Coding Tools
Grok 4.7 arrives in GitHub Copilot for agentic coding
GitHub Changeloghigh confidence
Why it matters
- →Grok 4.7 brings xAI's reasoning capabilities directly into GitHub Copilot, offering an alternative to OpenAI's models for complex coding tasks.
- →Support for agentic workflows allows developers to handle multistep projects more effectively within their IDEs.
- →Availability across all major IDEs and subscription tiers ensures broad access for both individual developers and enterprise teams.
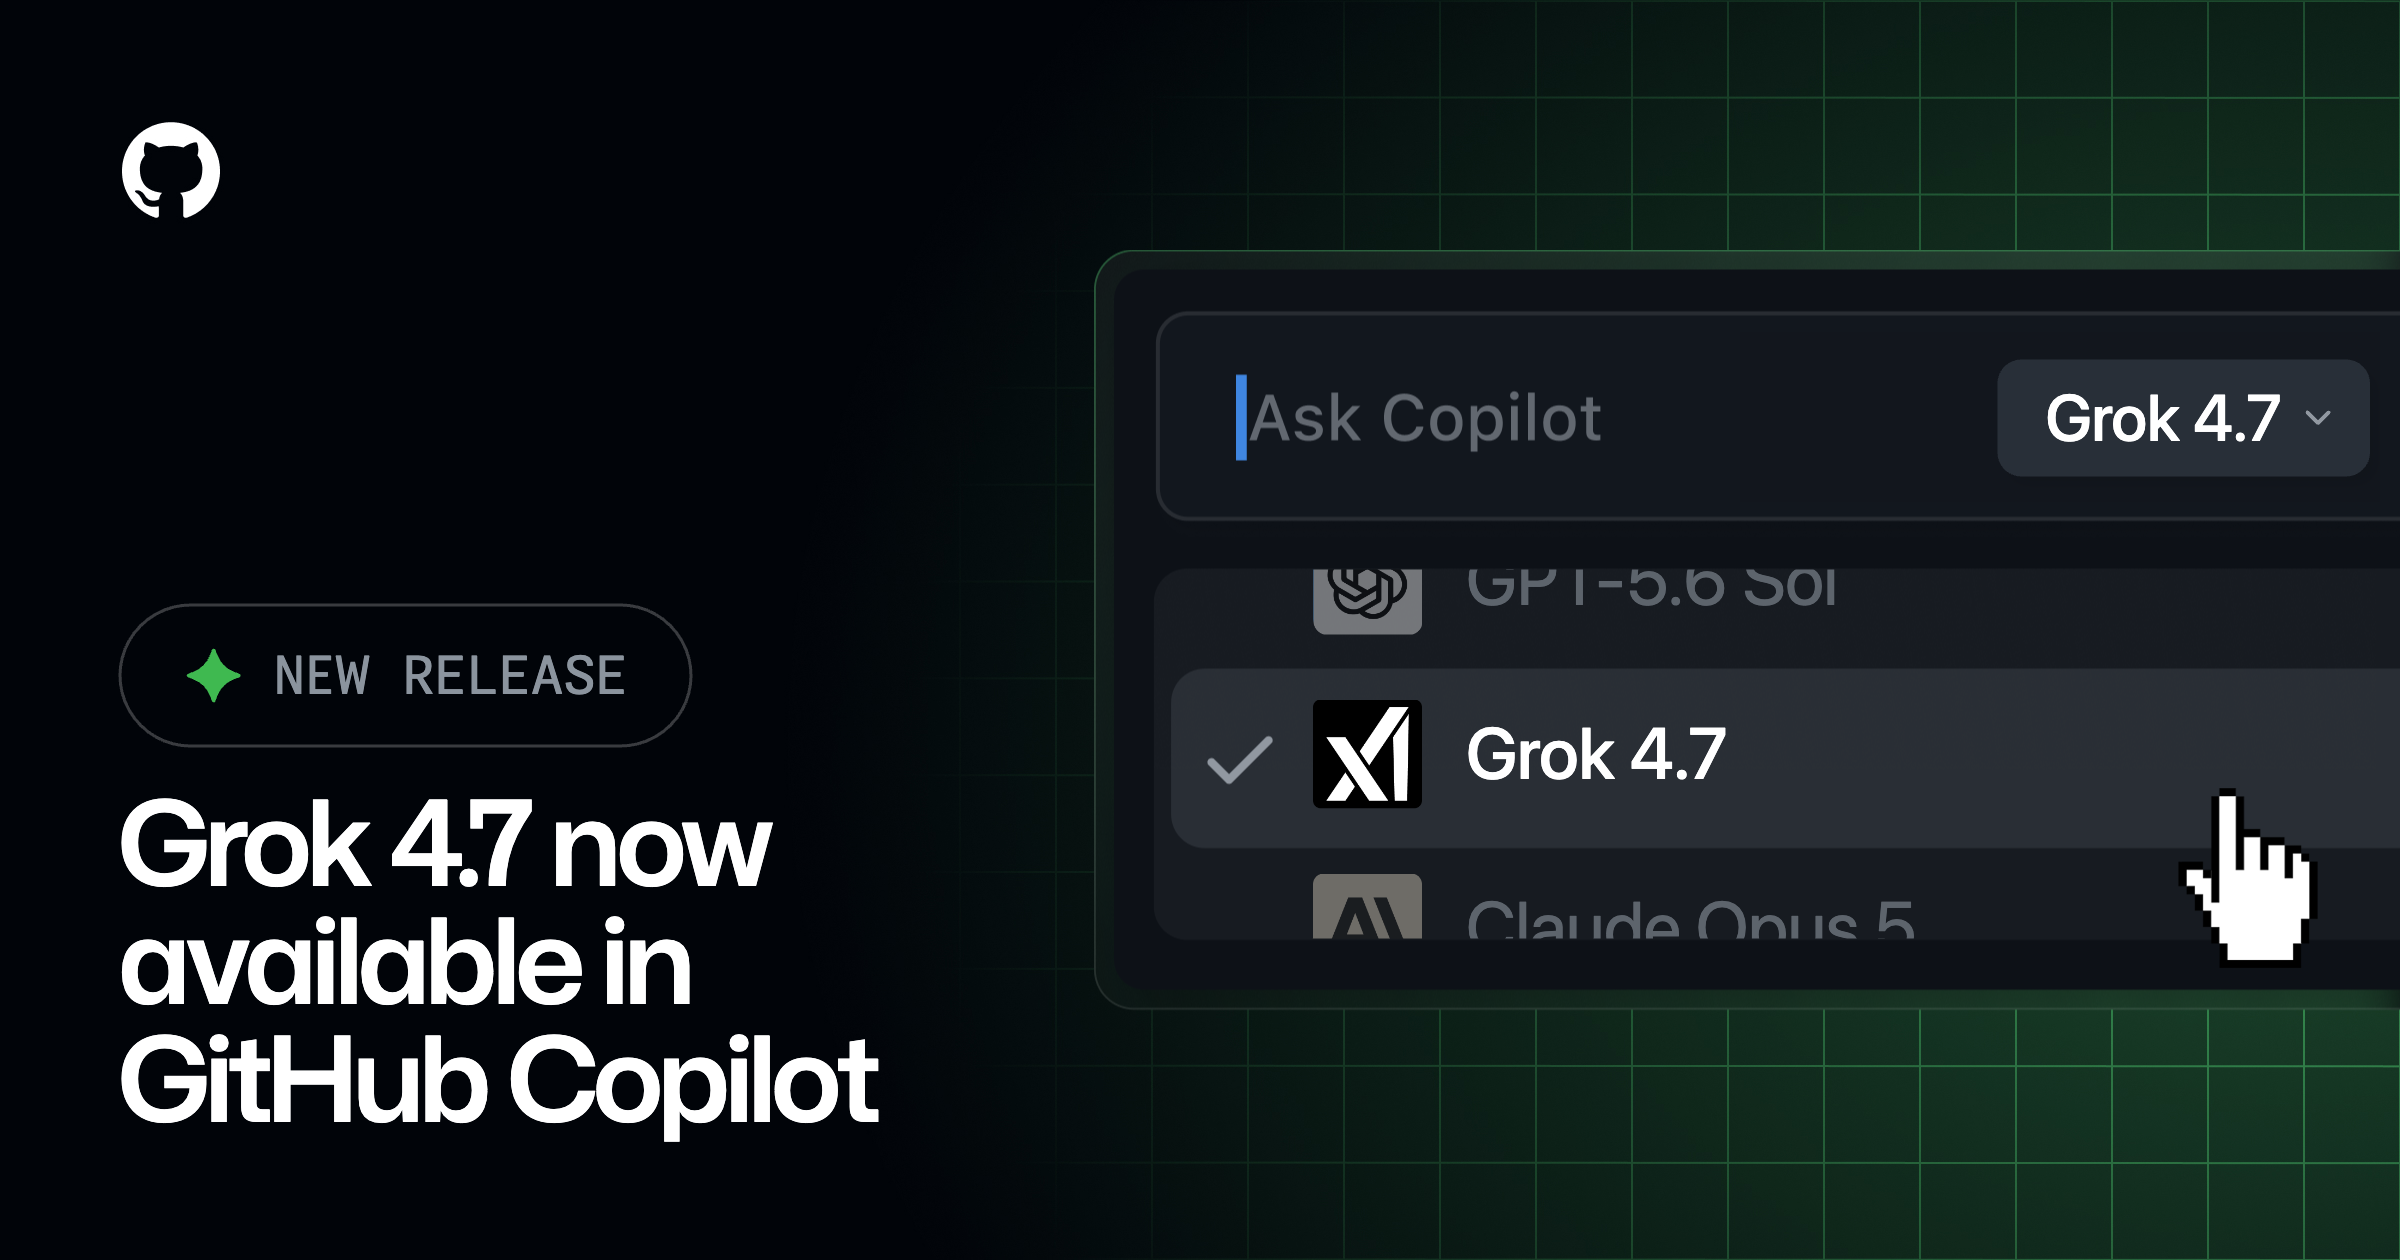
xAI has integrated its Grok 4.7 reasoning model into GitHub Copilot, expanding availability across Visual Studio Code, JetBrains, Xcode, and other supported IDEs. The model is designed specifically for agentic coding and complex, multistep workflows, building on the previous Grok 4.6 release. It is available to all Copilot subscription tiers, including Pro, Max, Business, and Enterprise plans, under standard usage-based billing. Administrators can manage access through existing model policy settings, with new models automatically enabled by default. The rollout is gradual, with full availability expected in the coming days.
Read originalMore from GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub PR page GA with bulk actions
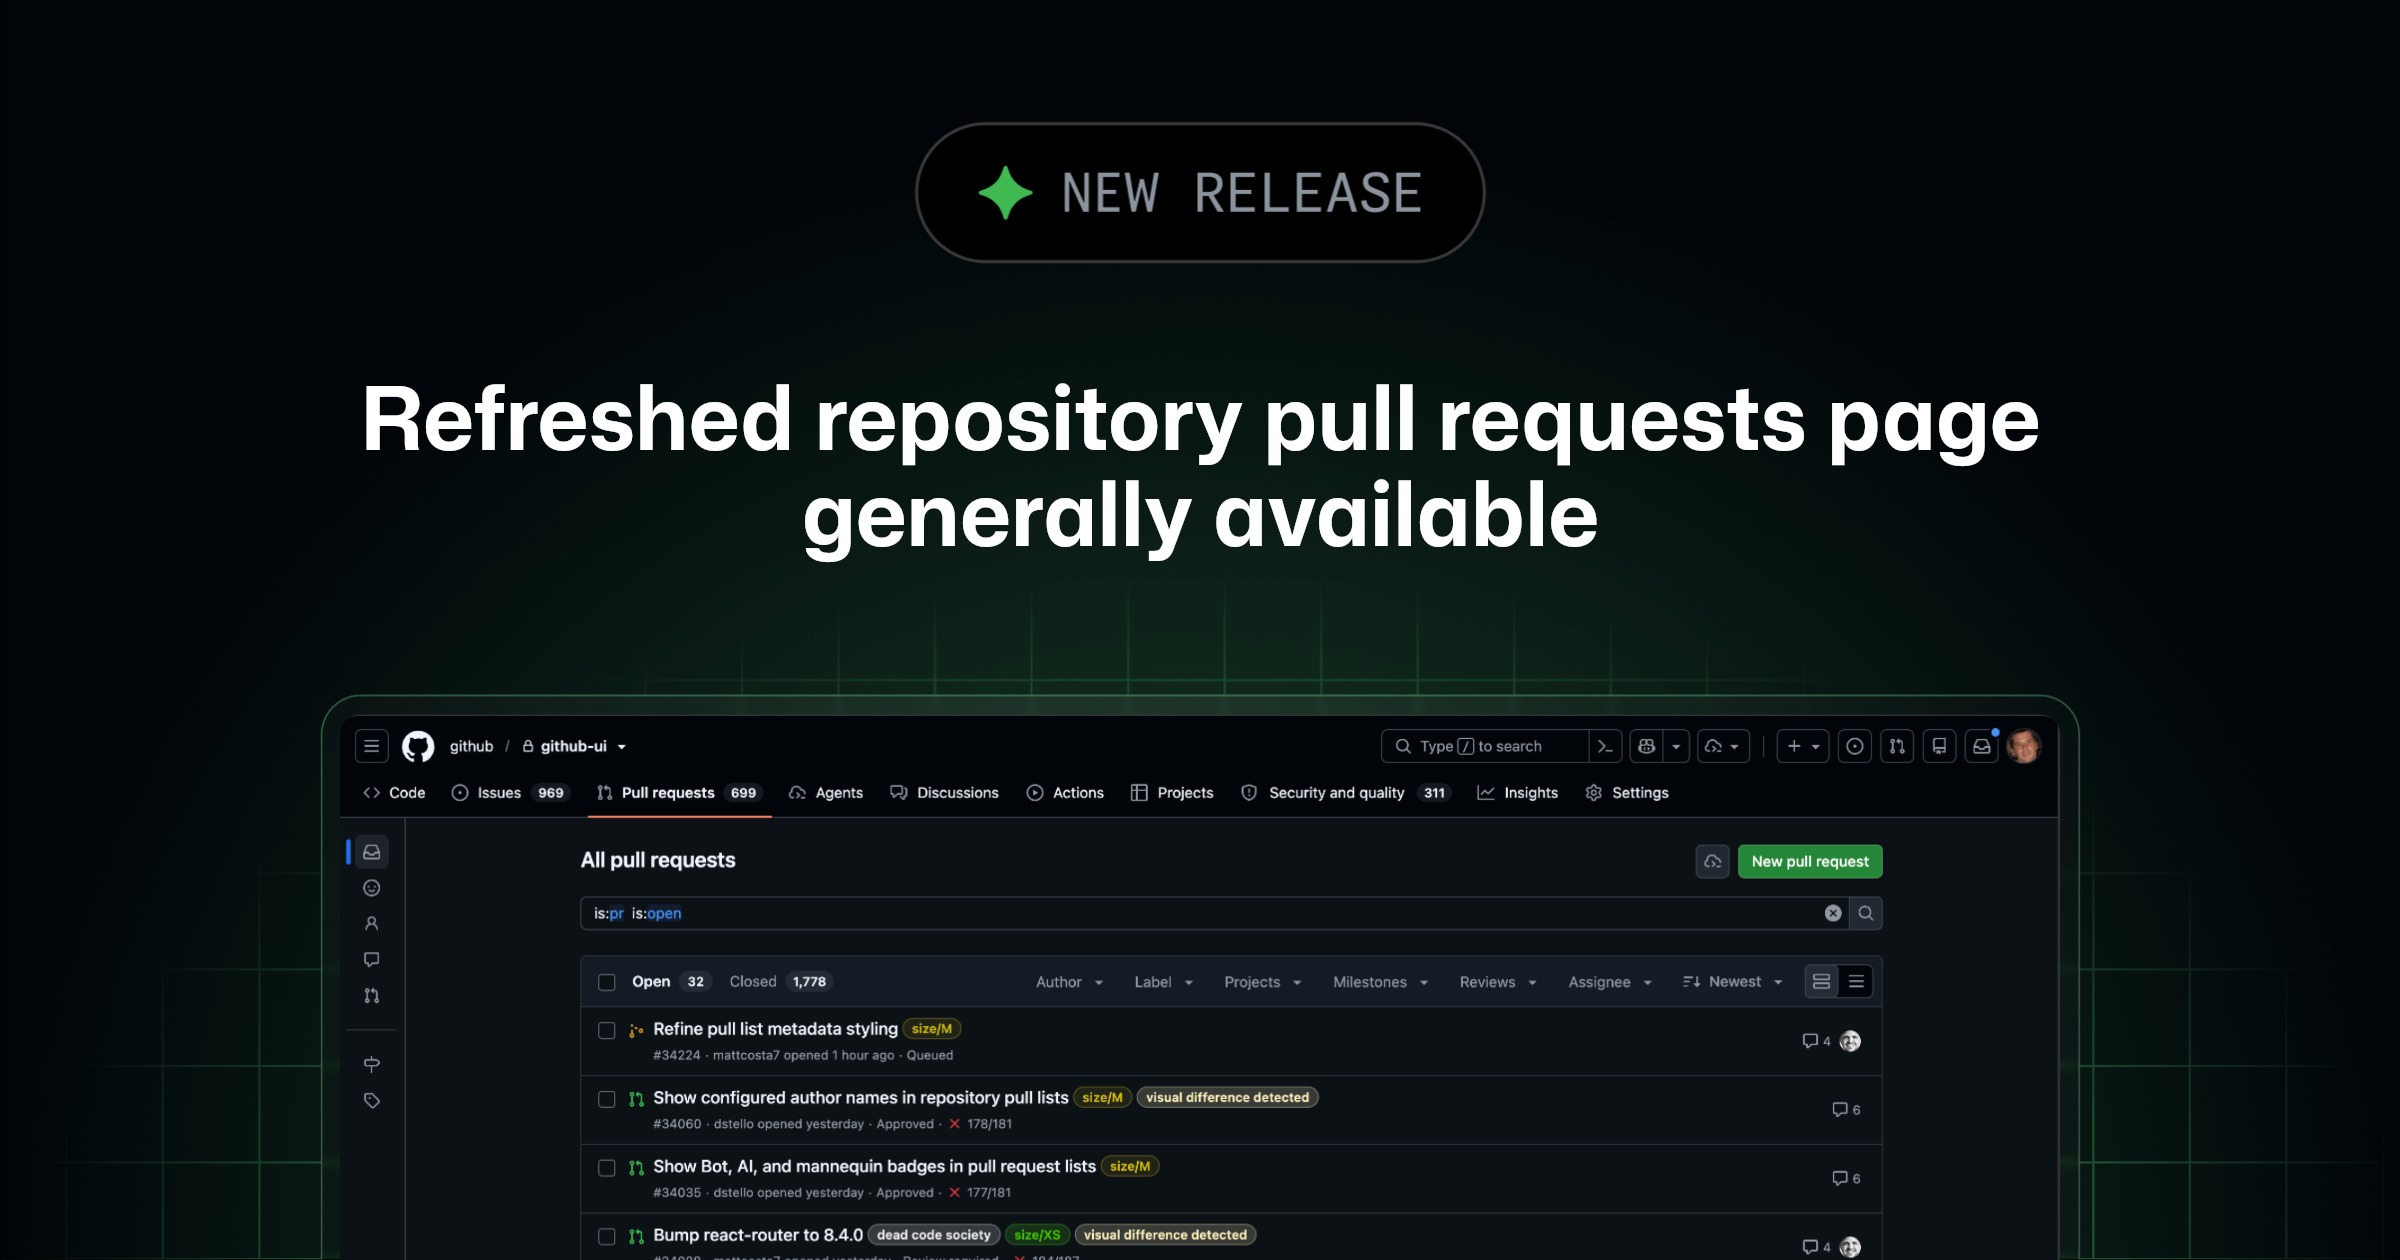
GitHub’s redesigned pull requests interface has moved from preview to general availability, shifting the focus from basic listing to active triage. The update brings bulk actions like closing or labeling multiple PRs simultaneously, a feature long requested by maintainers drowning in review queues. Advanced search now supports nested logic and AND/OR operators, while collapsible sidebars and compact modes help developers scan more context without endless scrolling. This isn't a new AI model, but it directly addresses the workflow bottleneck of code review management for millions of developers.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Enterprise adds credential inventory exports
GitHub finally gives enterprise admins a centralized view of every active credential across their organization. By exporting a complete inventory of SSH keys, tokens, and app permissions, security teams can instantly map their attack surface during an incident. This moves credential management from scattered manual checks to a single, auditable CSV or API endpoint. It’s a critical infrastructure upgrade for compliance and rapid response, closing a long-standing visibility gap in enterprise security operations.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Code Review GA with Auto-Resolution
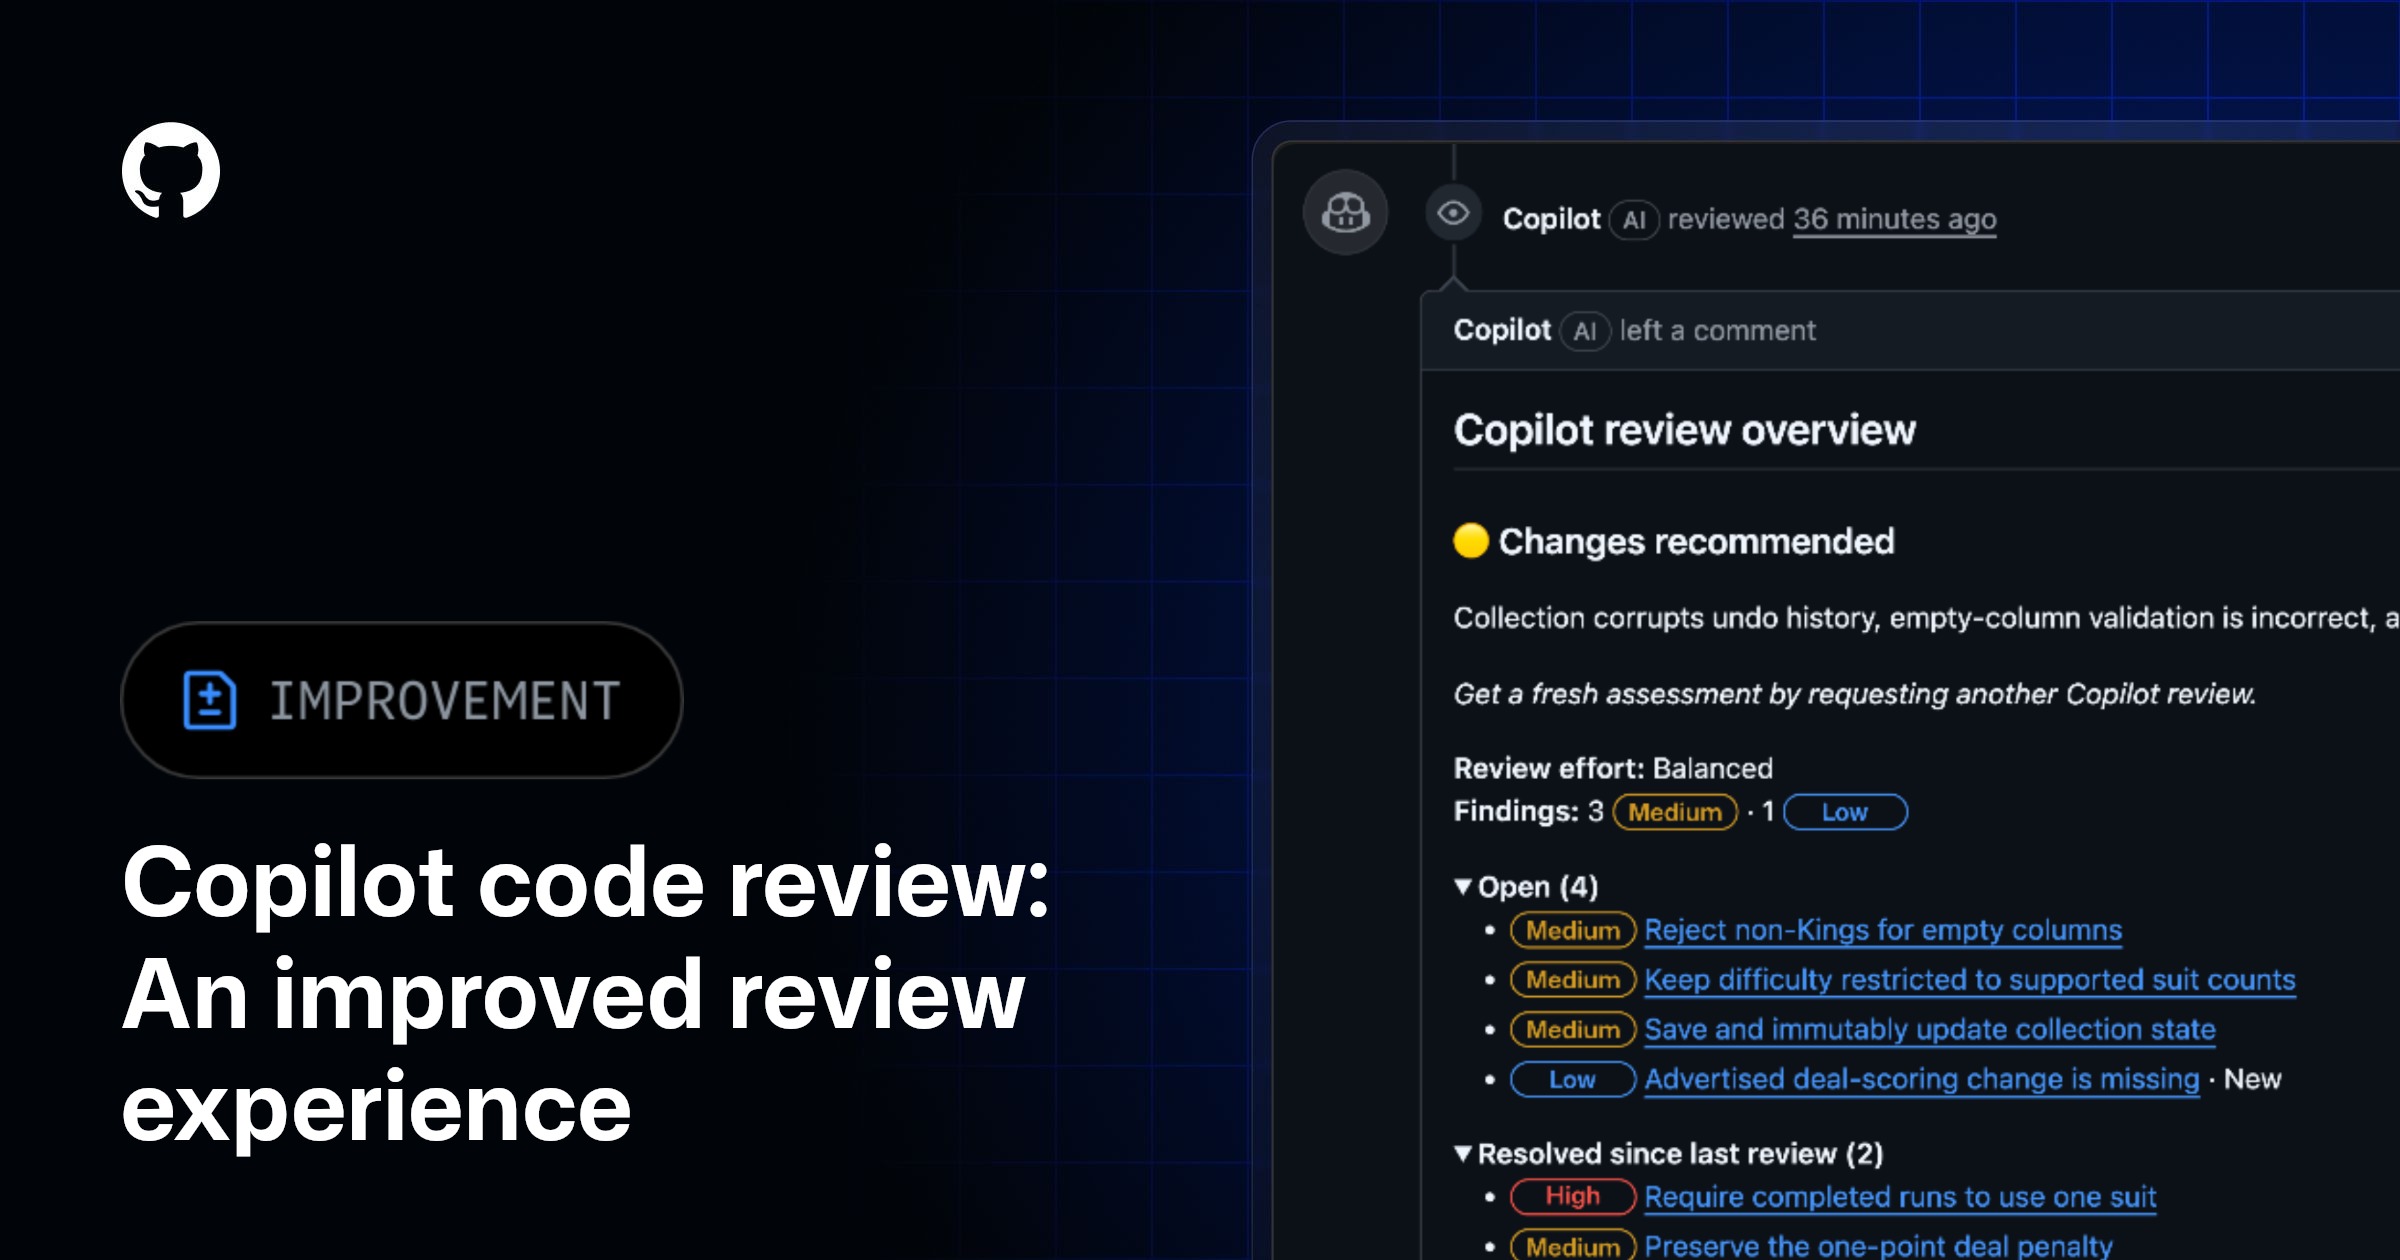
GitHub Copilot’s code review tool has reached general availability, shifting from experimental to a core part of the pull request workflow. The biggest leap is auto-resolution: Copilot now validates whether its own suggestions were actually fixed by subsequent commits and closes them out automatically, saving developers from manual cleanup. It also groups findings into clear states like 'Resolved' or 'Previously missed,' giving a real-time health check of the PR rather than just a static list of errors. This reduces context switching significantly, letting engineers focus on new issues while the AI handles the administrative burden of closing old ones.
GitHub Changelog
More in Coding Tools
Coding Toolscoding
llama.cpp adds env var control for server args
This release solves a real operational headache: configuring llama-server parameters like temperature and penalties via environment variables instead of command-line flags. By supporting LLAMA_ARG_* prefixes, it enables clean integration with systemd EnvironmentFile directives, making deployment on Linux servers significantly more robust and reproducible. The update also refreshes documentation using llama-gen-docs to keep the readme accurate. While no new inference engines are added, this is a practical step toward treating local LLM serving as standard infrastructure rather than a manual script.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11090 fixes CUDA Volta build
This release quietly repairs a regression in the CUDA backend that broke compilation on older Volta GPUs. By generalizing the tile shape logic in the load_ldmatrix kernel, the maintainers restored support for devices like the Tesla V100 without sacrificing newer architectures. It is a necessary patch for anyone running inference on legacy hardware, ensuring the codebase remains usable across the full spectrum of NVIDIA cards rather than drifting toward only the latest silicon.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11093 adds CUDA 13 and ROCm 10.0
This release quietly closes the hardware gap for local inference by adding default support for CUDA 13 and ROCm 10.0 alongside existing CUDA 12 builds. Users with newer NVIDIA GPUs or AMD accelerators no longer need to compile from source to get hardware acceleration, effectively making llama.cpp the universal runtime for consumer and enterprise AI chips. The simultaneous availability of both major driver stacks means developers can target the latest hardware without maintaining separate build pipelines. This standardization removes a significant friction point for anyone deploying models on modern, non-CUDA-12-only infrastructure.
llama.cpp Releases