Models & Labs
Reflection AI launches Beam open-weight model
The Rundown AIhigh confidence
Why it matters
- →Reflection AI enters the open-weight race with significant capital and DeepMind pedigree.
- →Beam targets efficiency gains over Chinese rivals like Z.ai's GLM-5.2.
- →Apache 2.0 licensing enables enterprise self-hosting for private data use cases.

Reflection AI, the $25 billion startup founded by former DeepMind researchers, has released Beam, its first public open-weight model for coding and agents. The company claims Beam achieves performance comparable to Z.ai’s GLM-5.2 while requiring significantly less computing power. Weights will be available under an Apache 2.0 license later this month, allowing organizations to self-host the model. Reflection is positioning Beam as a solution for enterprise 'AI factories' seeking to reduce dependency on Chinese open-source alternatives.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1GLM 5.2 Emerges as Leading Open Weights Model
Sam Witteveen · June 17, 2026 · Related
- 2Reflection AI Secures $6.3B Compute Deal with SpaceX
TechCrunch AI · June 22, 2026 · Related
- 3Reflection AI secures $1B compute deal with Nebius
TechCrunch AI · July 14, 2026 · Related
- 4China Challenges US AI Dominance with New Models
The Verge AI · July 20, 2026 · Related
- 5Chinese Open-Weight Models Spark U.S. Policy Debate
AI News · July 21, 2026 · Related
- 6Chinese AI Models Challenge Silicon Valley's Dominance
WIRED AI · July 22, 2026 · Related
- 7China's Open AI Models Challenge US Dominance
The Verge AI · July 27, 2026 · Related
- 8Chinese Labs Lead in Open Model Scale
Hugging Face Blog · August 14, 2026 · Related
What happened next
- 9Mistral releases new flagship model
Sifted · October 6, 2026 · Background
- 10MIT documents AI hardware evolution over eight years
MIT News AI · October 6, 2026 · Background
- 11ML-Intern: Autonomous AI Agent for Model Training
Hugging Face Blog · October 8, 2026 · Background
Follow this story
Open the full story →Reflection debuts Beam open-weight model
4 developments
- Oct 5 · TechCrunch AI
Reflection debuts Beam open-weight model - Oct 6 · The Rundown AI
Reflection AI launches Beam open-weight model (This article) - Oct 6 · The AI Daily Brief
Reflection AI Launches Open Model to Challenge US Dominance↳ The model aims to restore US leadership in open-source AI. - Oct 7 · The AI Daily Brief
Reflection AI Releases Beam Open Model
More from The Rundown AI

More in Models & Labs
Models & Labsmodels
llama.cpp b11535 release with ROCm 10 and CUDA 13
This release quietly cements llama.cpp as the universal inference runtime by adding default support for ROCm 10.0 and CUDA 13.4 across Linux and Windows. AMD GPU users finally get parity with NVIDIA's latest driver stack without manual configuration, while Apple Silicon KleidiAI builds are temporarily disabled to resolve stability issues. The inclusion of Snapdragon NPU support on Linux signals a serious push into edge AI hardware beyond just x86 and ARM CPUs. It is less about new features and more about ensuring the toolchain keeps pace with the rapidly evolving GPU landscape.
llama.cpp Releases
Models & Labscoding
llama.cpp b11540 adds ROCm 10 and CUDA 13 support
This release quietly closes the hardware gap for local inference by adding default builds for ROCm 10.0 and CUDA 13.4 across Linux and Windows. AMD users finally get parity with NVIDIA in the binary distribution, while CUDA 13 support future-proofs setups on newer drivers. The inclusion of Snapdragon and OpenVINO binaries further broadens the hardware surface area without requiring custom compilation. It is a pragmatic update that makes llama.cpp the most accessible runtime for diverse local AI hardware.
llama.cpp Releases
 © Lev Selector
Models & Labsmodels
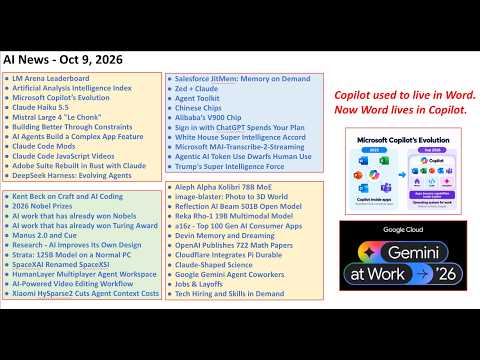
Mistral Large 4 and Claude Haiku 5.5 Released
Mistral releases Large 4 'Le Chonk' while Anthropic launches Claude Haiku 5.5, continuing the trend of cheaper, faster frontier models.
Lev Selector