Coding Tools
GitHub Copilot Code Review API and UI updates
GitHub Changeloghigh confidence
Why it matters
- →API access enables automated governance of code review policies in enterprise CI/CD pipelines.
- →Explicit attribution fields allow developers to trace which models or tools generated specific comments.
- →Improved bot handling and retry logic reduce friction for automated pull requests from GitHub Actions.
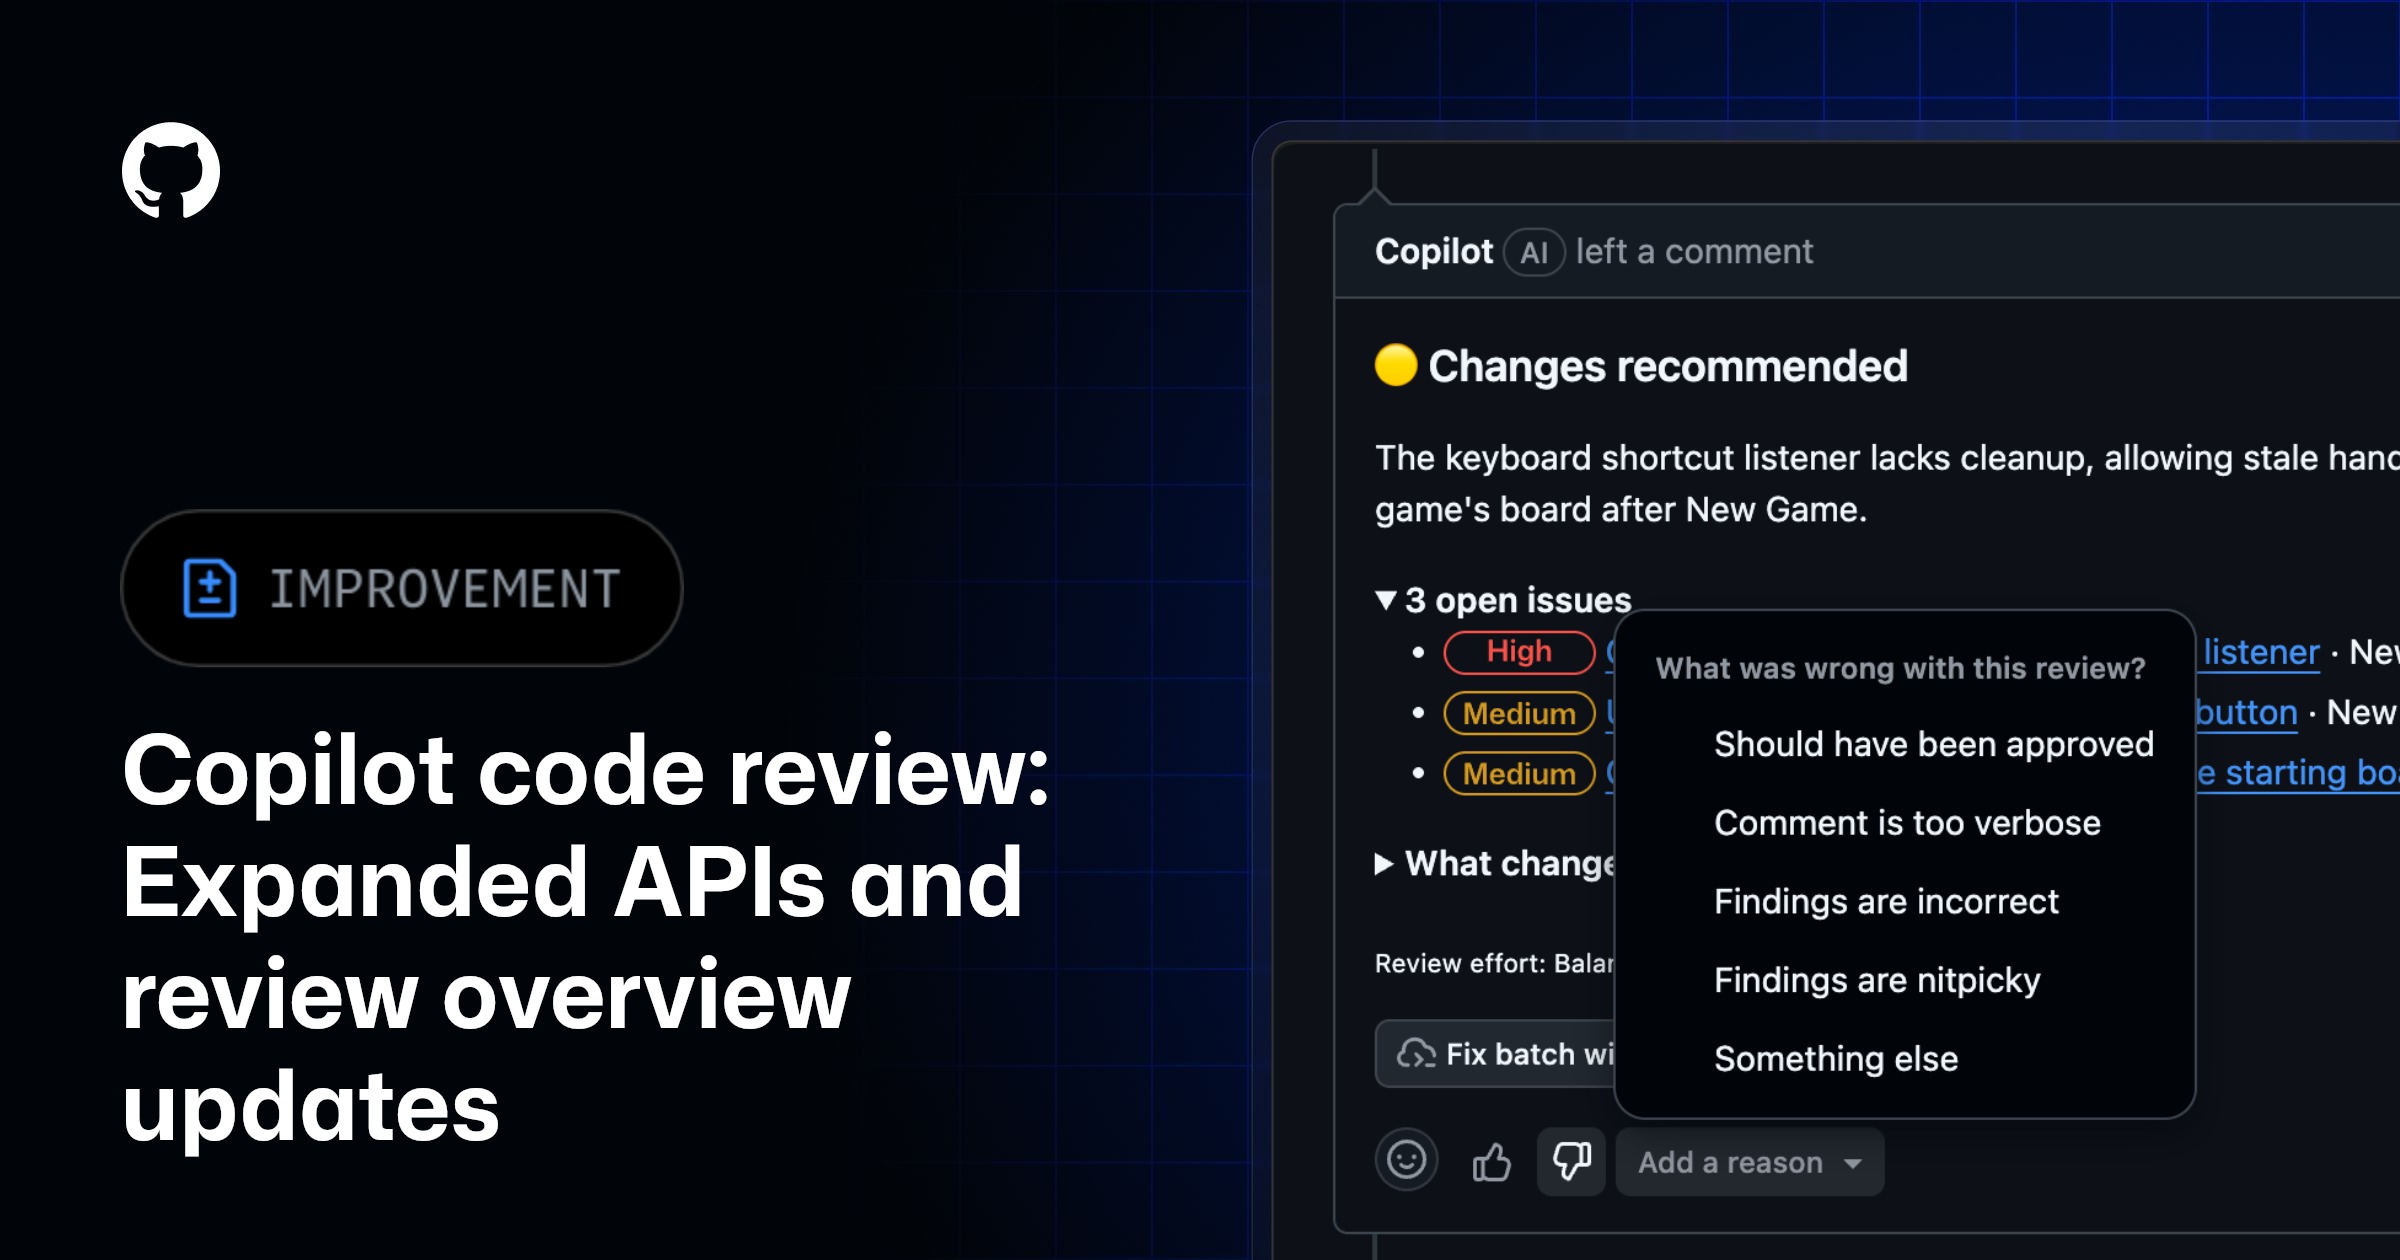
GitHub has expanded its Copilot code review capabilities by adding API management for settings across enterprise, organization, and repository levels. The update allows administrators to programmatically control review effort, enablement, and custom instructions via REST and GraphQL endpoints. Additionally, the platform introduced UI improvements including compact review overviews, explicit attribution of AI sources such as MCP servers, and enhanced reliability features like automatic retries for failed reviews. These changes are available to Copilot Pro, Business, and Enterprise plans.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1GitHub Copilot Expands Code Review Capabilities
GitHub Changelog · August 27, 2026 · Same story
- 2GitHub Copilot Code Review API and Default Effort Change
GitHub Changelog · October 2, 2026 · Same story
Follow this story
Open the full story →GitHub Copilot integrates into Xcode native assistant
3 developments
- Nov 4 · GitHub Changelog
GitHub Copilot integrates into Xcode native assistant - Nov 6 · GitHub Changelog
Copilot expands to JetBrains Air and Xcode↳ Copilot expands to JetBrains Air alongside its new Xcode integration. - Nov 7 · GitHub Changelog
GitHub Copilot Code Review API and UI updates (This article)↳ GitHub exposes Copilot code review config to REST and GraphQL APIs for enterprise automation and adds UI refinements like explicit AI attrib
More from GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Dashboard Adds Chat and Agent Metrics
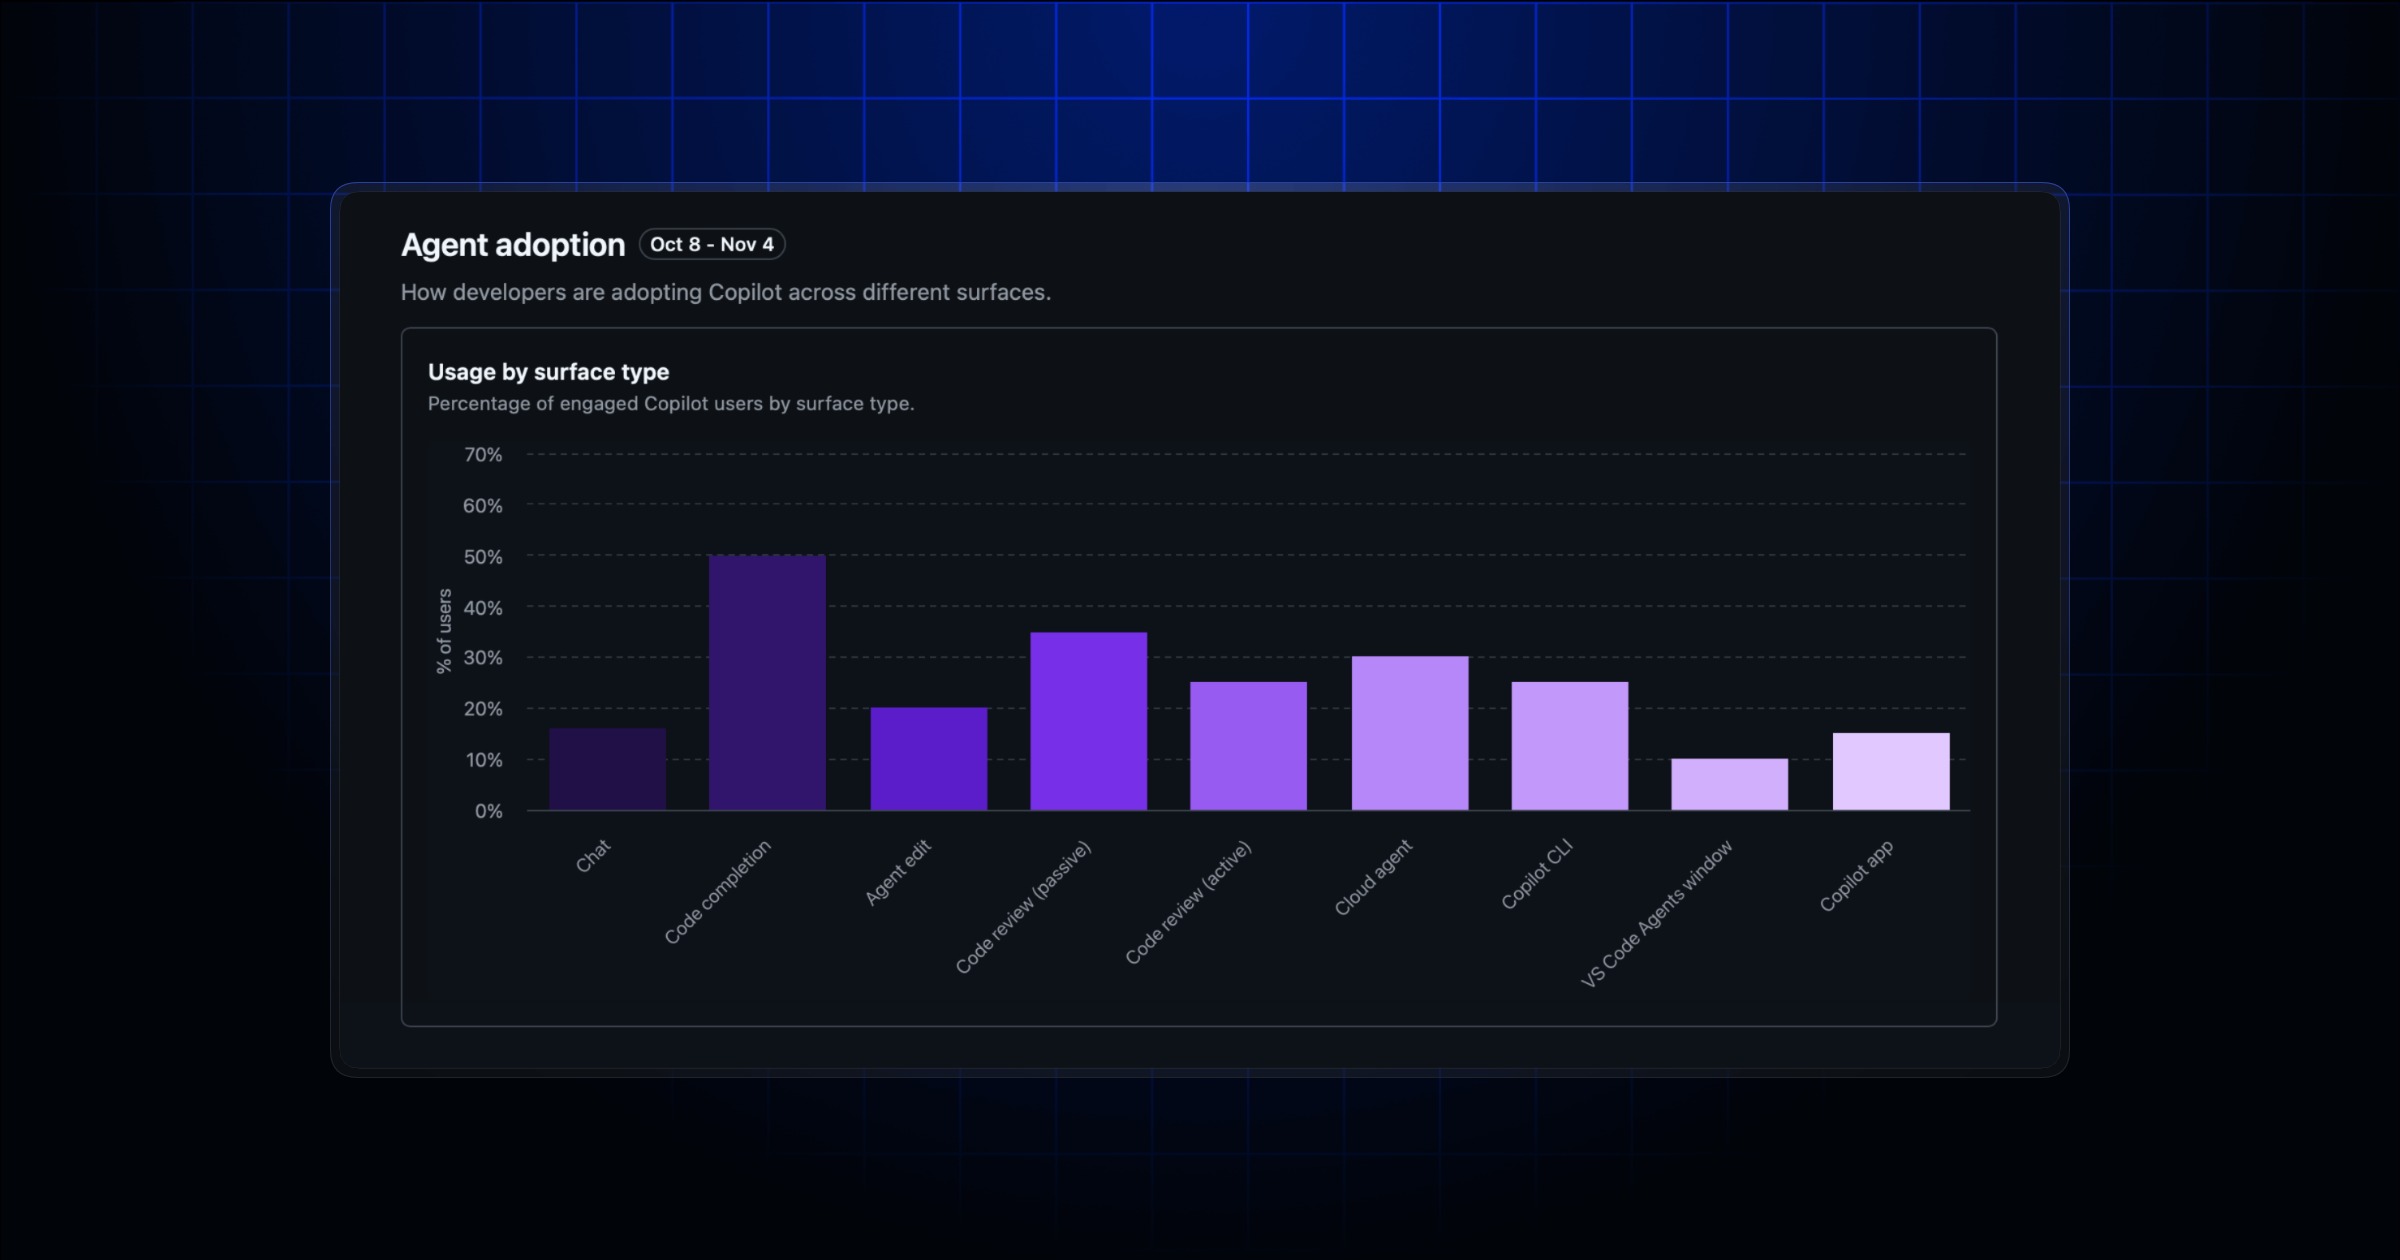
GitHub finally stops treating chat as a passive afterthought in its enterprise analytics. By adding Copilot Chat and the VS Code Agents window to the impact dashboard, the platform now tracks nine distinct experiences instead of just seven. The rebranding of 'Passive users' to 'Chat-first users' is a semantic correction that aligns metrics with actual developer behavior rather than arbitrary adoption thresholds. This gives engineering leaders a complete picture of how AI is actually being used across their codebases, closing the visibility gap between typing commands and writing code.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
Copilot expands to JetBrains Air and Xcode
GitHub Copilot is aggressively expanding its footprint beyond VS Code, landing in JetBrains Air and Xcode’s native assistant. This move signals a shift from IDE-specific plugins to a broader platform strategy, allowing developers to use their existing subscription across major ecosystems. The release also refines agent workflows with direct PR merging and remote preview capabilities, reducing context-switching for complex tasks. While the core AI engine remains unchanged, the integration depth in Xcode and JetBrains marks a significant step toward universal coding assistance.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Chat GA in Slack and Teams
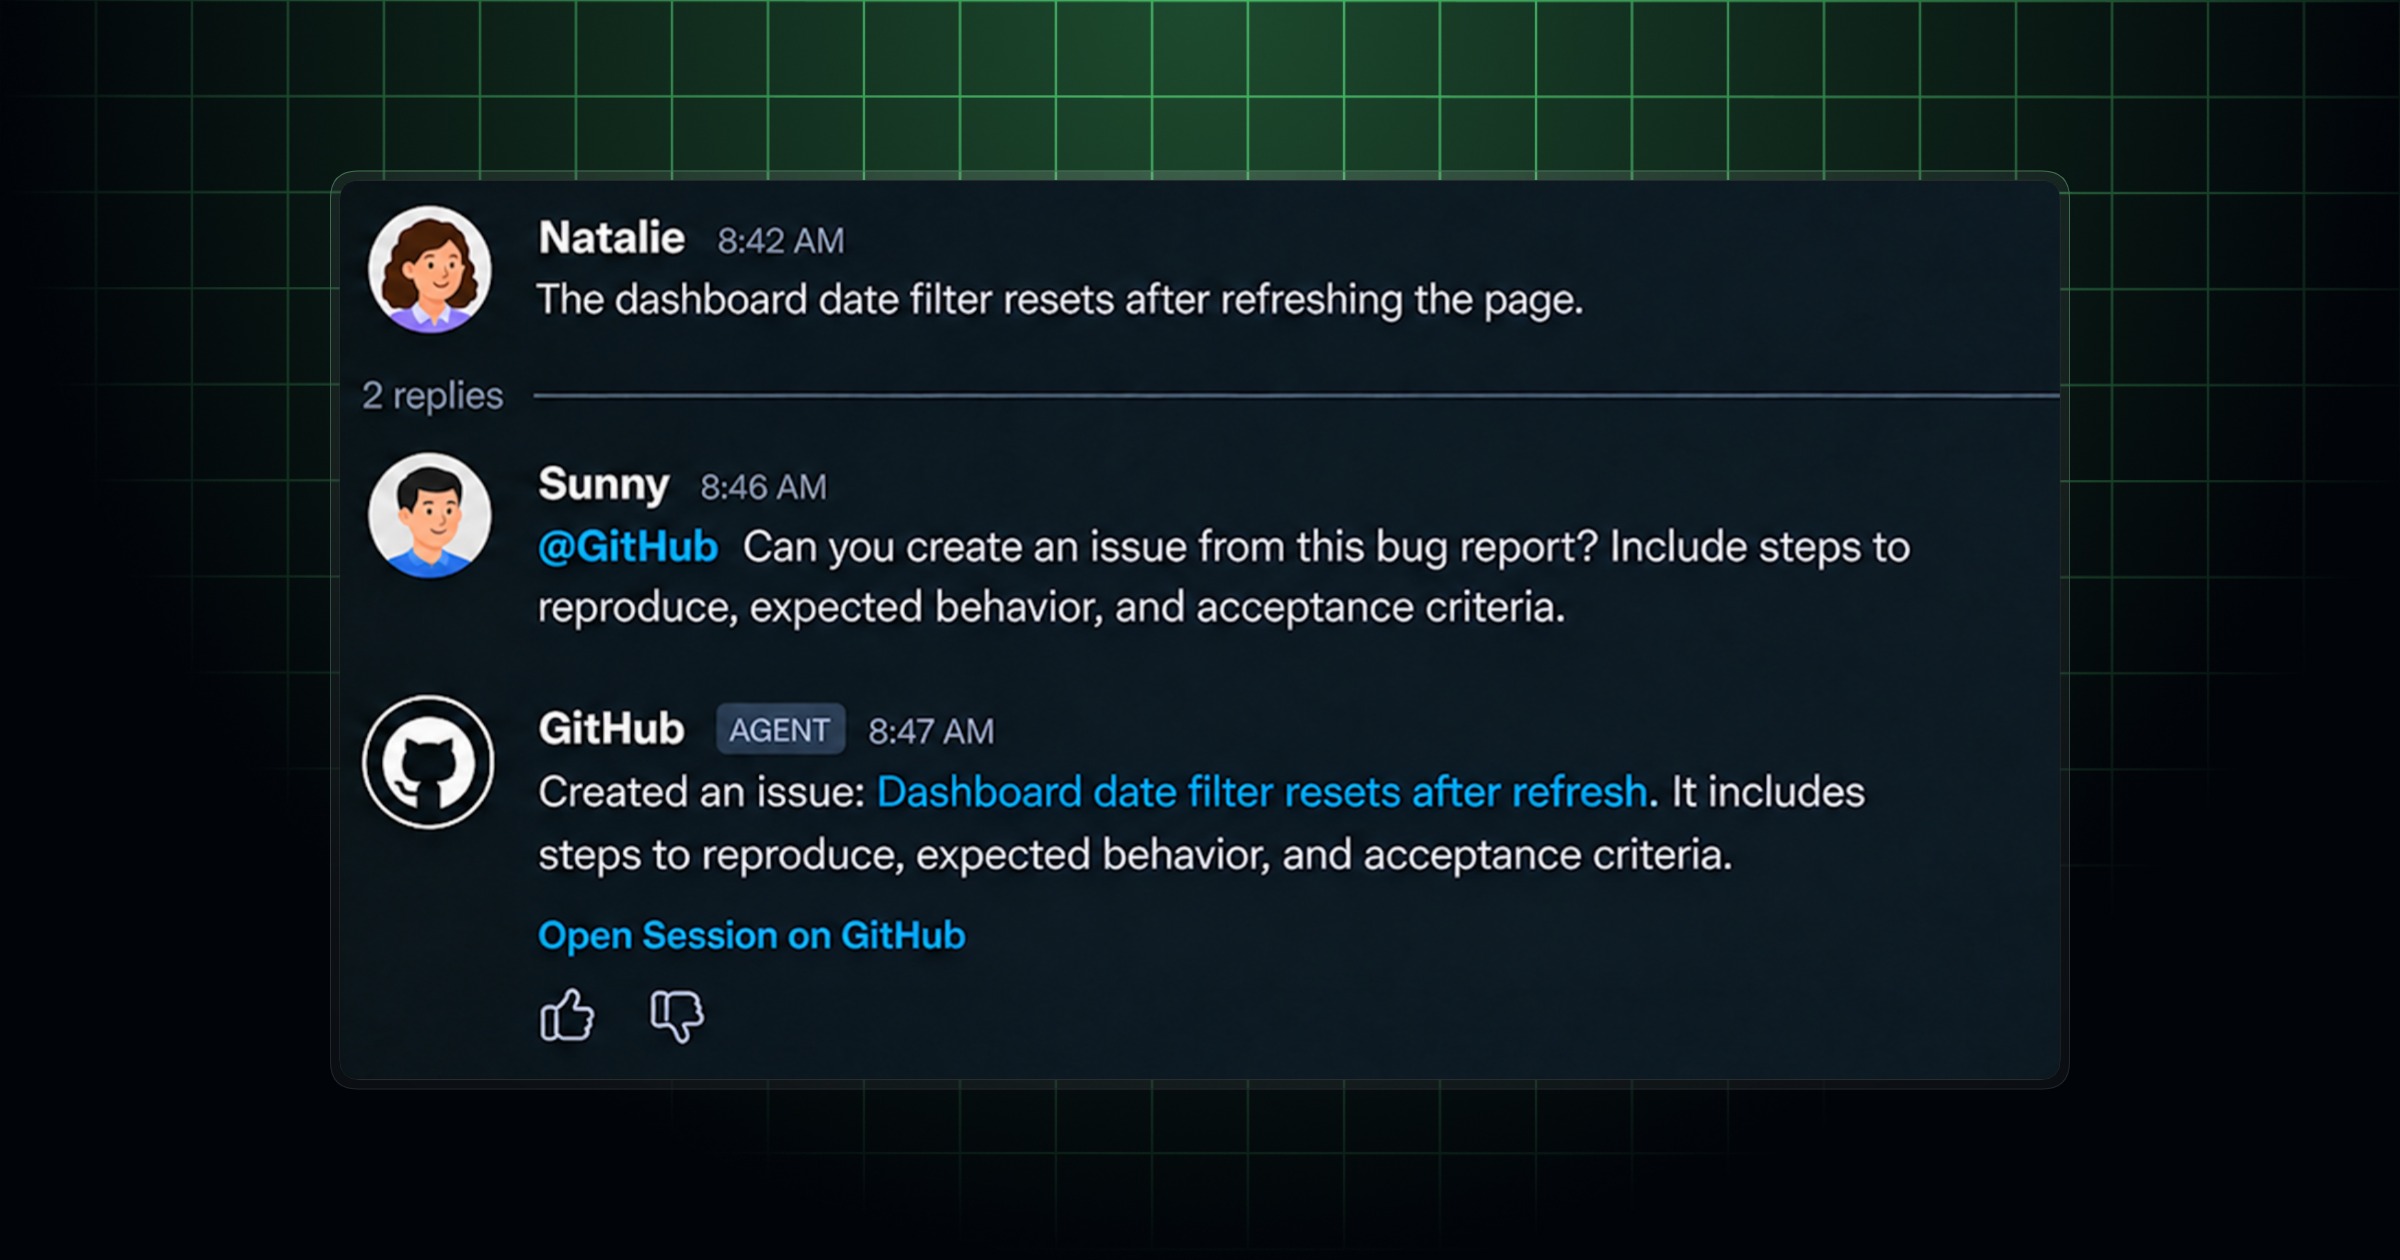
GitHub has finally moved its conversational AI assistant out of beta for Slack and Microsoft Teams, closing a major gap in developer workflow integration. The update isn't just about presence; it now auto-detects repositories from chat context, removing the friction of manual selection that plagued early versions. Crucially, it bridges the gap between discussion and execution by allowing users to create issues and pull requests directly within the thread, with clear attribution linking back to the conversation. This shifts AI coding assistance from a sidecar tool to an embedded part of daily team communication.
GitHub Changelog
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.319: MCP backgrounding and gateway controls
This release finally brings proper asynchronous handling to Model Context Protocol tasks, allowing Claude Code to offload long-running tool calls to the background instead of blocking the main thread. For enterprise users, the new pooled budget rules and JSON logging make the Claude apps gateway significantly more manageable for large teams. The update also tightens error reporting in auto mode, ensuring developers get clear reasons when actions are denied rather than silent failures. It’s a pragmatic patch that improves reliability for complex agent workflows.
Claude Code Releases
Coding Toolscoding
llama.cpp b12173 adds OpenCL repeat ops
This release quietly patches a gap in llama.cpp's OpenCL backend by adding support for the 'repeat' operation across f16, i32, i16, and bf16 types. For users relying on AMD or Intel GPUs via OpenCL rather than Vulkan or ROCm, this means fewer fallbacks to slower CPU execution for models that use these tensor operations. It’s a targeted fix that improves stability and performance on non-NVIDIA hardware without changing the core inference engine. The update also includes standard binaries for CUDA 13 and ROCm 10.0, keeping the stack current with latest driver ecosystems.
llama.cpp Releases
Coding Toolscoding
llama.cpp b12174 adds ROCm 10 and CUDA 13
This release quietly closes the hardware gap for non-NVIDIA users by adding default support for ROCm 10.0 on both Linux and Windows, allowing AMD GPU owners to run local models without complex configuration. It also brings CUDA 13.5 builds to Ubuntu and Windows, future-proofing the toolchain for newer NVIDIA architectures while maintaining backward compatibility with CUDA 12. Apple Silicon KleidiAI is disabled in this build, a notable regression for Mac users who rely on that specific optimization. The update solidifies llama.cpp's position as the most versatile inference runtime available, covering everything from Snapdragon NPUs to Intel Arc via SYCL.
llama.cpp Releases