Coding Tools
llama.cpp b12173 adds OpenCL repeat ops
llama.cpp Releaseshigh confidence
Why it matters
- →Fixes OpenCL backend gaps for non-NVIDIA GPU users, reducing CPU fallbacks.
- →Updates CUDA and ROCm library versions to latest stable releases (13.5/10.0).
- →Maintains llama.cpp's position as the most compatible local inference runtime.
llama.cpp has released version b12173, primarily focused on expanding OpenCL backend capabilities. The key technical change is the addition of 'repeat' operation support for f16, i32, i16, and bf16 data types, addressing previous limitations in tensor manipulation for OpenCL devices. This update ensures broader compatibility with models requiring these specific operations on AMD and Intel GPUs. Standard builds are also updated to include CUDA 13.5 libraries and ROCm 10.0 support across Linux and Windows platforms.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1llama.cpp b10657 Release Expands Platform Support
llama.cpp Releases · August 28, 2026 · Same story
- 2llama.cpp b11740 adds OpenCL i32 support
llama.cpp Releases · October 20, 2026 · Same story
More from llama.cpp Releases
Coding Toolscoding
llama.cpp b12174 adds ROCm 10 and CUDA 13
This release quietly closes the hardware gap for non-NVIDIA users by adding default support for ROCm 10.0 on both Linux and Windows, allowing AMD GPU owners to run local models without complex configuration. It also brings CUDA 13.5 builds to Ubuntu and Windows, future-proofing the toolchain for newer NVIDIA architectures while maintaining backward compatibility with CUDA 12. Apple Silicon KleidiAI is disabled in this build, a notable regression for Mac users who rely on that specific optimization. The update solidifies llama.cpp's position as the most versatile inference runtime available, covering everything from Snapdragon NPUs to Intel Arc via SYCL.
llama.cpp Releases
Coding Toolscoding
llama.cpp b12175 fixes CI hangs, adds ROCm 10 and CUDA 13
This release stabilizes the build pipeline by fixing a threading bug that caused test hangs on self-hosted runners, ensuring more reliable binaries for everyone. More importantly, it brings first-class support for ROCm 10.0 and CUDA 13 across Linux and Windows, closing the gap with NVIDIA's latest driver stacks. AMD users finally get parity with CUDA builds without manual configuration tweaks. The update also expands Apple Silicon coverage to include KleidiAI, though it remains disabled by default in this build. It’s a maintenance-heavy release that quietly modernizes the backend support matrix.
llama.cpp Releases
Coding Toolscoding
llama.cpp b12176 fixes C++ math compatibility
This release quietly patches a compilation failure on NetBSD by qualifying C math functions with std::, ensuring llama.cpp builds cleanly across stricter C++ environments. The change also corrects a subtle precision issue in test-quantize-fns.cpp where sqrtf was used with double accumulators, now switched to std::sqrt for better accuracy. While the behavioral difference is negligible for inference, this cleanup prevents future build breaks on non-standard Linux distributions and reinforces the project's commitment to portable, standards-compliant code.
llama.cpp Releases
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.319: MCP backgrounding and gateway controls
This release finally brings proper asynchronous handling to Model Context Protocol tasks, allowing Claude Code to offload long-running tool calls to the background instead of blocking the main thread. For enterprise users, the new pooled budget rules and JSON logging make the Claude apps gateway significantly more manageable for large teams. The update also tightens error reporting in auto mode, ensuring developers get clear reasons when actions are denied rather than silent failures. It’s a pragmatic patch that improves reliability for complex agent workflows.
Claude Code Releases
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Code Review API and UI updates
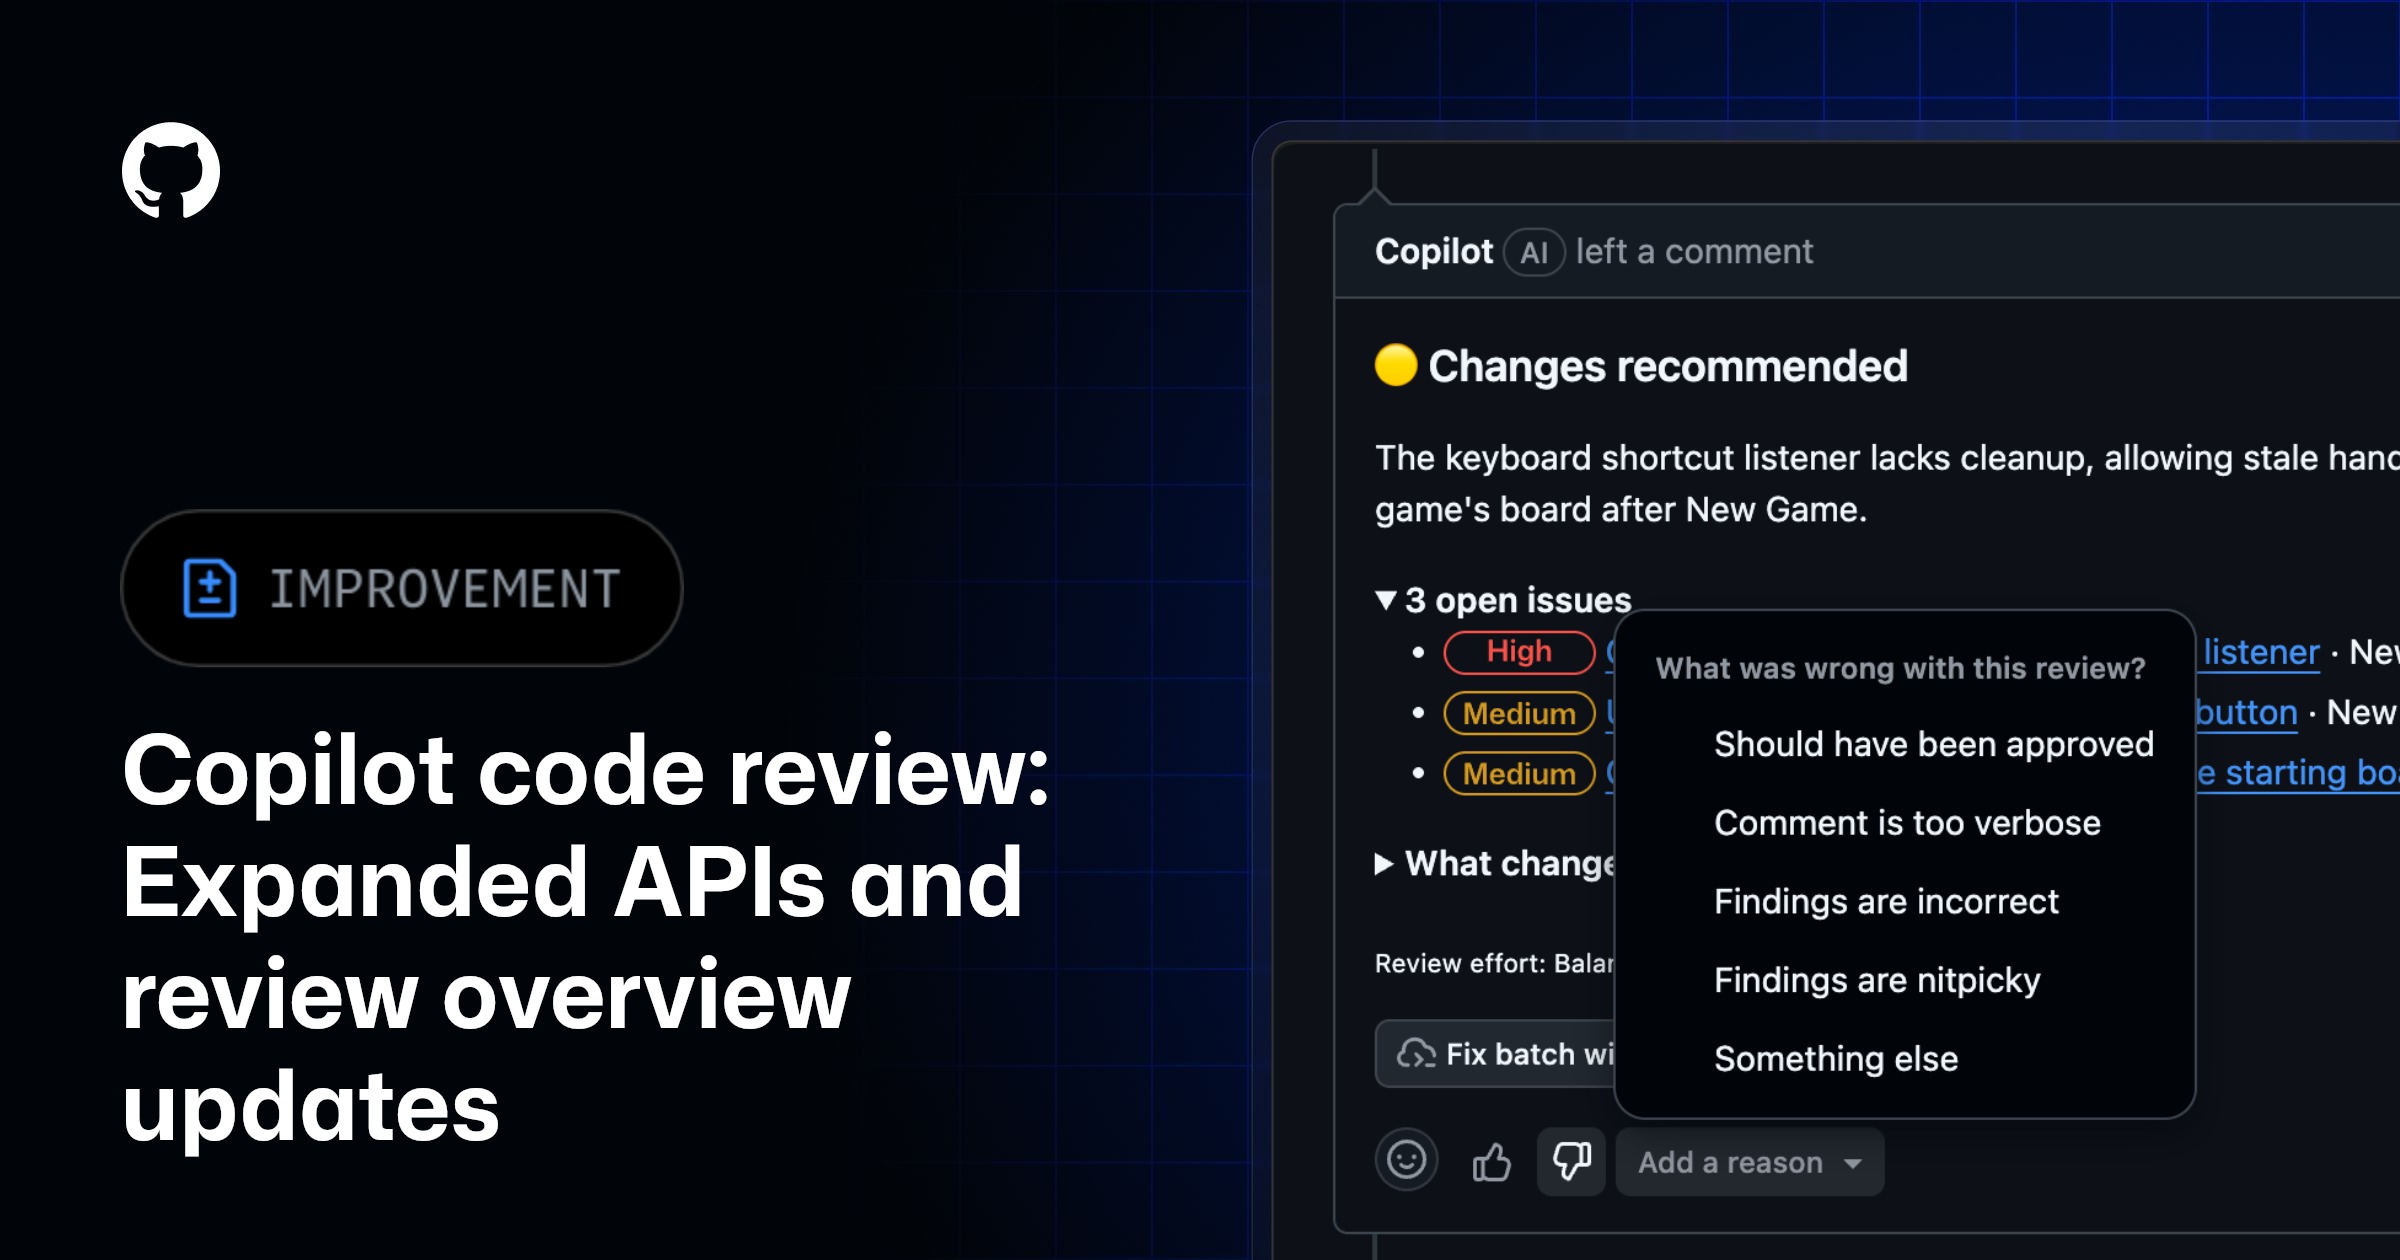
GitHub is finally exposing Copilot code review configuration to the REST and GraphQL APIs, closing a major gap for enterprise automation. Administrators can now programmatically control review effort, enablement, and custom instructions across organizations and repositories, moving beyond manual web interface tweaks. The update also refines the user experience with compact overviews, explicit attribution of AI sources like MCP servers, and better handling of bot-authored PRs. This shift makes Copilot Review a first-class citizen in CI/CD pipelines rather than just a UI feature.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Dashboard Adds Chat and Agent Metrics
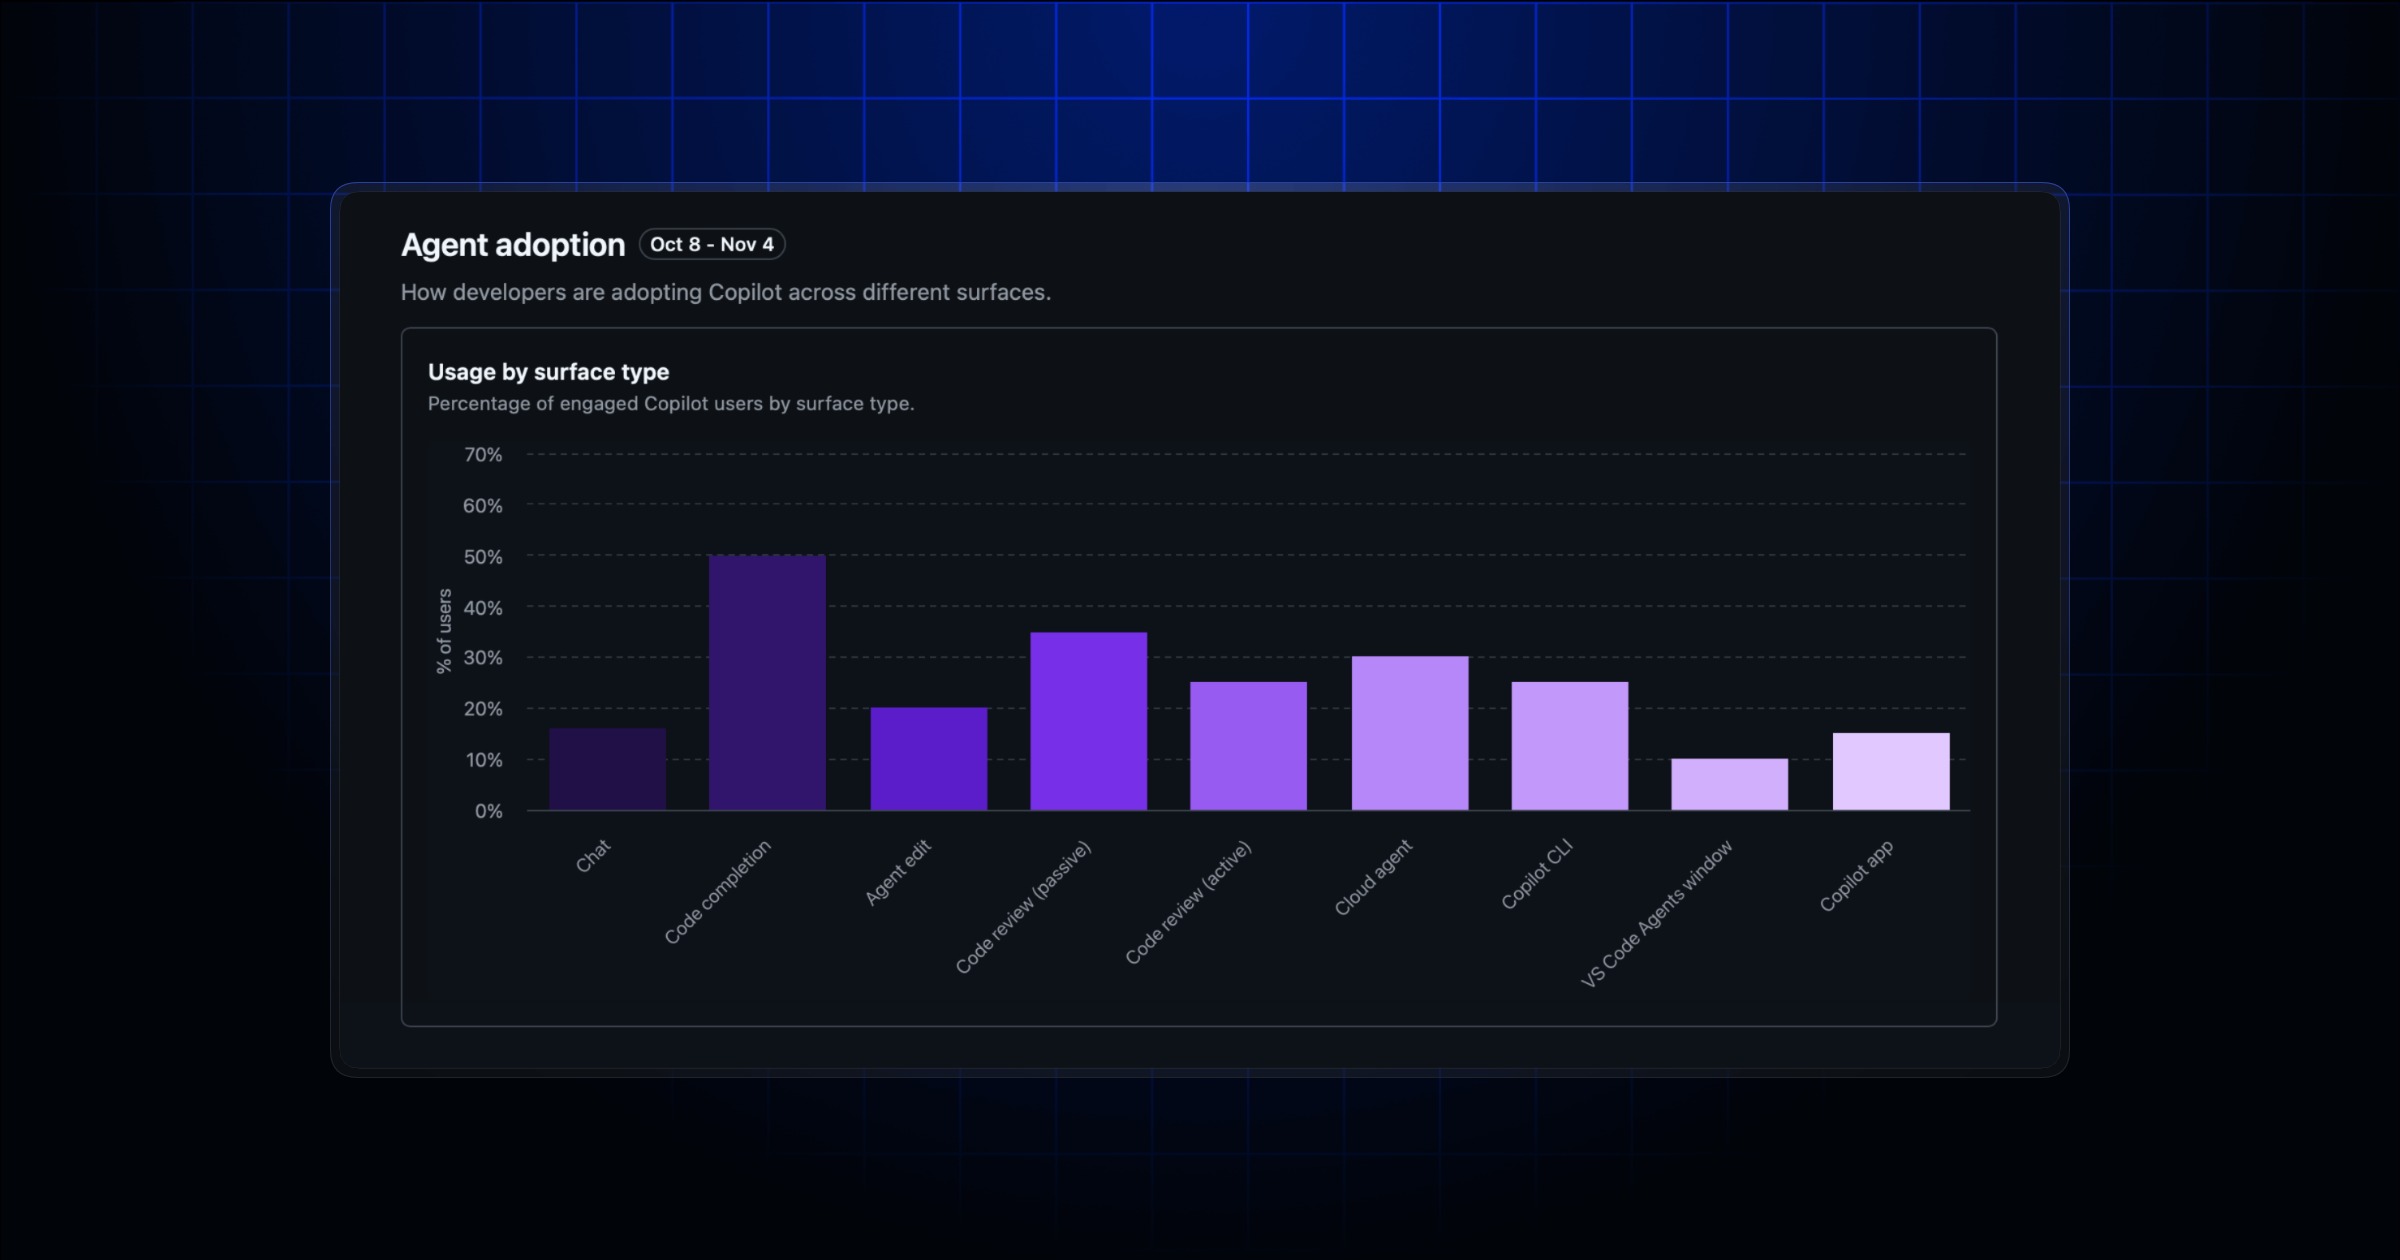
GitHub finally stops treating chat as a passive afterthought in its enterprise analytics. By adding Copilot Chat and the VS Code Agents window to the impact dashboard, the platform now tracks nine distinct experiences instead of just seven. The rebranding of 'Passive users' to 'Chat-first users' is a semantic correction that aligns metrics with actual developer behavior rather than arbitrary adoption thresholds. This gives engineering leaders a complete picture of how AI is actually being used across their codebases, closing the visibility gap between typing commands and writing code.
GitHub Changelog