Research
Physics-based pruning beats heuristics for LLM compression
Hugging Face Bloghigh confidence
Why it matters
- →Physics-based optimization captures layer interactions that heuristic pruning misses, yielding higher accuracy at deep compression levels.
- →The method uses a one-time Hessian calculation to evaluate billions of configurations cheaply, avoiding per-candidate benchmarking.
- →It demonstrates practical utility for quantum-inspired solvers in AI model compression tasks.

Multiverse AI has published research demonstrating that treating LLM block removal as a constrained binary optimization problem significantly outperforms traditional heuristics. By modeling transformer blocks as spins in an Ising glass, the method accounts for pairwise interactions between layers using a Hessian matrix derived from a small calibration dataset. In tests on Llama-3.3-70B-Instruct, this physics-based approach achieved nearly 23 percentage points higher MMLU scores than competing block-removal methods at 50% compression. The technique leverages classical and quantum-inspired solvers to find optimal pruning configurations without requiring expensive retraining for every candidate.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1DataCurve's DeepSWE Benchmark Reveals Coding Task Gaps
The AI Daily Brief · May 29, 2026 · Background
- 2Together AI Hosts MiniMax M3 for Efficient Inference
Together AI Blog · June 2, 2026 · Background
- 3Google DeepMind unveils DiffusionGemma for faster text generation
Google DeepMind · June 10, 2026 · Background
- 4Together AI Introduces Autoscaling for LLM Inference
Together AI Blog · July 31, 2026 · Background
- 5Efficient Knowledge Distillation for Large Language Models
Hugging Face Blog · August 10, 2026 · Background
- 6GLM 5.3 Flash: Z.AI's Cost-Efficient Model Variant
Sam Witteveen · August 30, 2026 · Background
- 7PrismML compresses LLMs to run locally with minimal loss
TechCrunch AI · September 17, 2026 · Background
What happened next
- 8llama.cpp v0.7.0: MoE caching and speculative decoding advances
llama.cpp Releases · October 16, 2026 · Background
- 9llama.cpp fixes 4D tensor quantization for MoE models
llama.cpp Releases · October 26, 2026 · Background
- 10WorldParticle unifies physics simulation with single AI model
MIT News AI · November 9, 2026 · Background
- 11HOPE: Second-Order Pruning for MoE Efficiency
Hugging Face Blog · November 9, 2026 · Related
- 12NVIDIA NemotronBolt 74B-A9B runs at 2-bit
Sam Witteveen · November 9, 2026 · Background
More from Hugging Face Blog
 © Hugging Face Blog
Models & Labscoding
IBM releases LLMON markup to fix prompt injection
IBM is tackling the brittleness of small language models by introducing LLMON, a structured markup language that explicitly separates instructions from data. By using reserved special tokens instead of ambiguous characters like JSON brackets, these new Granite 4.1 preview models drastically reduce indirect prompt injection attacks while maintaining standard performance. This approach forces the model to bind specific constraints to specific data payloads, eliminating the confusion that often leads to hallucinations or security breaches in long contexts.
Hugging Face Blog
 © Hugging Face Blog
Models & Labsother
Hugging Face releases TRELLIS.2 fine-tuning guide
Hugging Face finally provides a concrete path to adapt the powerful TRELLIS.2 model for specific domains like footwear or furniture, solving the 'generalist' problem in 3D generation. By targeting only the structure and shape DiTs with LoRA adapters while freezing the texture flow, they prevent catastrophic forgetting of material priors—a common pitfall when fine-tuning large generative models. This approach allows practitioners to achieve high geometric accuracy on small datasets (188 samples) without retraining the entire pipeline. It transforms TRELLIS.2 from a demo toy into a usable tool for production-grade 3D asset creation.
Hugging Face Blog
 © Hugging Face Blog
Open Sourceagents
Tether AI launches BotPsy, a sub-billion agentic model
Tether AI Research has released BotPsy, an 0.8B-parameter model built on Qwen3.5 that specializes in tool-use and agentic workflows for on-device deployment. It achieves state-of-the-art performance in its size class, outperforming larger models like Qwen3.5-2B-Think on benchmarks such as BFCL v4 and ACEBench while maintaining strict privacy by keeping data local. The model is designed to handle routine tasks like calendar management and web search without relying on expensive cloud APIs, offering a viable path for private, self-hosted personal assistants. With open weights under Apache 2.0 and GGUF support, it provides immediate utility for developers building lightweight, autonomous agents.
Hugging Face Blog
More in Research
 © MIT News AI
Researchother
MIT's human-in-the-loop topology optimization copilot
Topology optimization has long been a black box that engineers distrust because they can't steer the design as it evolves. MIT researchers solved this by training an ML model to predict where humans would intervene, pausing the algorithm to ask for feedback on manufacturability and aesthetics. This collaborative approach yielded structures with 39% higher buckling loads and better buildability, adding only 15 seconds to the total computation time. It shifts topology optimization from a theoretical exercise into a practical tool by restoring human agency without sacrificing performance.
MIT News AI
 © MIT News AI
Researchother
MIT Lincoln Lab wins R&D 100 for secure OS and quantum platform
MIT Lincoln Laboratory’s Magnetite operating system stands out as a serious contender for securing embedded systems against AI-driven cyberattacks. By combining a formally verified seL4 microkernel with Rust-based services, it offers a mathematically grounded alternative to legacy OS architectures in critical infrastructure. The lab also secured recognition for its Quantum Microsystems platform, which uses AI-optimized routing to integrate superconductor and semiconductor chips on a single wafer, addressing the interconnection bottlenecks that plague quantum scaling. These awards highlight a shift toward hardware-level security and system-level integration rather than just algorithmic improvements.
MIT News AI
 © MIT News AI
Researchresearch
MIT method trains climate AI with synthetic data
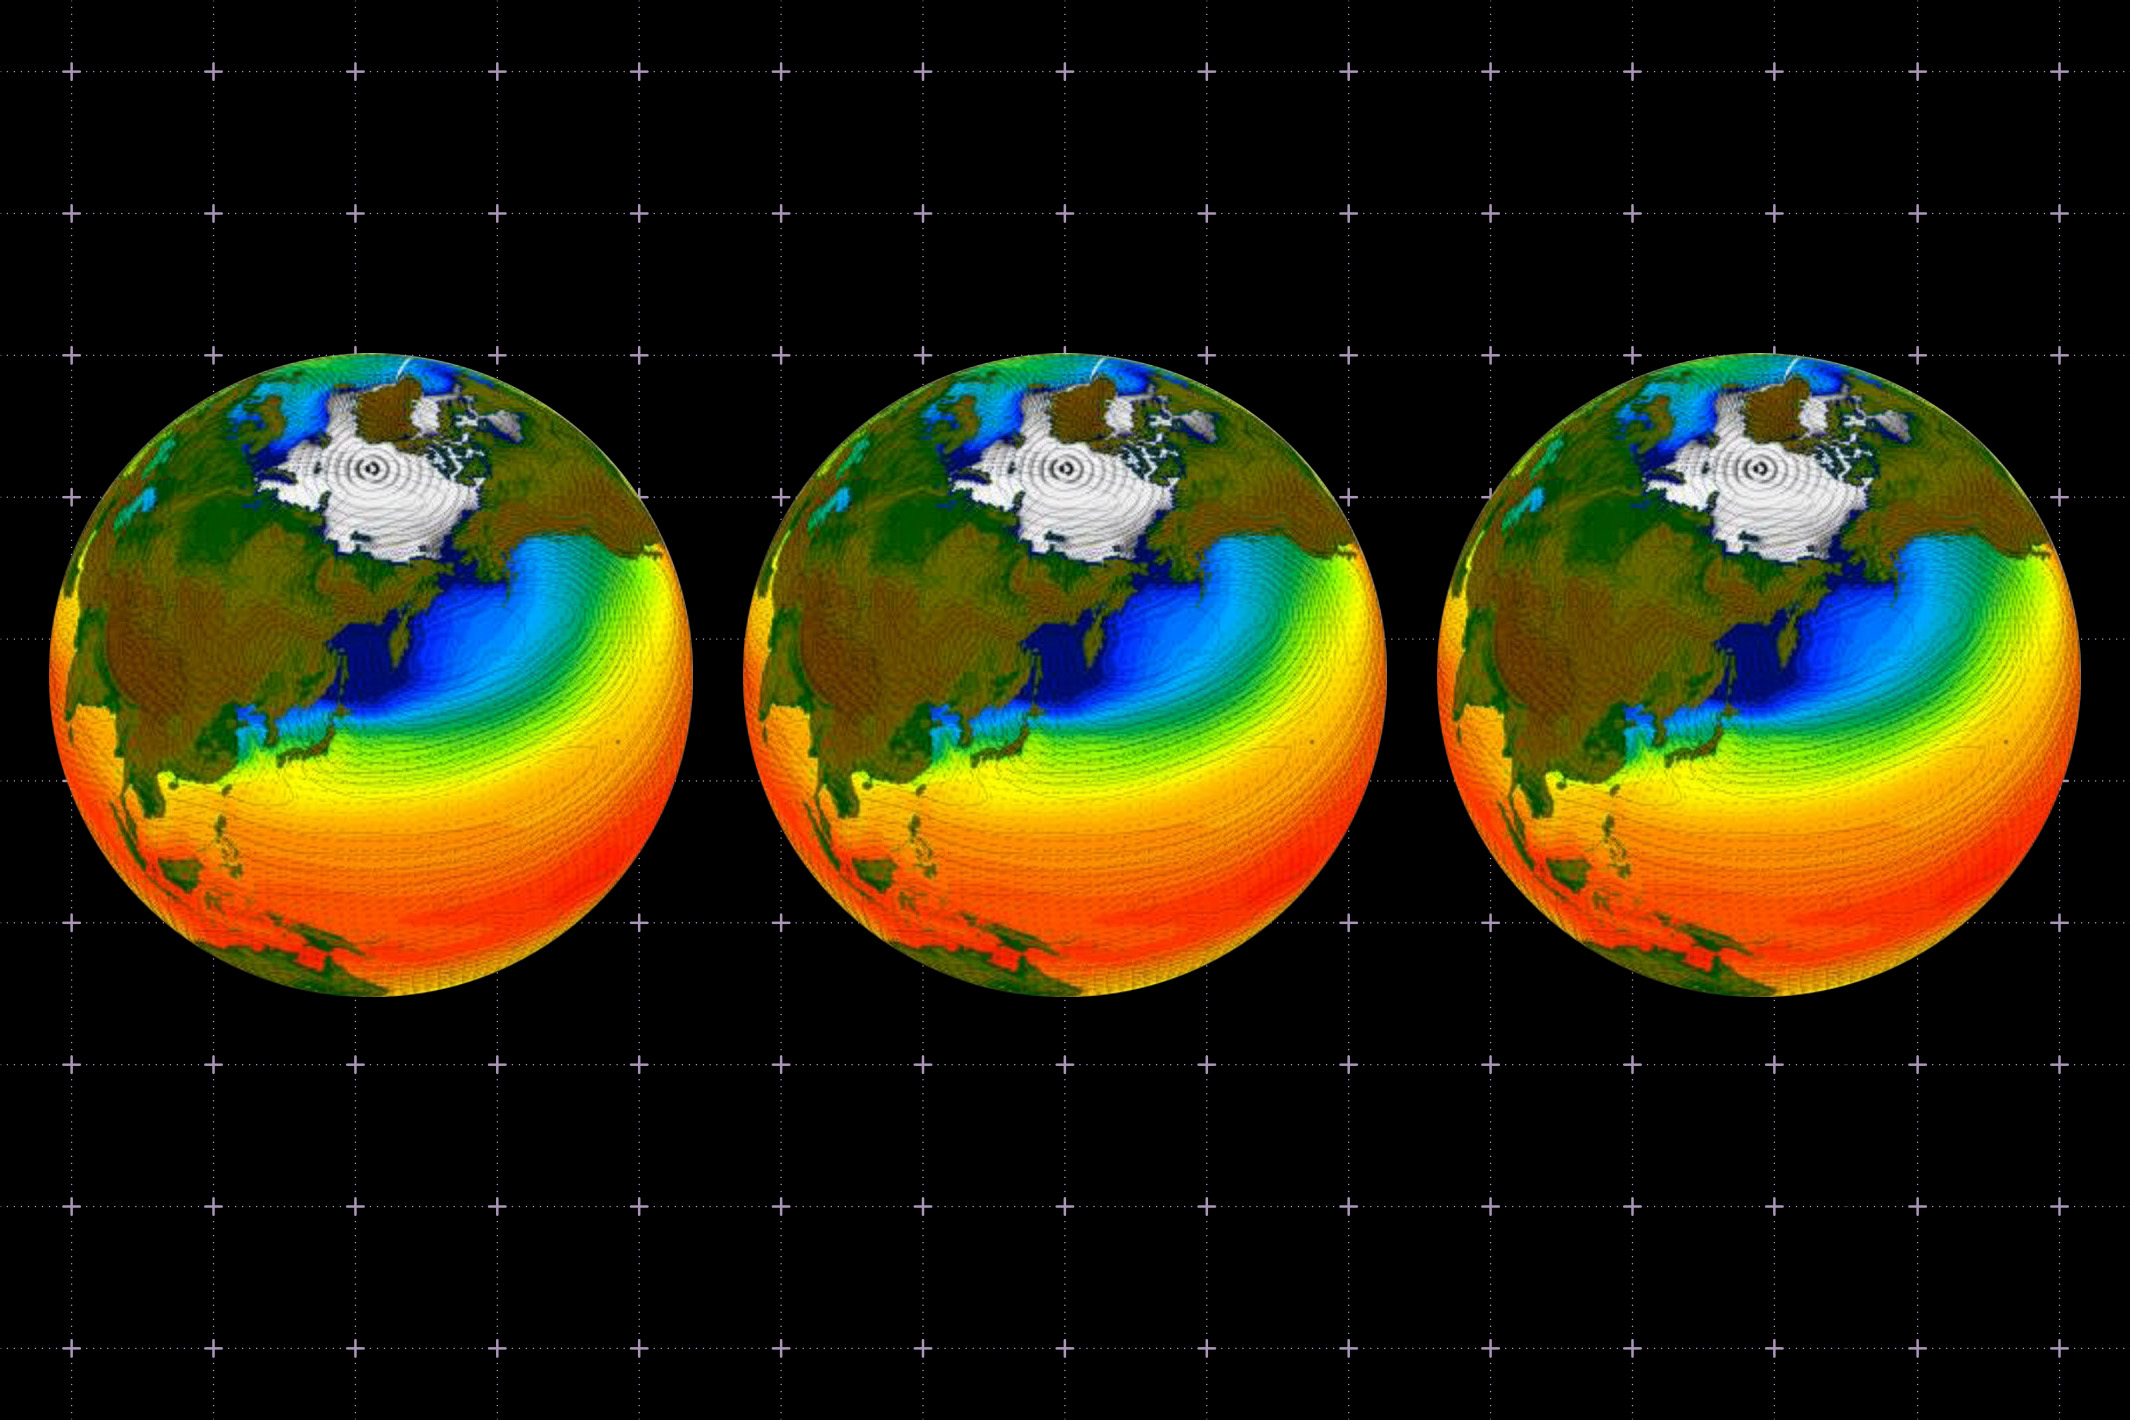
MIT researchers have solved a critical bottleneck in climate science: training fast AI emulators without months of supercomputer time. By generating optimized synthetic scenarios—complete with artificial high-frequency oscillations—they train models to generalize better than those fed realistic historical data. This approach cuts production time from years to days, allowing scientists to rapidly test novel policy interventions that traditional emulators fail to predict. It shifts climate modeling from static snapshots to dynamic, adaptable tools for immediate decision-making.
MIT News AI