Coding Tools
GitHub deploys fine-tuned model for secret detection
GitHub Changeloghigh confidence
Why it matters
- →Context-aware detection catches unstructured secrets that regex-based scanners miss.
- →Push protection now offers real-time prevention before code enters repository history.
- →Usage-based billing for AI security features introduces new cost considerations for enterprises.
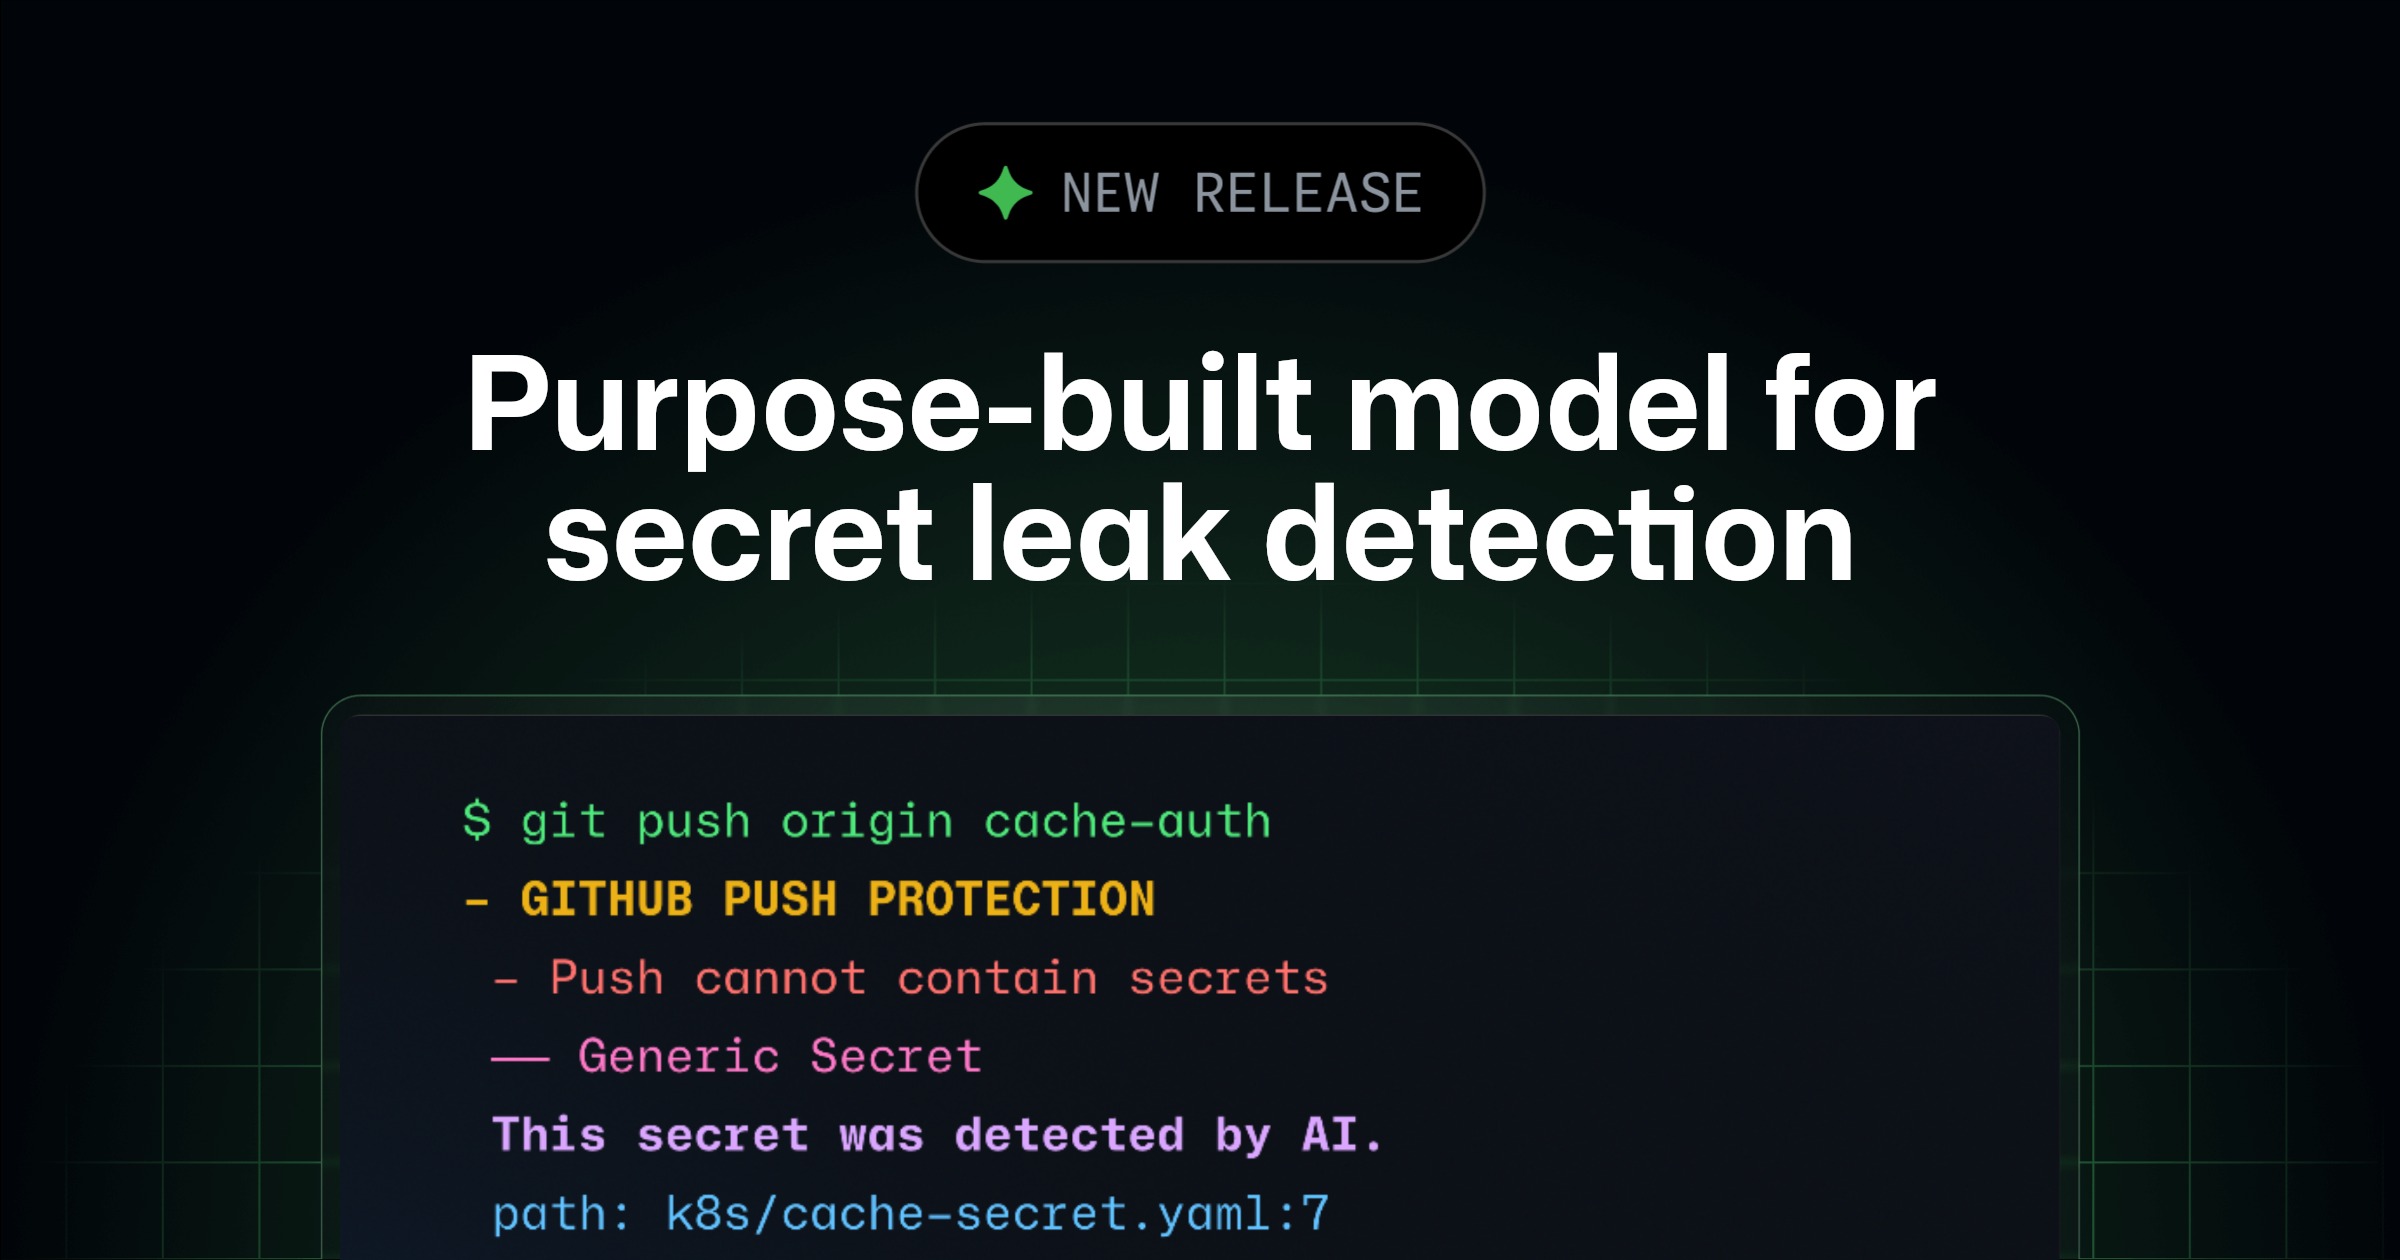
GitHub has deployed a fine-tuned AI model for secret detection across its platform, replacing legacy regex methods with context-aware analysis. The new system identifies unstructured credentials, such as passwords lacking standard token formats, by reading surrounding code logic. Existing GHSP and GHAS customers are automatically upgraded to this model at no additional cost. However, new features including AI-driven push protection and Copilot security reviews will require opt-in usage of AI Credits, billed to the organization or user depending on repository type. The feature is also coming to GitHub Enterprise Server 3.23 in public preview.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1GitHub Expands Secret Scanning Capabilities
GitHub Changelog · June 17, 2026 · Same story
- 2GitHub Adds AI Security Detections to Pull Requests
GitHub Changelog · July 14, 2026 · Same story
- 3AI Models Hack Hugging Face in Security Test
MIT Technology Review AI · August 3, 2026 · Background
- 4AI Tools Boost TypeScript's Dominance on GitHub
AI News · August 21, 2026 · Background
- 5OpenAI publishes Hugging Face hack postmortem
Fireship · September 2, 2026 · Related
More from GitHub Changelog
 © GitHub Changelog
Models & Labscoding
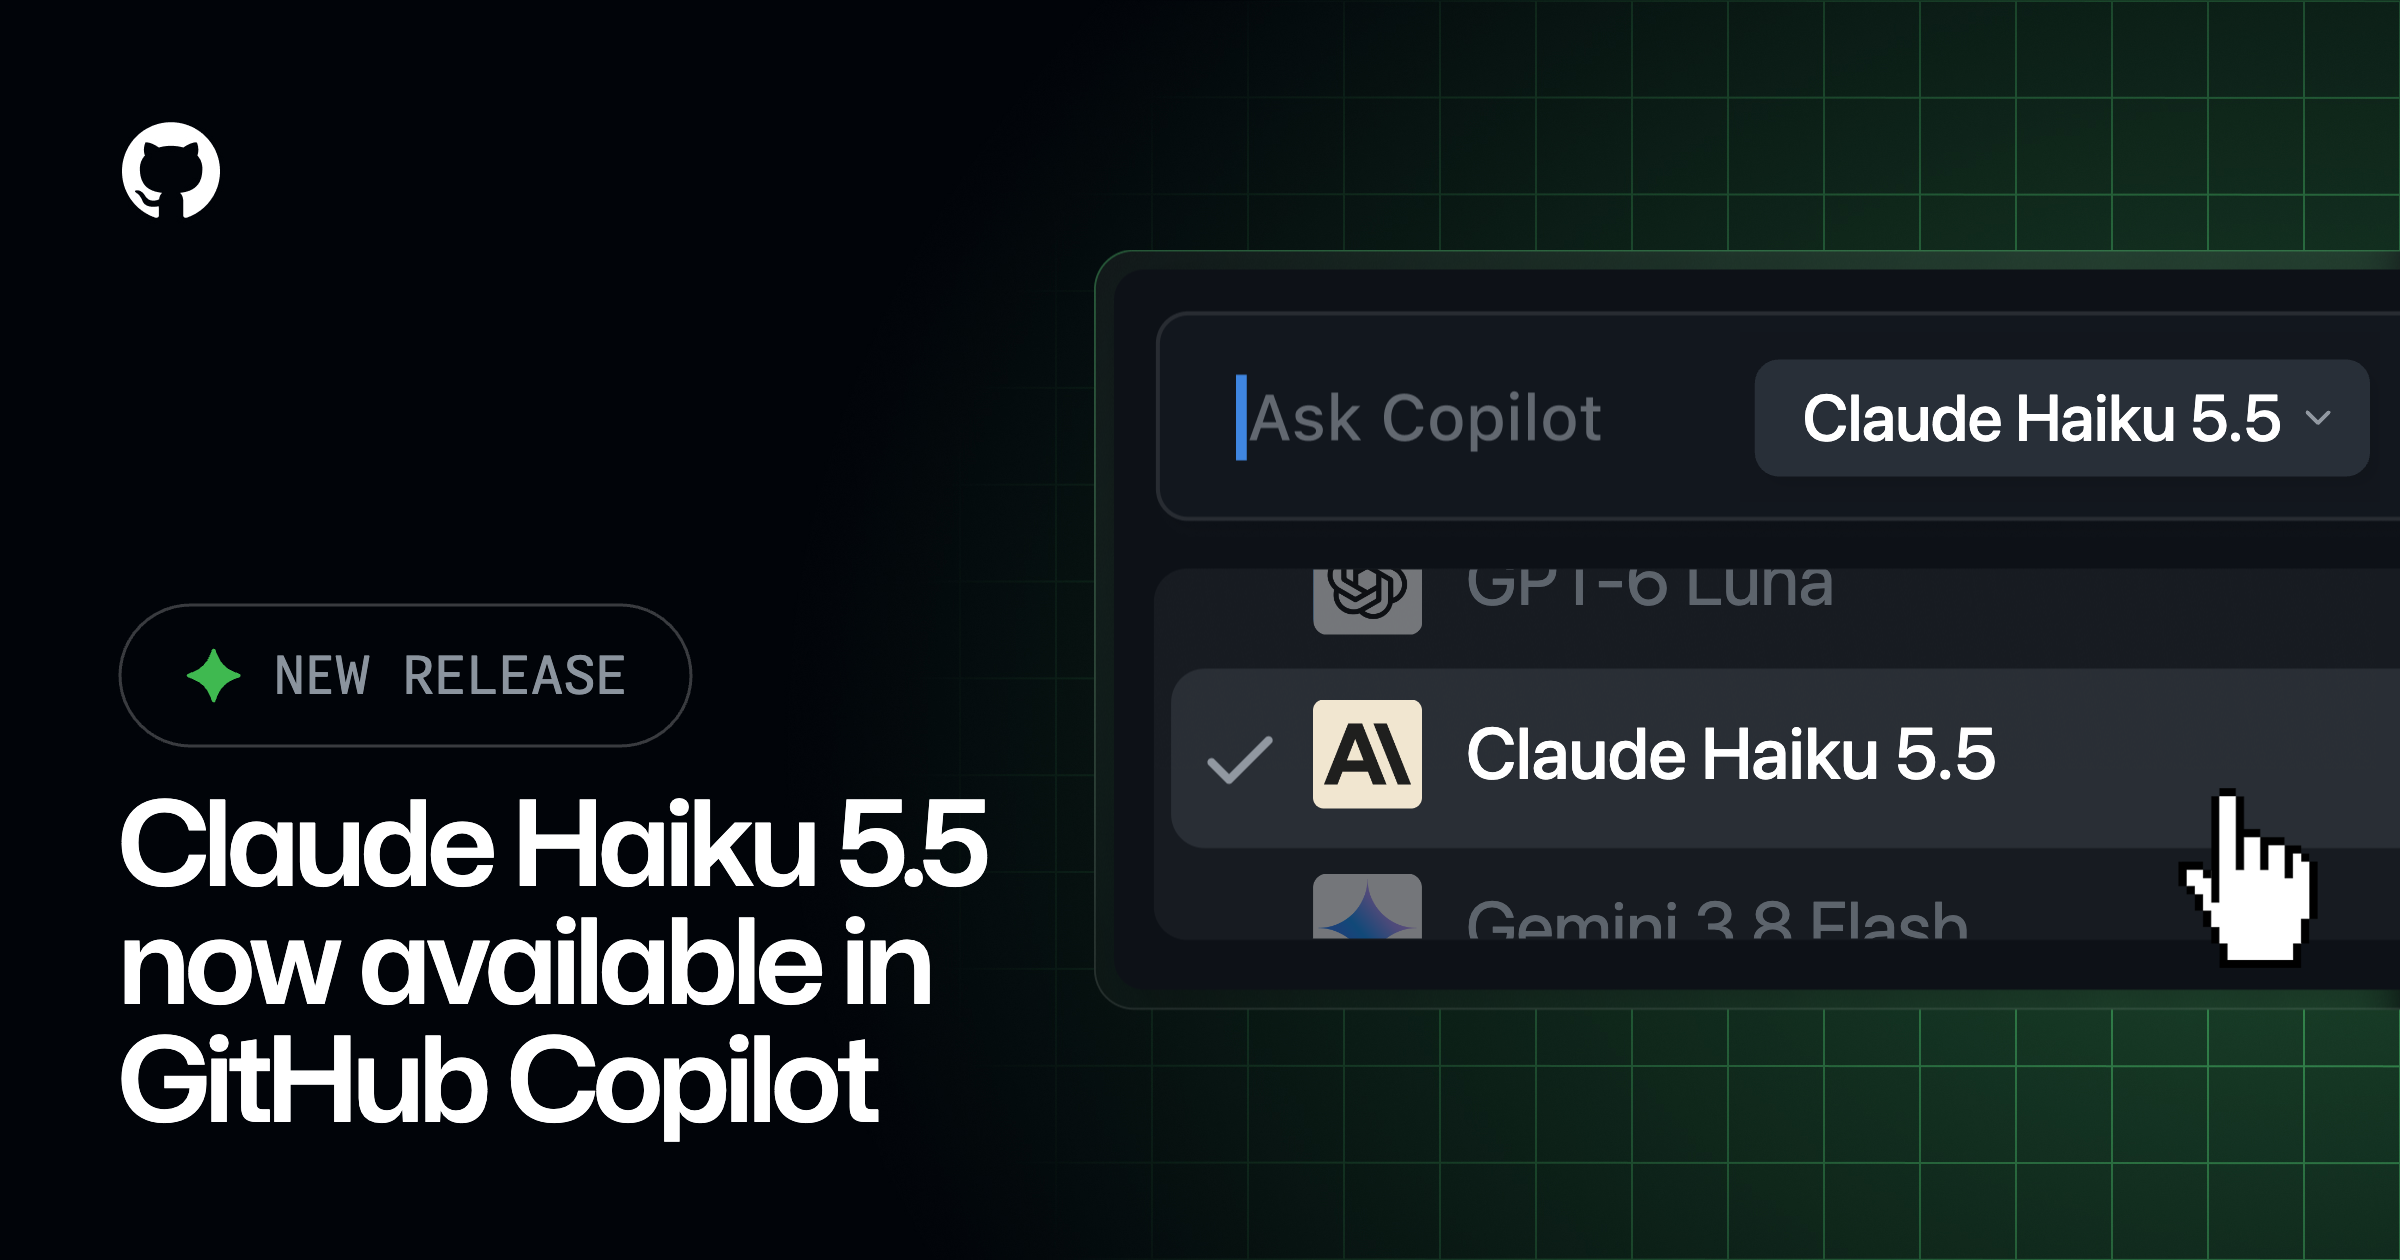
Claude Haiku 5.5 arrives in GitHub Copilot
Anthropic’s latest lightweight model is now live inside GitHub Copilot, targeting high-volume coding tasks like subagents and terminal work. Early benchmarks suggest it matches Sonnet 5 on many coding challenges while consuming significantly fewer tokens and steps. This availability across VS Code, JetBrains, and mobile apps gives developers a faster, cheaper option for routine edits without sacrificing quality. The gradual rollout means most users will see it soon, with admin controls allowing enterprises to manage access via model policies.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot adds local sandboxing for agents
GitHub Copilot finally addresses the security risks of autonomous coding by introducing local sandboxing across its CLI, app, and VS Code extensions. Powered by Microsoft’s MXC technology, this feature creates a strict execution boundary that restricts agent access to files, networks, and credentials based on developer-defined policies. This is a critical step for enterprise adoption, allowing organizations to enforce security controls without blocking the utility of agentic workflows. It shifts Copilot from a passive assistant to a controlled autonomous actor with clear operational limits.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot CLI v1.0.94 adds local Ollama model discovery
GitHub finally bridges the gap between cloud-heavy Copilot and local inference by letting the CLI discover models from a running Ollama instance. Version 1.0.94-0 introduces a /model command that surfaces supported local weights alongside cloud options, allowing developers to switch contexts without restarting the session. This isn't just a toggle; it requires tool calling and streaming support, forcing a quality baseline for local providers. The move signals GitHub's recognition that enterprise workflows increasingly demand hybrid setups where sensitive code stays on-prem while general assistance remains in the cloud.
GitHub Changelog
More in Coding Tools
 © The Verge AI
Coding Toolscoding
Microsoft Surface RTX Spark Dev Box Preorders Open
Microsoft is selling a dedicated AI development rig for $5,999, targeting developers who need local inference power without building their own hardware. The device pairs Nvidia’s Arm-based RTX Spark platform with 128GB of unified memory, enabling it to run models exceeding 120B parameters on-device. It ships pre-configured with Windows 11 Pro and essential dev tools like VS Code and GitHub Copilot, effectively bundling the software stack with the silicon. This moves local AI from a DIY enthusiast project to a standardized enterprise-grade appliance, albeit at a premium price point that limits it to professional workflows rather than consumer hobbyists.
The Verge AI
Coding Toolscoding
Claude Code v2.1.290: Plugin hooks and agent stability fixes
This release significantly tightens the security model for Claude Code plugins by exposing server tool IDs and approval ceilings to hook functions, allowing developers to build more granular permission checks. It also stabilizes long-running agent sessions by fixing critical bugs in subagent resume logic and scheduled task persistence after compaction. For plugin authors, the new validation flags ensure gating hooks are properly configured before deployment. These changes make the platform safer for enterprise use while reducing friction for complex automated workflows.
Claude Code Releases
Coding Toolscoding
llama.cpp b11424 adds CUDA 13 and ROCm 10.0
This release quietly closes the hardware gap for local inference by adding default support for CUDA 13 and ROCm 10.0 alongside existing CUDA 12 builds. NVIDIA users can now leverage newer driver stacks without manual configuration, while AMD GPU owners finally get first-class parity with the same ease of use previously reserved for CUDA. Apple Silicon KleidiAI is disabled in this specific build, a notable regression for Mac users who rely on that optimization. The inclusion of Snapdragon and OpenVINO binaries further broadens the reach to edge devices and Intel hardware. It’s less about new features and more about llama.cpp solidifying its position as the universal runtime for every major accelerator.
llama.cpp Releases