Models & Labs
OpenAI's GPT-5.6 Models Now in GitHub Copilot
GitHub Changeloghigh confidence
Why it matters
- →GPT-5.6 models enhance GitHub Copilot's adaptability for diverse coding tasks.
- →Developers can choose models based on specific project needs, improving efficiency.
- →The integration across multiple platforms broadens accessibility for users.
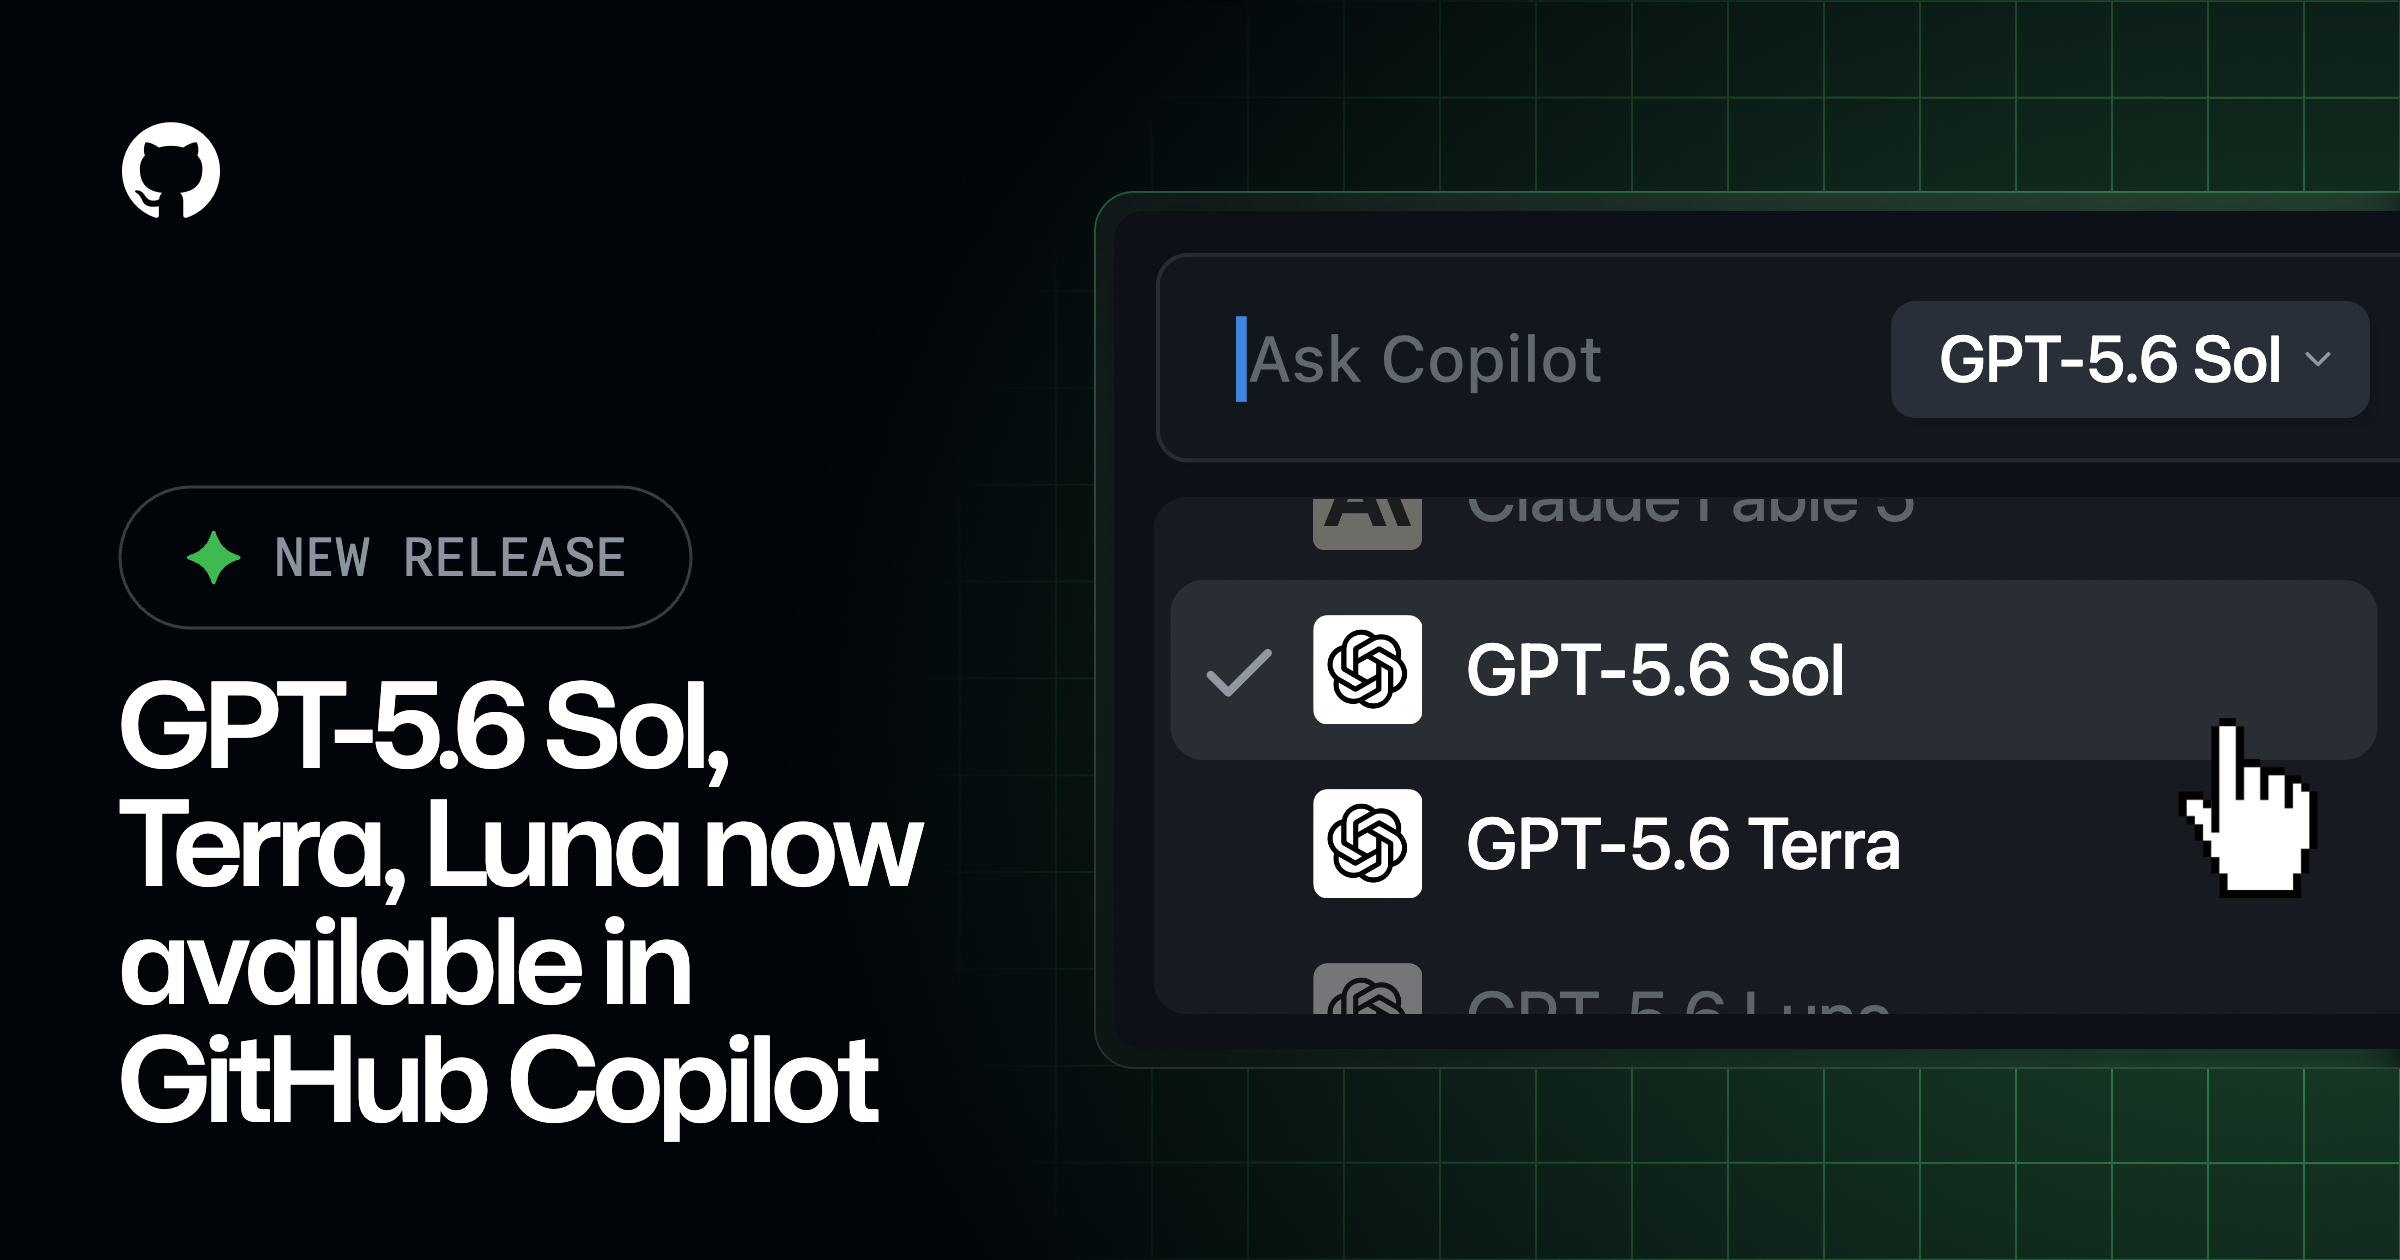
OpenAI has introduced its GPT-5.6 models—Sol, Terra, and Luna—into GitHub Copilot, enhancing the tool's adaptability for different coding tasks. Sol is optimized for complex reasoning, Terra offers a balanced approach for general coding, and Luna is designed for cost-effective, smaller tasks. These models are available under Usage Based Billing and can be accessed through various platforms like Visual Studio and GitHub Mobile. The rollout is gradual, with administrators needing to enable the models in Copilot settings.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
More from GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub expands issue types to personal accounts
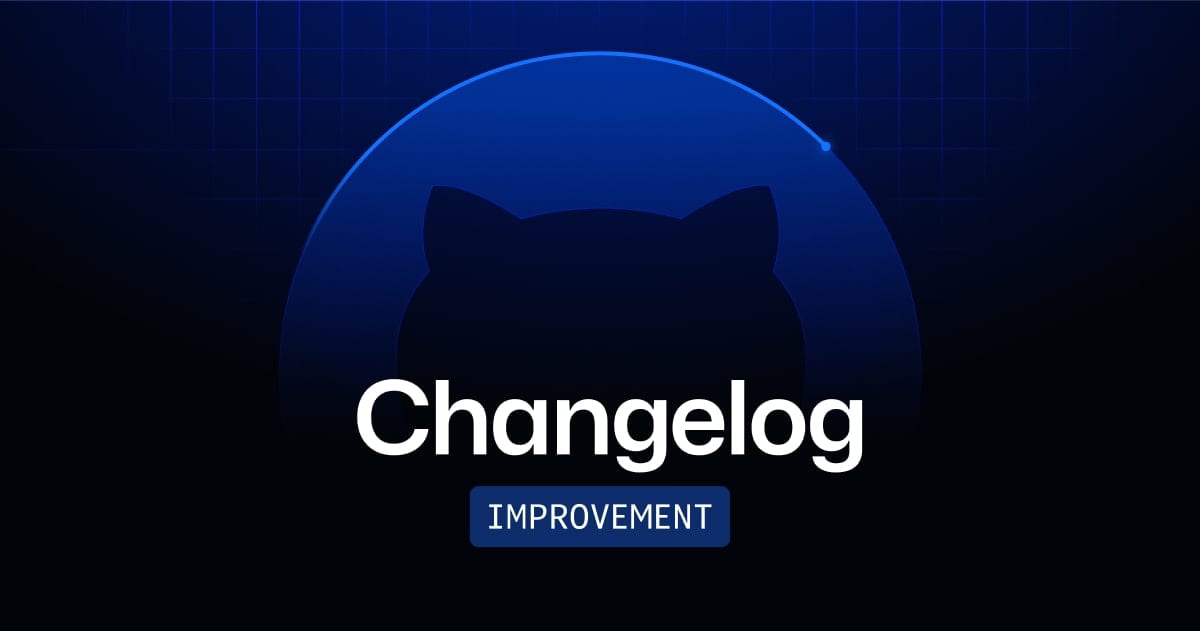
GitHub finally brings enterprise-grade planning structures to individual developers. Personal repositories now support customizable issue types and fields, allowing solo maintainers to standardize workflows with up to 25 distinct categories. This closes a long-standing gap where only organizations could enforce structured data schemas for bug tracking and feature management. The move signals that GitHub is treating personal open-source projects with the same operational seriousness as corporate codebases.
GitHub Changelog
 © GitHub Changelog
More in Models & Labs
Models & Labsother
llama.cpp b12340 adds CUDA 13 and ROCm 10.0
This release quietly closes the hardware gap for local inference by adding default support for CUDA 13 and ROCm 10.0 across Linux and Windows. Users with newer NVIDIA GPUs or AMD accelerators no longer need to compile from source to get performance, while Apple Silicon builds now ship KleidiAI disabled by default, shifting the focus back to standard ARM optimizations. The inclusion of Snapdragon support for Linux and Android marks a significant step toward on-device AI beyond the x86/ARM desktop ecosystem. It is less about new features and more about ensuring llama.cpp remains the universal runtime for every available accelerator.
llama.cpp Releases
Models & Labscoding
llama.cpp b12342 adds few-row MMQ for speculative decoding
Speculative decoding just got a significant speed boost on NVIDIA GPUs. This release introduces a specialized kernel for 'few-row' matrix multiplications, targeting the small batch sizes typical of verification passes in speculative decoding workflows. By optimizing these specific operations for quantized formats like Q8_0 and IQ4 variants, llama.cpp reduces latency where it matters most during token generation. The change is CUDA-only for now but leverages hardware capabilities from Ampere onwards, making local inference faster without requiring new model architectures or complex configuration changes.