Coding Tools
GitHub AI Scan API now manages repository-level settings
GitHub Changeloghigh confidence
Why it matters
- →Enables automated governance of AI scanning across large codebases via infrastructure as code.
- →Reduces manual overhead for security teams managing repository-level policy exceptions.
- →Aligns repository scan management with existing pull request scan automation workflows.
GitHub has expanded its REST API for code scanning to include programmatic management of AI Scan settings at the repository level. The update adds a repository_scan property to organization and repository endpoints, allowing users to enable or disable the feature via scripts and infrastructure as code. This mirrors the existing behavior for pull request scans, where organizational policies dictate default states that individual repositories can inherit or opt out of. The feature is currently in public preview and requires GitHub Code Security or Advanced Security licenses.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1GitHub Launches AI Scan API for Pull Requests
GitHub Changelog · September 10, 2026 · Same story
- 2GitHub adds AI Scan enablement visibility
GitHub Changelog · October 6, 2026 · Same story
More from GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot Deprecates Claude Haiku 4.5 in Dec 2026
GitHub is quietly removing Claude Haiku 4.5 from its entire Copilot ecosystem by December 2026, a move that forces enterprise and business users to migrate away from Anthropic’s fastest model. While individual annual subscribers retain access, the deprecation signals a strategic shift in GitHub’s default model stack, likely prioritizing higher-margin or more integrated options like GPT-4o or newer Claude variants. This isn't just a sunset notice; it's a mandate for workflow updates, requiring administrators to actively manage model policies rather than relying on passive defaults. The move highlights the fragility of relying on third-party models within closed IDE ecosystems, where access can be revoked unilaterally. Developers must now audit their settings to ensure compliance with new default stacks. This transition marks a clear boundary between individual flexibility and enterprise control in AI tooling.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Copilot app supports Enterprise Server
The GitHub Copilot desktop app finally reaches parity with the web interface for enterprise users. Version 1.2.0 makes GitHub Enterprise Server support generally available, allowing developers to connect their GHES accounts directly within the IDE-like environment. This closes a significant gap for organizations that cannot or will not use GitHub.com, enabling remote repository and pull request workflows without leaving the app. While cloud sessions remain unavailable for these instances, local inference on enterprise code is now fully integrated.
GitHub Changelog
 © GitHub Changelog
Models & Labscoding
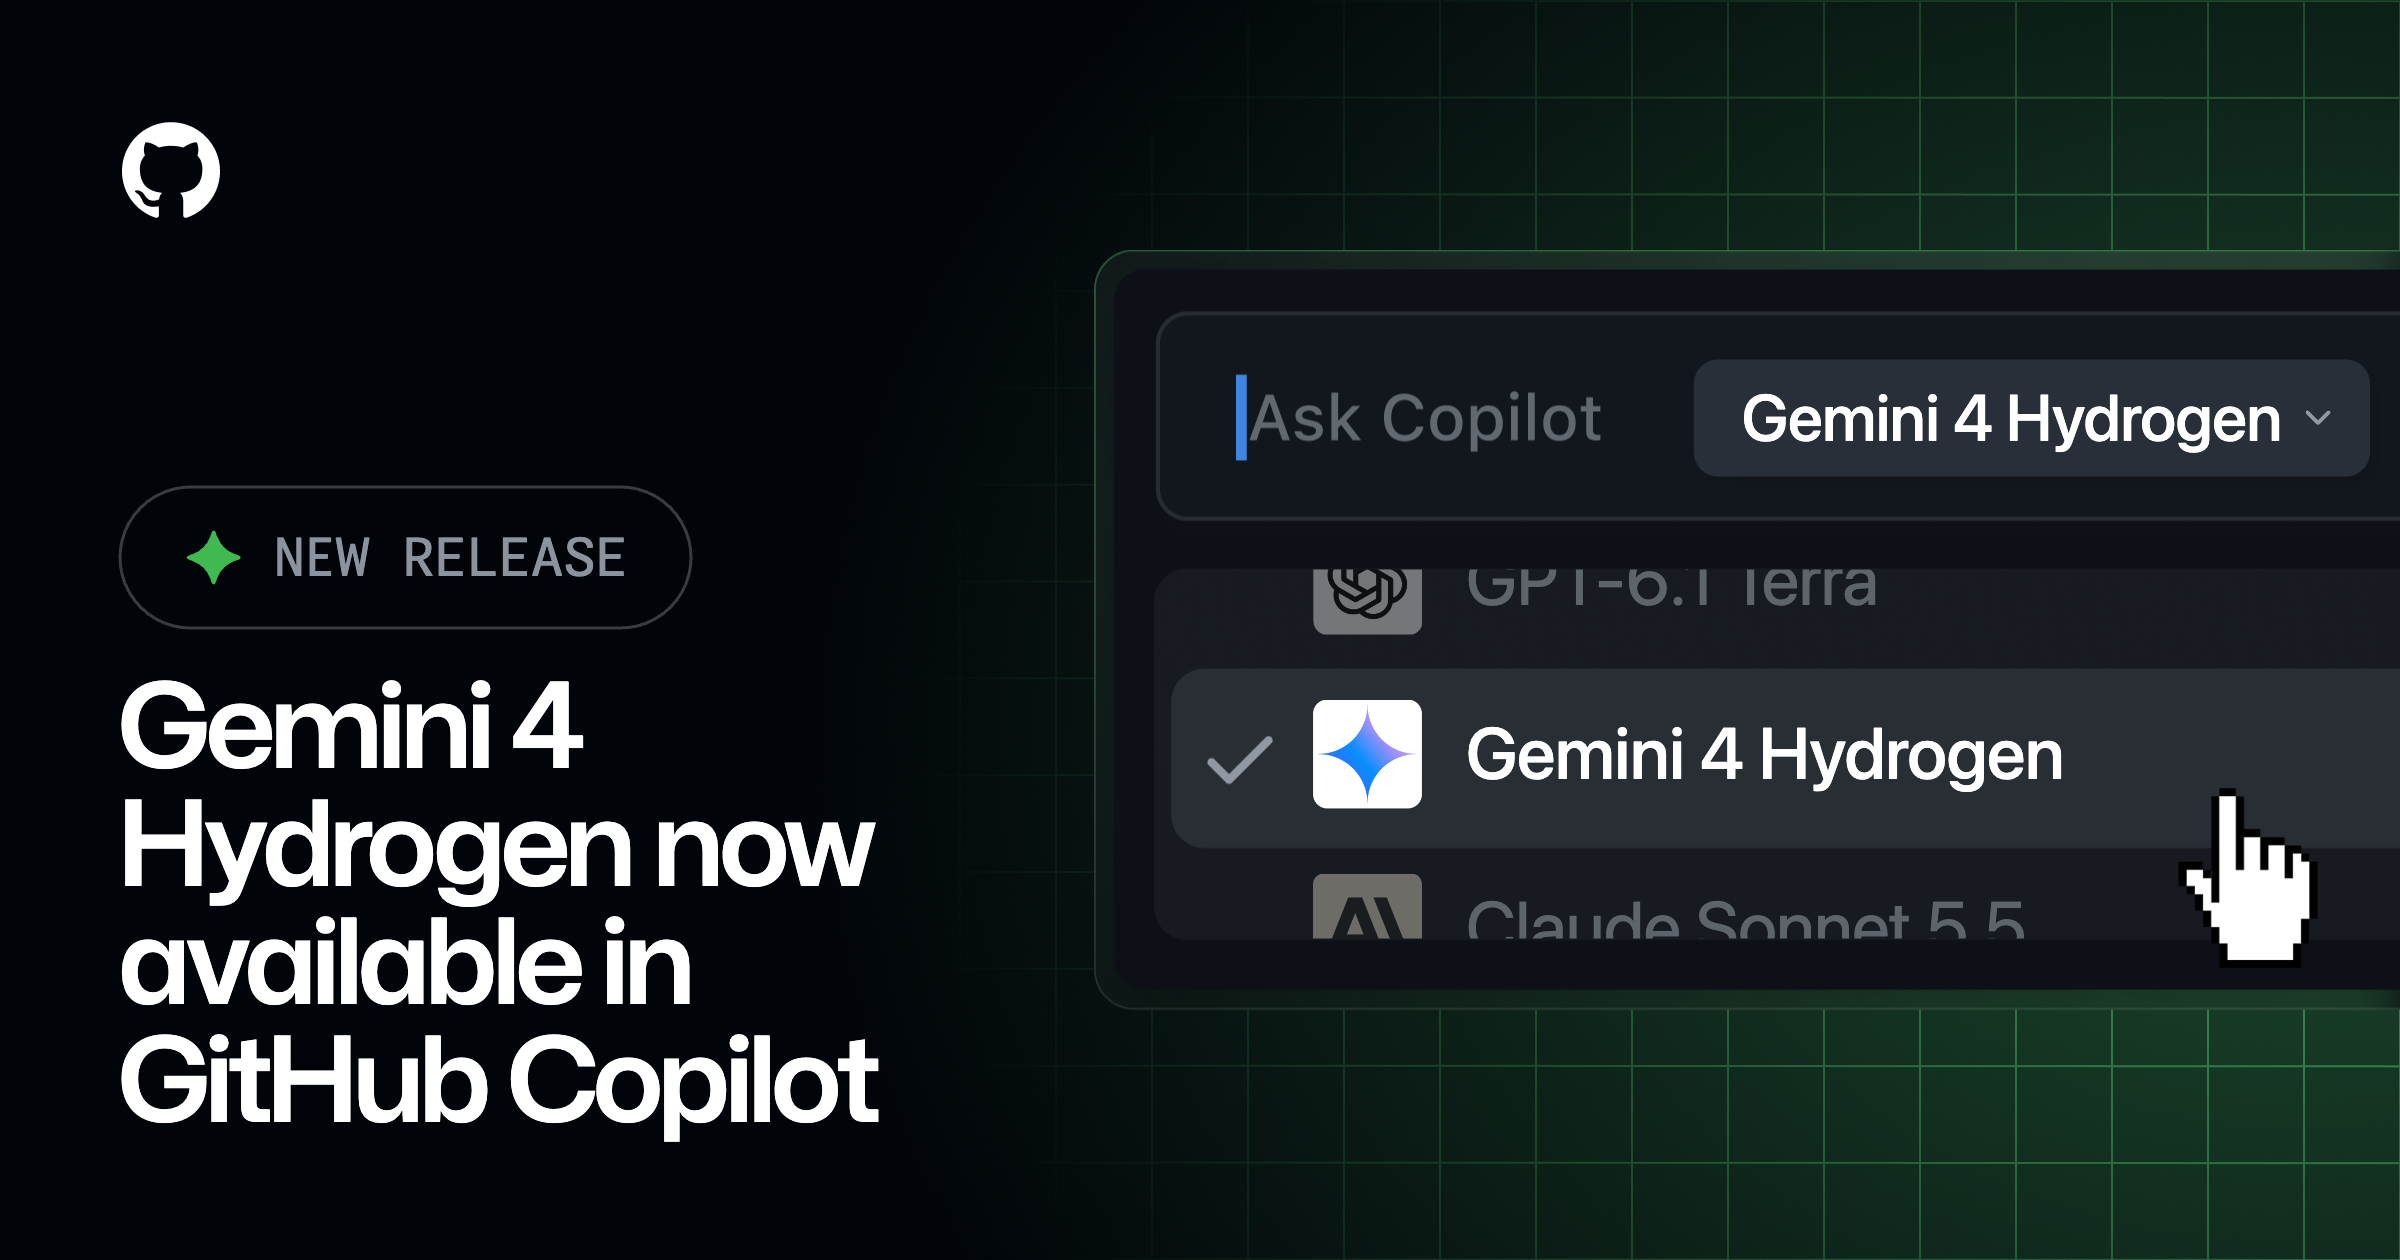
Gemini 4 Hydrogen arrives in GitHub Copilot
Google’s latest Flash model is now generally available in GitHub Copilot, targeting agentic coding and multistep workflows. It offers improved instruction following over Gemini 3.8 Flash and is billed at provider list pricing under usage-based billing. The rollout is gradual across Visual Studio Code, JetBrains IDEs, and other platforms. Administrators can manage access through model policies in Copilot settings.
GitHub Changelog
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.325 patches security and MCP stability
This release prioritizes stability over new features, addressing a critical zstd decompression vulnerability that could have exposed response data. Beyond security, it significantly hardens the reliability of Model Context Protocol (MCP) integrations, fixing persistent connection drops and authentication loops that plagued background tasks. The update also resolves context compaction failures on third-party gateways, ensuring sessions no longer crash when hitting token limits. For developers relying on Claude Code for complex workflows, this patch removes several friction points that previously interrupted automated coding sessions.
Claude Code Releases
Coding Toolscoding
llama.cpp b12398 optimizes Vulkan Flash Attention for AMD
This release targets the persistent performance gap on AMD hardware by optimizing Vulkan Flash Attention specifically for RDNA3 and RDNA4 architectures. The changes include reducing shared memory usage through buffer reuse and fixing critical stability issues like NVIDIA hangs and sparse FA underflow bugs. While there are no new model architectures, these low-level shader optimizations directly translate to faster inference speeds for local users on modern AMD GPUs. It is a quiet but necessary engineering update that tightens the ecosystem for non-NVIDIA accelerators.
llama.cpp Releases
Coding Toolscoding
llama.cpp b12399 adds ROCm 10 and CUDA 13 builds
This release quietly extends llama.cpp’s hardware support to the latest NVIDIA and AMD stacks. By shipping binaries for CUDA 13.5 and ROCm 10.0, it ensures users on cutting-edge GPUs don't have to compile from source to get performance gains. The Vulkan build also fixes header inclusion issues that previously broke compilation on some Linux distributions. It’s a maintenance update rather than a feature leap, but it keeps the local inference runtime compatible with the fastest consumer and datacenter hardware available today.
llama.cpp Releases