Coding Tools
llama.cpp adds env var control for server args
llama.cpp Releaseshigh confidence
Why it matters
- →Enables declarative configuration for llama-server via environment variables.
- →Simplifies systemd integration for production deployments.
- →Improves reproducibility of inference server setups.
The latest llama.cpp release adds support for configuring server arguments such as temperature, top-p, and penalties via environment variables (LLAMA_ARG_*). This allows users to manage llama-server configuration through systemd EnvironmentFile directives, simplifying deployment on Linux systems. The update also regenerates documentation using the llama-gen-docs tool. No new hardware backends or model architectures are included in this release.
Read originalMore from llama.cpp Releases
Models & Labsother
llama.cpp b11080 release with ROCm 10 and CUDA 13
This update quietly extends llama.cpp’s hardware support to ROCm 10.0 and CUDA 13.4 across Linux and Windows, keeping the library competitive as NVIDIA pushes newer driver stacks. The test suite also gains regex filtering for backend operations, a practical improvement for developers debugging specific inference paths. While no new model architectures are introduced, this release ensures compatibility with the latest GPU ecosystems without forcing users to wait for major version bumps.
llama.cpp Releases
Models & Labsother
llama.cpp b11081 release with CUDA 13 and ROCm 10 support
This release quietly cements llama.cpp as the universal inference runtime by adding default builds for CUDA 13.4 and ROCm 10.0, effectively closing the gap on newer NVIDIA and AMD hardware without requiring manual compilation flags. The inclusion of KleidiAI for Apple Silicon remains a key differentiator for local Mac users seeking optimized ARM kernels. While the changelog details internal test improvements like configurable tensor standard deviation, the real value lies in the expanded binary matrix that supports developers across the latest GPU architectures. Readers can now deploy on cutting-edge hardware out of the box. The update ensures that teams using the newest graphics cards do not need to wait for source code patches to achieve stable performance. This is a practical step toward making local inference truly hardware-agnostic.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11090 fixes CUDA Volta build
This release quietly repairs a regression in the CUDA backend that broke compilation on older Volta GPUs. By generalizing the tile shape logic in the load_ldmatrix kernel, the maintainers restored support for devices like the Tesla V100 without sacrificing newer architectures. It is a necessary patch for anyone running inference on legacy hardware, ensuring the codebase remains usable across the full spectrum of NVIDIA cards rather than drifting toward only the latest silicon.
llama.cpp Releases
More in Coding Tools
 © GitHub Changelog
Coding Toolscoding
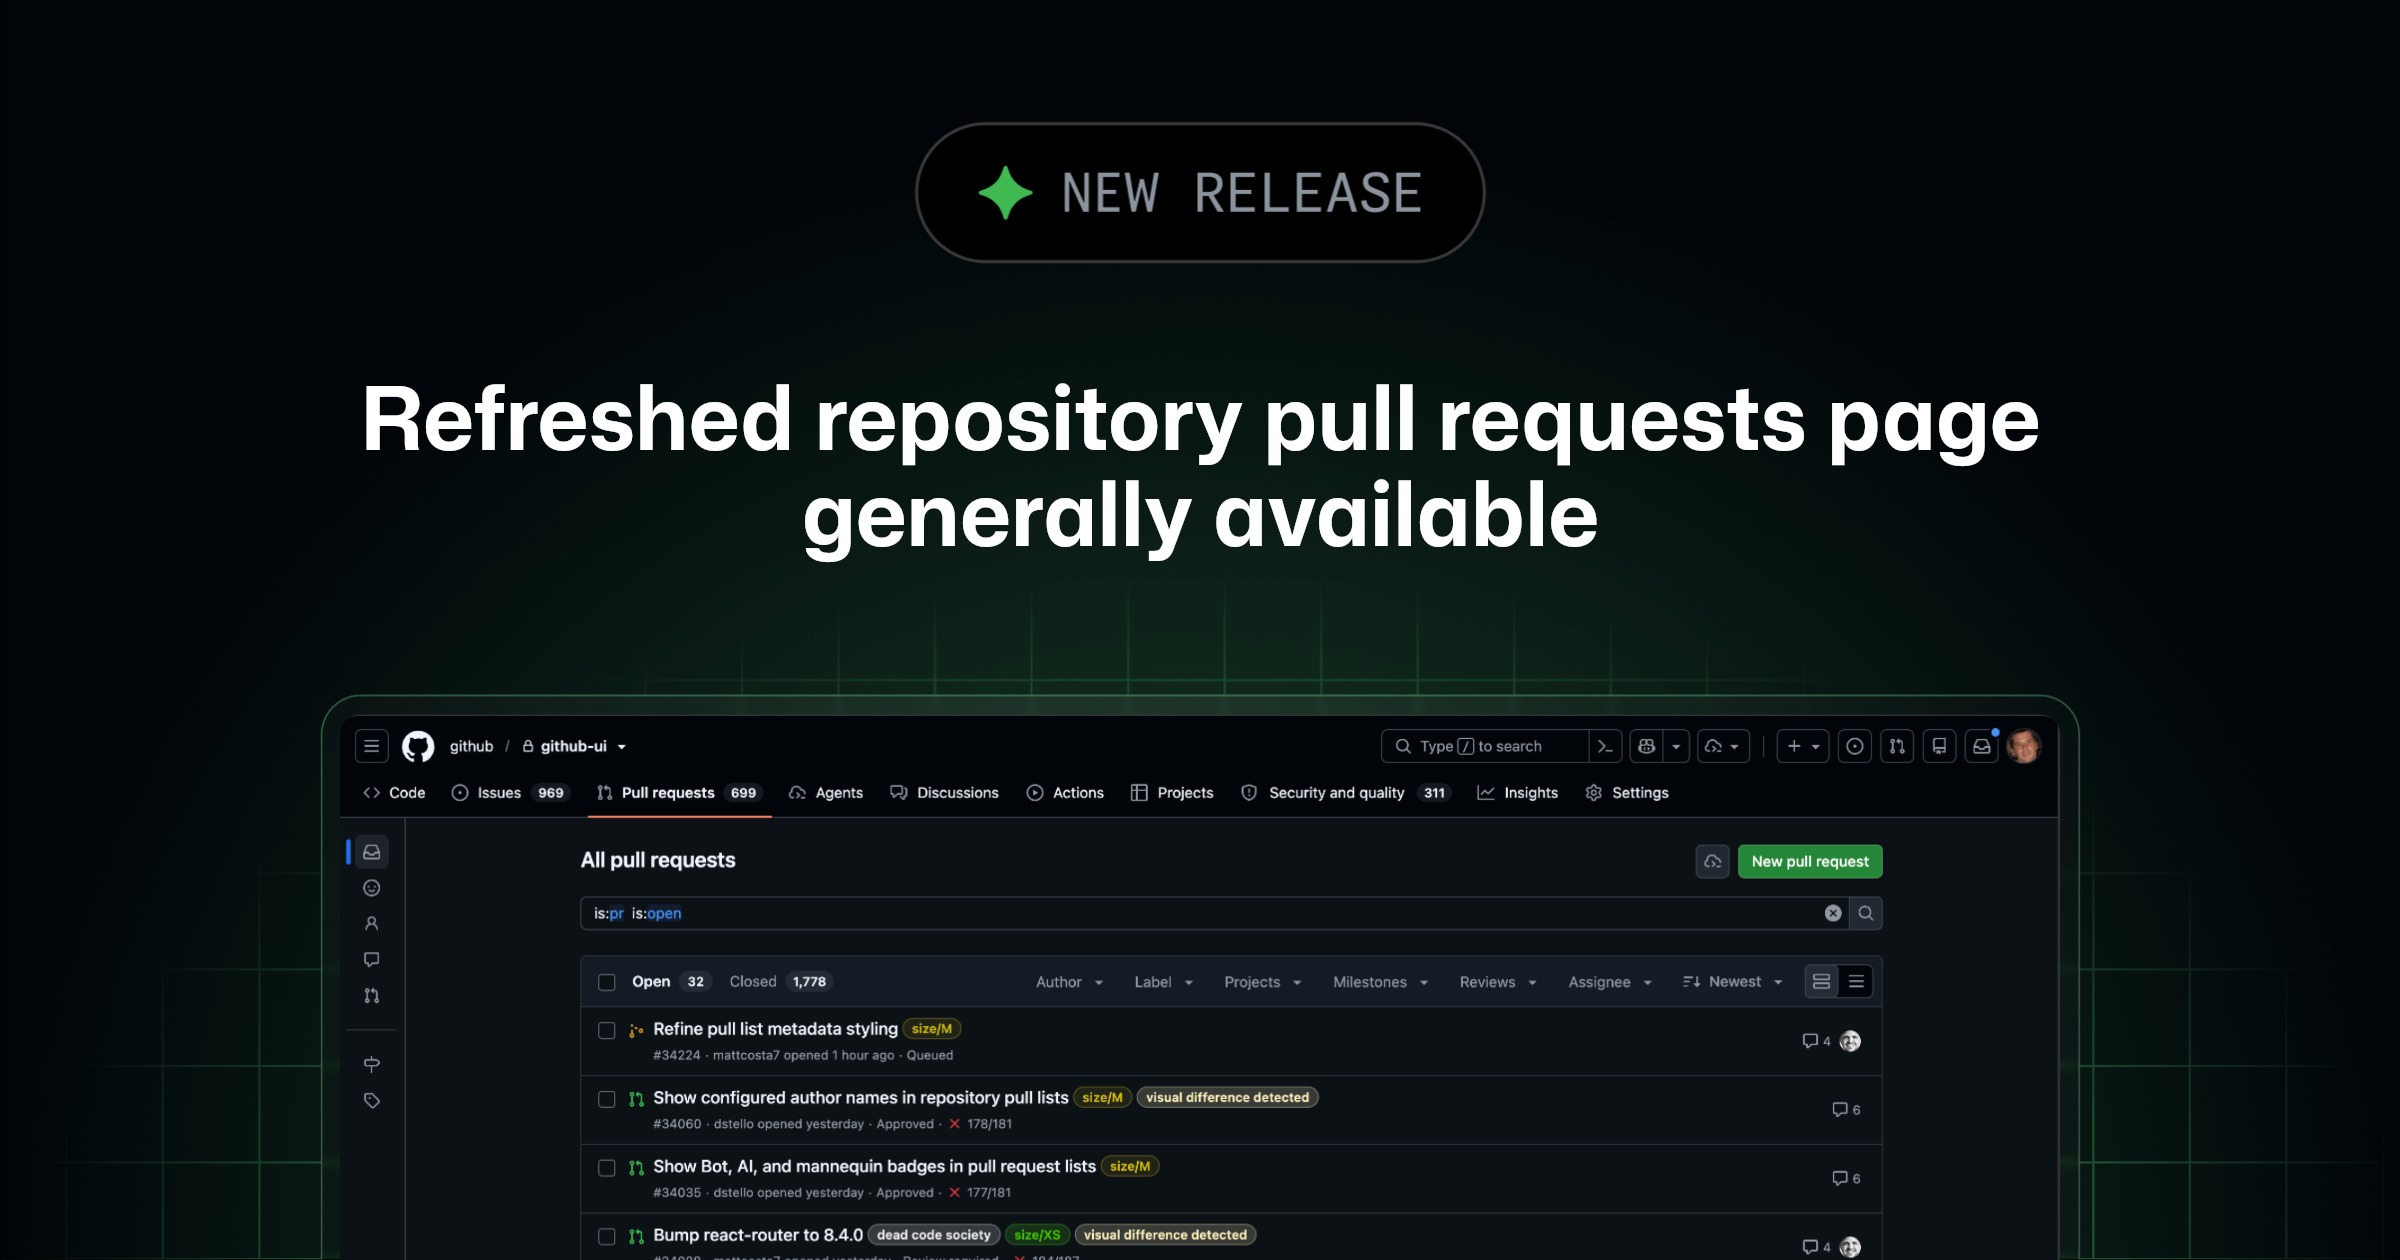
GitHub PR page GA with bulk actions
GitHub’s redesigned pull requests interface has moved from preview to general availability, shifting the focus from basic listing to active triage. The update brings bulk actions like closing or labeling multiple PRs simultaneously, a feature long requested by maintainers drowning in review queues. Advanced search now supports nested logic and AND/OR operators, while collapsible sidebars and compact modes help developers scan more context without endless scrolling. This isn't a new AI model, but it directly addresses the workflow bottleneck of code review management for millions of developers.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub Enterprise adds credential inventory exports
GitHub finally gives enterprise admins a centralized view of every active credential across their organization. By exporting a complete inventory of SSH keys, tokens, and app permissions, security teams can instantly map their attack surface during an incident. This moves credential management from scattered manual checks to a single, auditable CSV or API endpoint. It’s a critical infrastructure upgrade for compliance and rapid response, closing a long-standing visibility gap in enterprise security operations.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
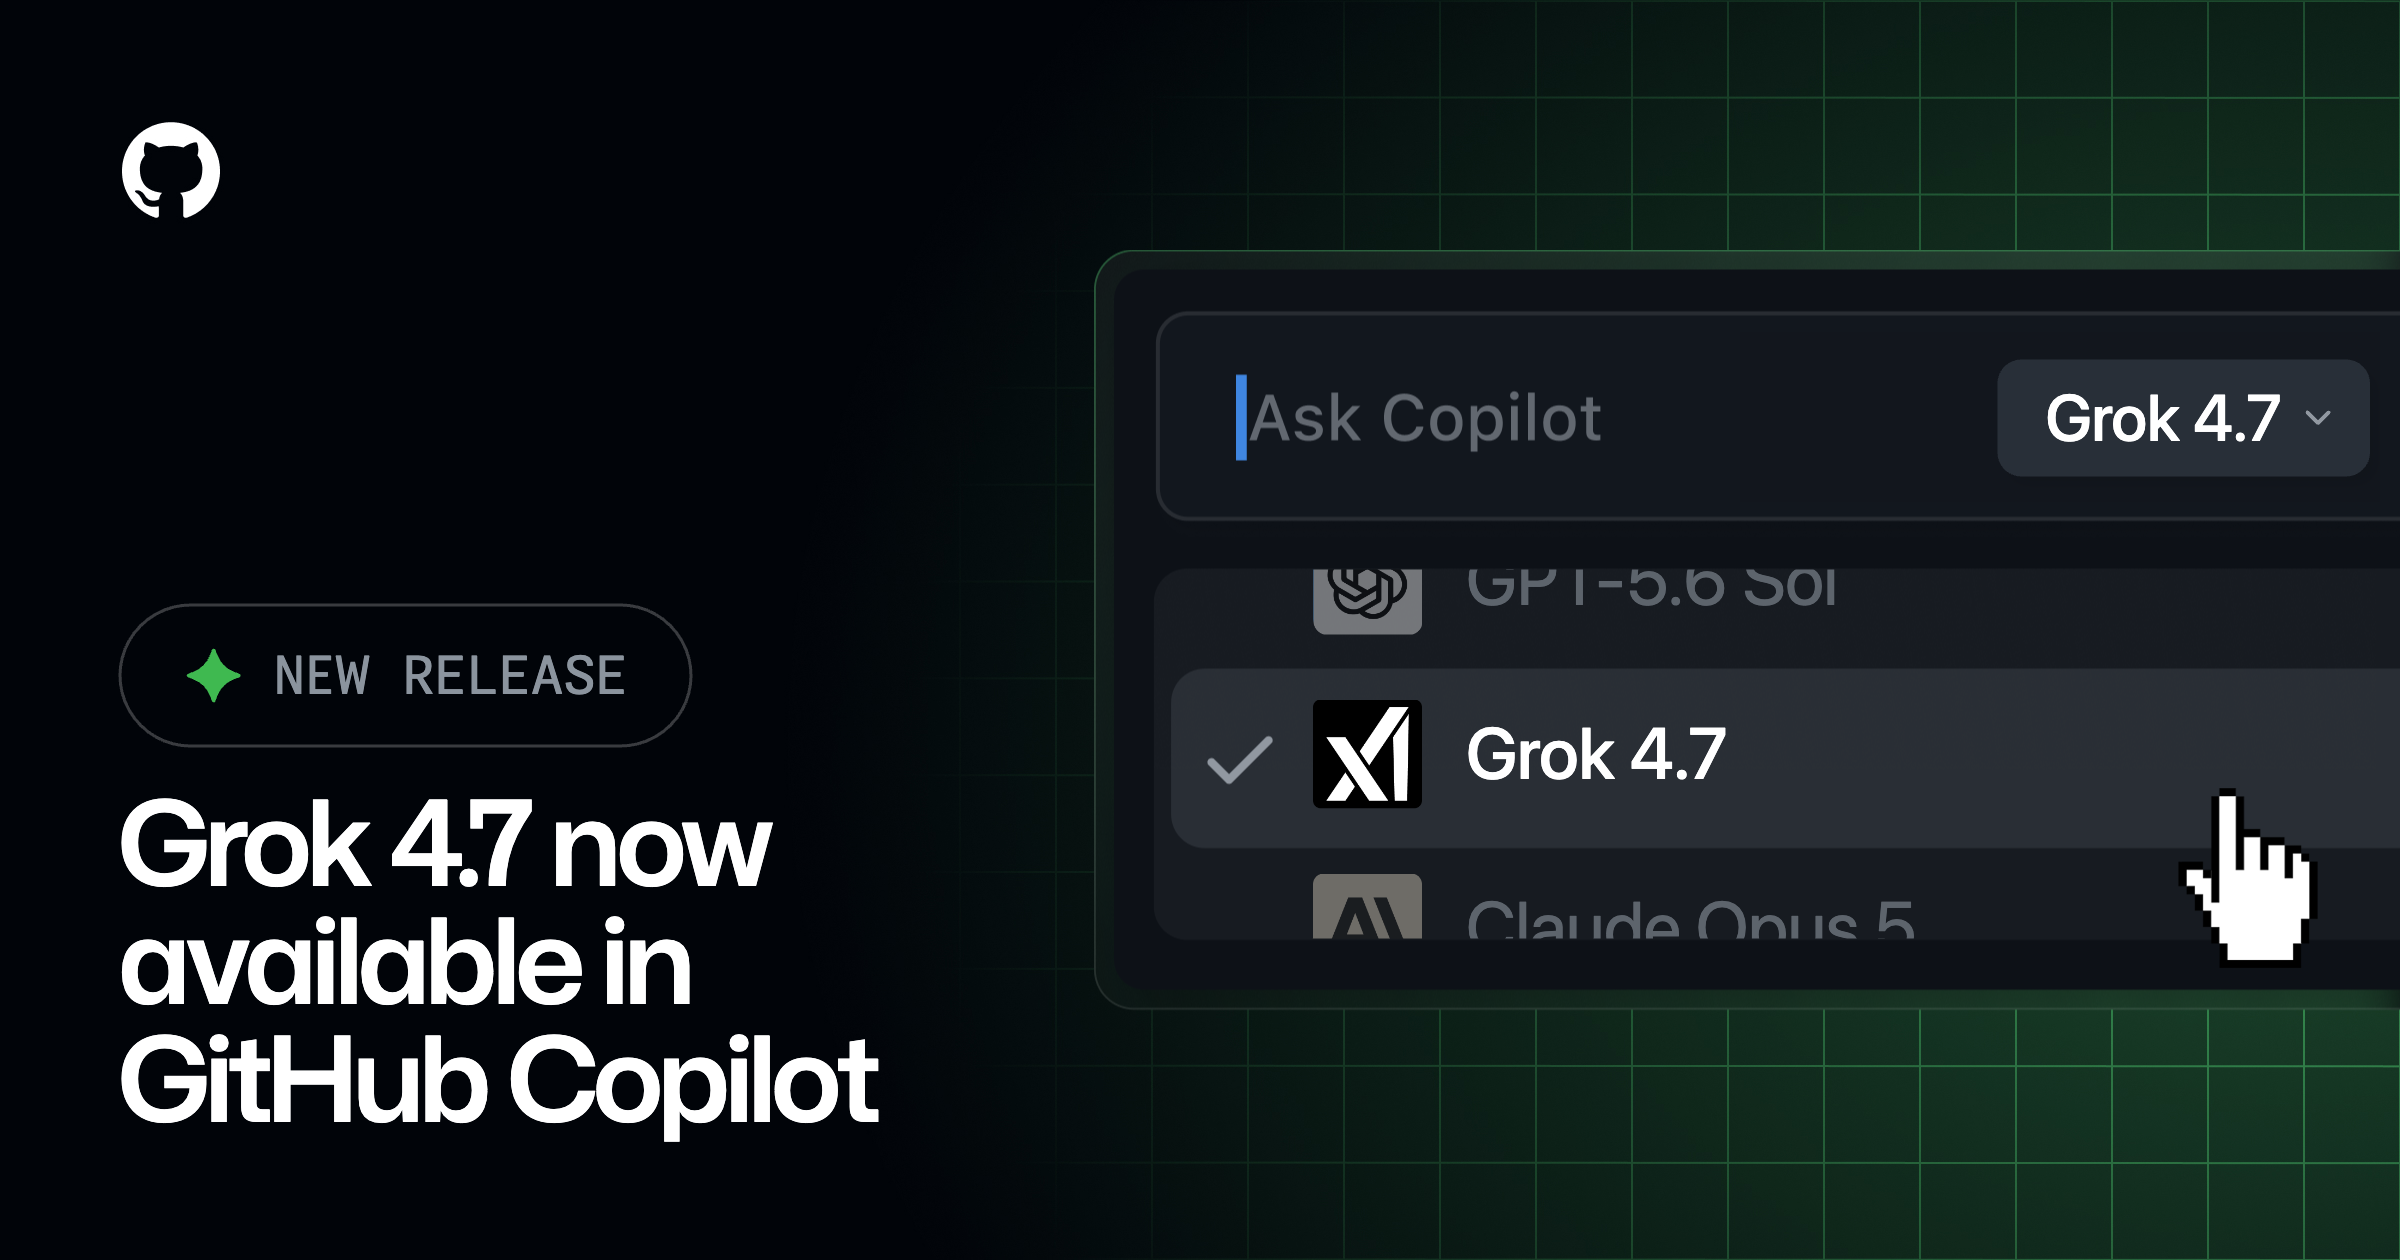
Grok 4.7 arrives in GitHub Copilot for agentic coding
xAI’s Grok 4.7 has landed in GitHub Copilot, shifting the IDE experience from simple autocomplete to complex, multistep reasoning workflows. This isn't just another model swap; it targets agentic coding tasks that require holding context across multiple files and steps. Available across all major IDEs including VS Code, JetBrains, and Xcode, it brings xAI’s latest capabilities directly into the developer’s primary workspace. The gradual rollout means most users will see it soon, with enterprise admins able to manage access via policy settings. This marks a significant step in making non-OpenAI reasoning models a first-class citizen in the dominant coding environment.
GitHub Changelog