Models & Labs
Falcon-ASR targets Emirati dialect with open weights
Hugging Face Bloghigh confidence
Why it matters
- →Solves the critical gap in accurate transcription for Gulf Arabic dialects.
- →Single-weight multilingual support simplifies deployment across five languages.
- →Open weights allow developers to fine-tune or self-host without vendor lock-in.

The Technology Innovation Institute (TII) has released Falcon-ASR, a 1.6 billion parameter speech recognition model optimized for Arabic dialects, particularly Emirati. The model achieves a 20.92% Word Error Rate (WER) across six Arabic test sets and outperforms competitors like Qwen3-Omni on internal Emirati evaluations. Built on the Falcon3-Audio architecture, it supports English, French, Spanish, and Portuguese using a single set of weights without language-specific flags. A Hugging Face demo is available for testing.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1OpenAI Unveils New Voice Models for ChatGPT
TechCrunch AI · July 8, 2026 · Background
- 2NVIDIA Magpie TTS Enhances Multilingual Voice Agents
Hugging Face Blog · August 10, 2026 · Related
- 3Open ASR Leaderboard Adds Hindi Language
Hugging Face Blog · August 28, 2026 · Related
Follow this story
Open the full story →Falcon-Emirati-7B targets dialect nuance
2 developments
- Oct 6 · Hugging Face Blog
Falcon-Emirati-7B targets dialect nuance - Oct 7 · Hugging Face Blog
Falcon-ASR targets Emirati dialect with open weights (This article)↳ TII releases Falcon-ASR with 20.92% WER and superior Emirati accent recognition in a single multi-language model.
More from Hugging Face Blog
 © Hugging Face Blog
General AIother
Ai2 replaces priority scheduling with GPU time budgets
Allen Institute for AI solved the 'tragedy of the commons' in its H100 and B200 clusters by abandoning priority queues for a budget-based system. Researchers now spend allocated GPU time rather than hoarding it, turning resource allocation into a transparent administrative process. This shift eliminates squatting and priority inflation while keeping occupancy high through hierarchical fair-share scheduling. It proves that treating compute as a financial asset works better than treating it as a shared utility.
Hugging Face Blog
 © Hugging Face Blog
Coding Toolscoding
ML-Intern: Autonomous AI Agent for Model Training
Hugging Face’s ML-Intern agent proves that autonomous model training is no longer theoretical. By handling dataset curation, hyperparameter tuning, and cost management with a single prompt, it produced six distinct fine-tuned models in days for under $50 total. This shifts the barrier from engineering complexity to prompt precision, allowing developers to iterate on specialized capabilities like camera-angle LoRAs or domain-specific vision without manual infrastructure overhead. The real shift is the democratization of custom model creation, turning what used to be a week-long engineering sprint into a low-cost, automated workflow.
Hugging Face Blog
 © Hugging Face Blog
Models & Labsmodels
Liquid AI opens d1 decision models for edge inference
Liquid AI is shifting the paradigm from token-by-token generation to single-pass decision making with its new open-weight d1 models. The d1-3B model achieves top-tier performance on the Decision Index while answering queries in under 50ms on NVIDIA Jetson hardware, a stark contrast to the latency of traditional LLMs. By leveraging Liquid Foundation Models, these systems bypass autoregressive decoding entirely, enabling real-time multimodal classification for text, vision, and audio directly on edge devices. This approach offers a viable alternative for low-latency enterprise tasks where generative models are too slow or resource-heavy.
Hugging Face Blog
More in Models & Labs
Models & Labsmodels
llama.cpp b11535 release with ROCm 10 and CUDA 13
This release quietly cements llama.cpp as the universal inference runtime by adding default support for ROCm 10.0 and CUDA 13.4 across Linux and Windows. AMD GPU users finally get parity with NVIDIA's latest driver stack without manual configuration, while Apple Silicon KleidiAI builds are temporarily disabled to resolve stability issues. The inclusion of Snapdragon NPU support on Linux signals a serious push into edge AI hardware beyond just x86 and ARM CPUs. It is less about new features and more about ensuring the toolchain keeps pace with the rapidly evolving GPU landscape.
llama.cpp Releases
Models & Labscoding
llama.cpp b11540 adds ROCm 10 and CUDA 13 support
This release quietly closes the hardware gap for local inference by adding default builds for ROCm 10.0 and CUDA 13.4 across Linux and Windows. AMD users finally get parity with NVIDIA in the binary distribution, while CUDA 13 support future-proofs setups on newer drivers. The inclusion of Snapdragon and OpenVINO binaries further broadens the hardware surface area without requiring custom compilation. It is a pragmatic update that makes llama.cpp the most accessible runtime for diverse local AI hardware.
llama.cpp Releases
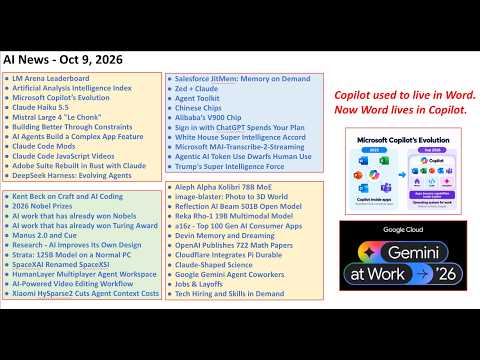 © Lev Selector
Models & Labsmodels
Mistral Large 4 and Claude Haiku 5.5 Released
Mistral releases Large 4 'Le Chonk' while Anthropic launches Claude Haiku 5.5, continuing the trend of cheaper, faster frontier models.
Lev Selector