Models & Labs
llama.cpp b11540 adds ROCm 10 and CUDA 13 support
llama.cpp Releaseshigh confidence
Why it matters
- →ROCm 10.0 support brings AMD GPU users to parity with CUDA in official binary distributions.
- →CUDA 13.4 compatibility ensures llama.cpp works with the latest NVIDIA driver stacks out of the box.
- →Snapdragon and OpenVINO binaries expand local inference capabilities to mobile and edge devices.
llama.cpp has released build b11540, expanding binary support to include ROCm 10.0 and CUDA 13.4 libraries on Linux and Windows. The release also adds binaries for Qualcomm Snapdragon devices and OpenVINO, while disabling KleidiAI on macOS Apple Silicon and openEuler builds. This update ensures compatibility with the latest NVIDIA driver stacks and AMD ROCm versions without requiring users to compile from source. The expansion significantly lowers the barrier for running local models on non-NVIDIA hardware.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1llama.cpp b11028 adds CUDA 13 and ROCm 10.0 support
llama.cpp Releases · September 18, 2026 · Same story
- 2llama.cpp b11045 adds CUDA 13 and ROCm 10.0 builds
llama.cpp Releases · September 19, 2026 · Same story
More from llama.cpp Releases
Coding Toolscoding
llama.cpp b11532 adds ModernBERT and CUDA 13
This release quietly fixes a critical accuracy gap for ModernBERT encoders by implementing exact GELU activation, ensuring semantic embeddings match the original PyTorch models rather than approximations. It also brings native support for CUDA 13.4 across Linux and Windows, closing the driver compatibility lag that has plagued NVIDIA users on newer hardware stacks. While KleidiAI builds are temporarily disabled on Apple Silicon, the broader expansion to ROCm 10.0 and Snapdragon NPU keeps llama.cpp as the most versatile local inference runtime available today.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11533 fixes Adreno A6X crashes
This release targets a specific but painful stability issue for Android users running llama.cpp on Qualcomm Adreno A6X GPUs. The kernel compiler was crashing due to argument limits in the iot device backend, effectively breaking local inference on those chips. By skipping the problematic kernel and adding explicit detection for the Adreno 623, the team restores functionality where it previously failed hard. It’s a narrow fix, but essential for anyone trying to run models on mid-range Android hardware without hitting compiler errors.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11534 optimizes CUDA SSM and adds ROCm 10
This release quietly sharpens llama.cpp’s performance on NVIDIA GPUs by fusing state snapshot copies into the recurrent cache during SSM scans. It also removes redundant CUDA copies in specific non-speculative decoding scenarios, shaving off latency where it counts. On the AMD side, ROCm 10.0 support arrives alongside stable builds for CUDA 12.8 and 13.4, keeping the library competitive across hardware vendors. KleidiAI on Apple Silicon is temporarily disabled, a minor setback for Mac users until that integration is stabilized. The net result is faster inference for SSM-based models without changing the user experience.
llama.cpp Releases
More in Models & Labs
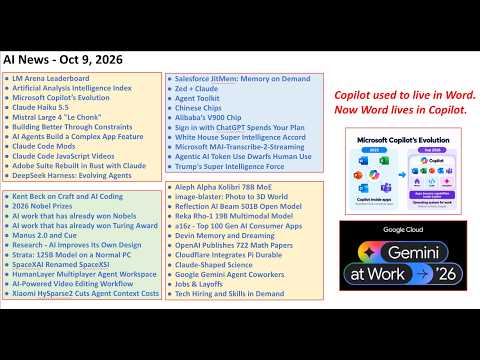 © Lev Selector
Models & Labsmodels
Mistral Large 4 and Claude Haiku 5.5 Released
Mistral releases Large 4 'Le Chonk' while Anthropic launches Claude Haiku 5.5, continuing the trend of cheaper, faster frontier models.
Lev Selector
 © Matt Wolfe
Models & Labsmodels
OpenAI Introduces GPT-6 and Intelligent UI
OpenAI announced GPT-6 for everyone, featuring an 'Intelligent UI' that adapts to user context and workflow needs.
Matt Wolfe
© Matt WolfeModels & Labsmodels
Mistral Releases Large Model 4
French AI startup Mistral has released Mistral Large 4, its latest flagship model competing with top-tier US counterparts.
Matt Wolfe