Coding Tools
llama.cpp b11039 fixes SWA pattern roundtrip
llama.cpp Releaseshigh confidence
Why it matters
- →Fixes silent precision loss in SWA models like OLMo2 and Gemma3n by correctly parsing per-layer attention patterns.
- →Enables bit-exact roundtrips for diverse architectures, ensuring converted GGUFs match original checkpoint behavior.
- →Expands Model-Saver support to include complex models like Plamo3 and Cohere2 with MLA geometry preservation.
llama.cpp version b11039 addresses a critical inconsistency in handling sliding window attention (SWA) patterns during model serialization. The update modifies loaders to correctly interpret SWA patterns as either scalar periods or per-layer arrays, preventing silent fallbacks to defaults for models like OLMo2 and Gemma3n. Concurrently, the Model-Saver now explicitly writes these patterns alongside MLA key/value lengths, enabling bit-exact roundtrips for over a dozen architectures including Plamo3, Cohere2, and Exaone-MoE. This ensures that converted GGUF files maintain precise inference fidelity compared to their original checkpoints.
Read originalMore from llama.cpp Releases
Coding Toolscoding
llama.cpp b11036 adds CUDA 13 and ROCm 10.0
This release quietly closes the hardware gap for local inference by adding default builds for CUDA 13 and ROCm 10.0. NVIDIA users on newer driver stacks can finally run without workarounds, while AMD GPU owners get parity with the latest ROCm version. Apple Silicon support is explicitly disabled in this build, a notable regression for Mac users who need to wait for the next patch. The inclusion of OpenVINO and SYCL builds further cements llama.cpp as the universal runtime for diverse hardware, ensuring no major accelerator is left behind.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11037 fixes GPU inference bugs
This release prioritizes stability over new features, addressing critical correctness issues in vector handling for GET_ROWS operations. By fixing vec4 alignment checks and updating CUDA libraries to versions 12.8 and 13.3, it ensures reliable performance across NVIDIA hardware on both Linux and Windows. The inclusion of ROCm 10.0 builds further solidifies AMD GPU support without requiring complex configuration. While no new model architectures are added, these fixes prevent silent corruption in local inference tasks that could otherwise go unnoticed.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11040 release with CUDA 13 and ROCm 10
This is a routine maintenance release for llama.cpp, prioritizing stability over new features. The most notable technical shift is the addition of CUDA 13 builds alongside existing CUDA 12 support, giving users access to newer NVIDIA driver stacks without waiting for major version bumps. ROCm 10.0 support remains available for AMD GPU inference, maintaining parity with previous releases. KleidiAI on Apple Silicon has been explicitly disabled in this build, likely due to stability concerns or testing requirements. There are no new model architectures or quantization methods introduced here.
llama.cpp Releases
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.277 fixes critical bugs and adds AGENTS.md
This release stabilizes Claude Code by patching a cascade of crashes and session hangs that plagued recent versions. The most notable functional shift is the fallback to AGENTS.md when CLAUDE.md is absent, aligning with broader industry standards for agent configuration. Gateway improvements allow better proxy handling for egress-bound environments, while numerous fixes address edge cases in file editing, plugin management, and resume functionality. It’s a maintenance-heavy update that restores reliability rather than introducing new capabilities.
Claude Code Releases
Coding Toolscoding
Claude Code v2.1.278 optimizes auto-mode billing
Anthropic quietly fixed a cost leak in Claude Code’s auto mode. By defaulting to the server-side classifier for API and enterprise users, the update eliminates charges for classifier overhead that previously bled into session costs. This shift means developers no longer pay double for the same logic, while still retaining the ability to opt out via environment variables if needed. The change is a subtle but necessary correction to pricing transparency in automated coding workflows.
Claude Code Releases
 © GitHub Changelog
Coding Toolscoding
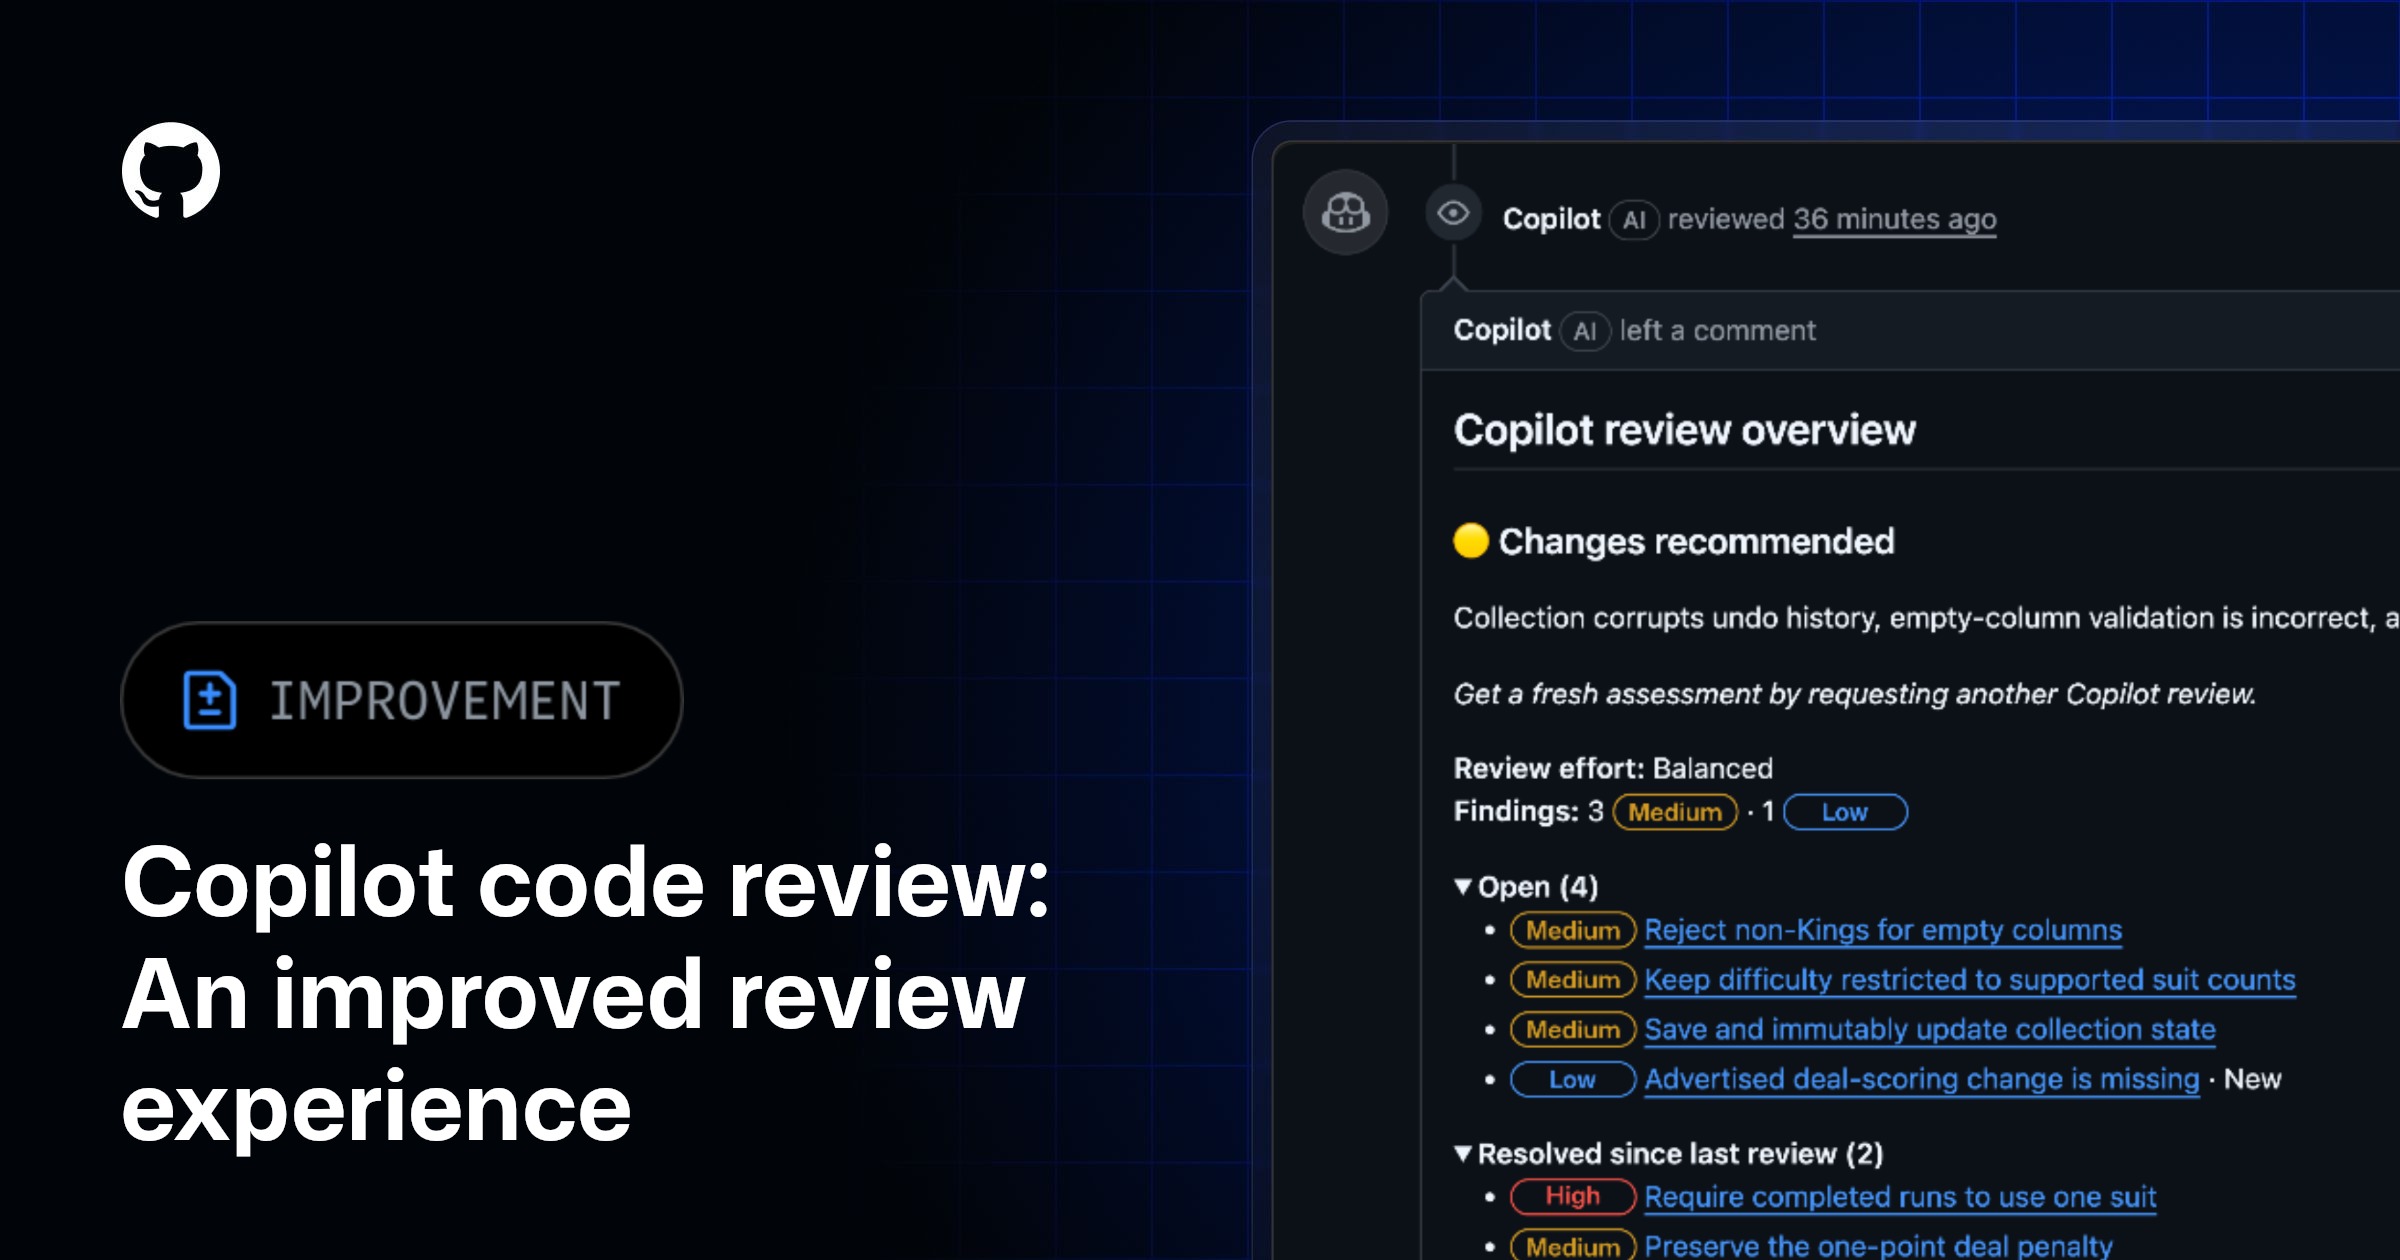
GitHub Copilot Code Review GA with Auto-Resolution
GitHub Copilot’s code review tool has reached general availability, shifting from experimental to a core part of the pull request workflow. The biggest leap is auto-resolution: Copilot now validates whether its own suggestions were actually fixed by subsequent commits and closes them out automatically, saving developers from manual cleanup. It also groups findings into clear states like 'Resolved' or 'Previously missed,' giving a real-time health check of the PR rather than just a static list of errors. This reduces context switching significantly, letting engineers focus on new issues while the AI handles the administrative burden of closing old ones.
GitHub Changelog