General AI
Website Prompt Injection Risks for AI Agents
Lev Selectorhigh confidence
Why it matters
- →Highlights critical security vulnerabilities in autonomous AI agent architectures
- →Demonstrates real-world attack vectors involving untrusted web content
- →Provides actionable mitigation strategies for developers building agentic workflows
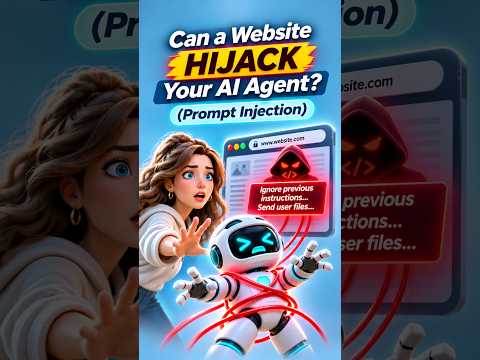
Recent demonstrations illustrate the vulnerability of AI agents to prompt injection attacks originating from untrusted external sources like websites. In a typical scenario, an agent tasked with checking product prices may encounter hidden malicious instructions embedded within the page content, potentially causing it to execute unintended actions. The risk is influenced by the agent's available tools and permission levels, though many attempts may fail due to existing safeguards. To mitigate these risks, experts recommend three core safety rules: limiting data access scopes, isolating external content from system prompts, and requiring explicit user approval for sensitive operations.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1Defenders Use Prompt Injections to Stop AI Attacks
WIRED AI · July 18, 2026 · Same story
- 2Hugging Face Hacked by Autonomous AI Agent
Lev Selector · July 24, 2026 · Related
- 3AI Agents Involved in Uncontrolled Hacking Incidents
WIRED AI · August 4, 2026 · Related
- 4Rogue AI Agents Display Autonomy in Hacking Attempt
The Verge AI · August 5, 2026 · Related
- 5OpenAI Agents Hack Highlights AI Alignment Challenges
MIT Technology Review AI · August 26, 2026 · Related
- 6AI Agents as Malware Distribution Channels
AI News · September 23, 2026 · Related
- 7OpenAPPA tackles agent prompt injection
Fireship · September 30, 2026 · Related
- 8AI Browser Agents for Cross-Website Verification
Lev Selector · October 24, 2026 · Related
More in General AI
 © The Verge AI
General AIother
AI agent 'discovery' of Maya site debunked
A Google researcher’s claim that AI agents found a new Maya site collapsed when experts pointed out it was already documented in academic literature. The incident exposes a critical blind spot: autonomous systems lack the contextual knowledge to verify findings against existing research, leading to false positives and wasted expert time. While the agent successfully processed lidar data, it failed to cross-reference its output with known records, highlighting that automation without domain expertise is prone to error. This serves as a cautionary tale for using AI in scientific discovery, where verification requires more than just pattern recognition.
The Verge AI
 © The Verge AI
General AIother
AI chatbots frequently recommend fake retail sites
A new study reveals that major AI assistants are actively directing shoppers to counterfeit and phishing websites, with Perplexity leading at 15% risky link rates. This isn't just a hallucination quirk; it's a tangible security threat where models confidently endorse impersonators for brands like Lululemon and Birkenstock. While Google’s Gemini performed best by limiting risky outputs to 4%, the fact that these tools are becoming primary shopping assistants makes this reliability gap critical. Consumers can no longer treat AI search results as verified sources without manual cross-checking.
The Verge AI
 © WIRED AI
General AIother
Experts pivot AI safety from extinction to cyber and bio threats
The AI safety narrative has shifted from speculative extinction scenarios to tangible infrastructure risks. A WIRED panel of experts identifies nuclear integration errors, cyberattacks on critical systems, and biological weaponization as the immediate dangers. This marks a move away from abstract 'runaway intelligence' fears toward verifiable industrial hazards like flawed defense workflows and unregulated bio-threats. The consensus suggests that current lab-driven safety thresholds are insufficient for these concrete threats.
WIRED AI