Coding Tools
llama.cpp adds FP8 KV-cache support
llama.cpp Releaseshigh confidence
Why it matters
- →Reduces VRAM usage for KV cache by approximately 50% compared to BF16.
- →Enables longer context windows on consumer GPUs that previously lacked sufficient memory.
- →Maintains inference quality while significantly lowering hardware requirements for large models.
The llama.cpp project has merged support for FP8 Key-Value (KV) cache storage, a change aimed at reducing memory consumption during inference. This update allows the KV cache to be stored in 8-bit floating point format instead of the previous BF16 standard, effectively halving the VRAM required for context retention. The implementation includes comprehensive testing across various backends including CUDA, ROCm, and Apple Silicon, ensuring stability for both scaled and unscaled configurations. This release enables users to maintain larger context windows on hardware with limited memory capacity.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1llama.cpp b10068 release focuses on K/V cache
llama.cpp Releases · July 19, 2026 · Same story
- 2llama.cpp b10594 release optimizes GPU resource use
llama.cpp Releases · August 24, 2026 · Same story
Follow this story
Open the full story →llama.cpp b12059 optimizes unified KV cache for multi-sequence
3 developments
- Nov 3 · llama.cpp Releases
llama.cpp b12059 optimizes unified KV cache for multi-sequence - Nov 7 · llama.cpp Releases
llama.cpp adds Kimi K3.1-Pro support↳ llama.cpp adds Kimi K3.1-Pro support using DSA and linear-attention KDA layers - Nov 11 · llama.cpp Releases
llama.cpp adds FP8 KV-cache support (This article)↳ llama.cpp adds FP8 KV-cache support, cutting VRAM usage by half compared to BF16 without sacrificing quality
More from llama.cpp Releases
Coding Toolscoding
llama.cpp b12336 fixes HunyuanVL crash
This release quietly patches a critical memory overflow in the mtmd module that caused crashes when loading HunyuanVL models. The issue stemmed from F64 position embeddings overflowing an F32 buffer, a subtle bug that broke multimodal inference for users relying on this specific architecture. By enforcing strict F32 requirements, llama.cpp stabilizes support for Tencent's vision-language model without adding new features or changing the core API. It’s a necessary maintenance update that keeps local multimodal workflows from breaking unexpectedly.
llama.cpp Releases
Models & Labsother
llama.cpp b12340 adds CUDA 13 and ROCm 10.0
This release quietly closes the hardware gap for local inference by adding default support for CUDA 13 and ROCm 10.0 across Linux and Windows. Users with newer NVIDIA GPUs or AMD accelerators no longer need to compile from source to get performance, while Apple Silicon builds now ship KleidiAI disabled by default, shifting the focus back to standard ARM optimizations. The inclusion of Snapdragon support for Linux and Android marks a significant step toward on-device AI beyond the x86/ARM desktop ecosystem. It is less about new features and more about ensuring llama.cpp remains the universal runtime for every available accelerator.
llama.cpp Releases
Models & Labscoding
llama.cpp b12342 adds few-row MMQ for speculative decoding
Speculative decoding just got a significant speed boost on NVIDIA GPUs. This release introduces a specialized kernel for 'few-row' matrix multiplications, targeting the small batch sizes typical of verification passes in speculative decoding workflows. By optimizing these specific operations for quantized formats like Q8_0 and IQ4 variants, llama.cpp reduces latency where it matters most during token generation. The change is CUDA-only for now but leverages hardware capabilities from Ampere onwards, making local inference faster without requiring new model architectures or complex configuration changes.
llama.cpp Releases
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.323 adds experimental Code Mode and plugin safety
This release quietly introduces Code Mode, an opt-in feature where Claude writes JavaScript to call its own tools, marking a shift toward more autonomous agent-like behavior within the CLI. The update also hardens the plugin ecosystem by enforcing version ranges and adding strict TypeScript type checking for hooks, which should significantly reduce instability from third-party extensions. Beyond these features, the changelog is dominated by critical fixes for authentication drift in background sessions and memory leaks when handling large files, stabilizing the tool for heavy enterprise use.
Claude Code Releases
 © GitHub Changelog
Coding Toolscoding
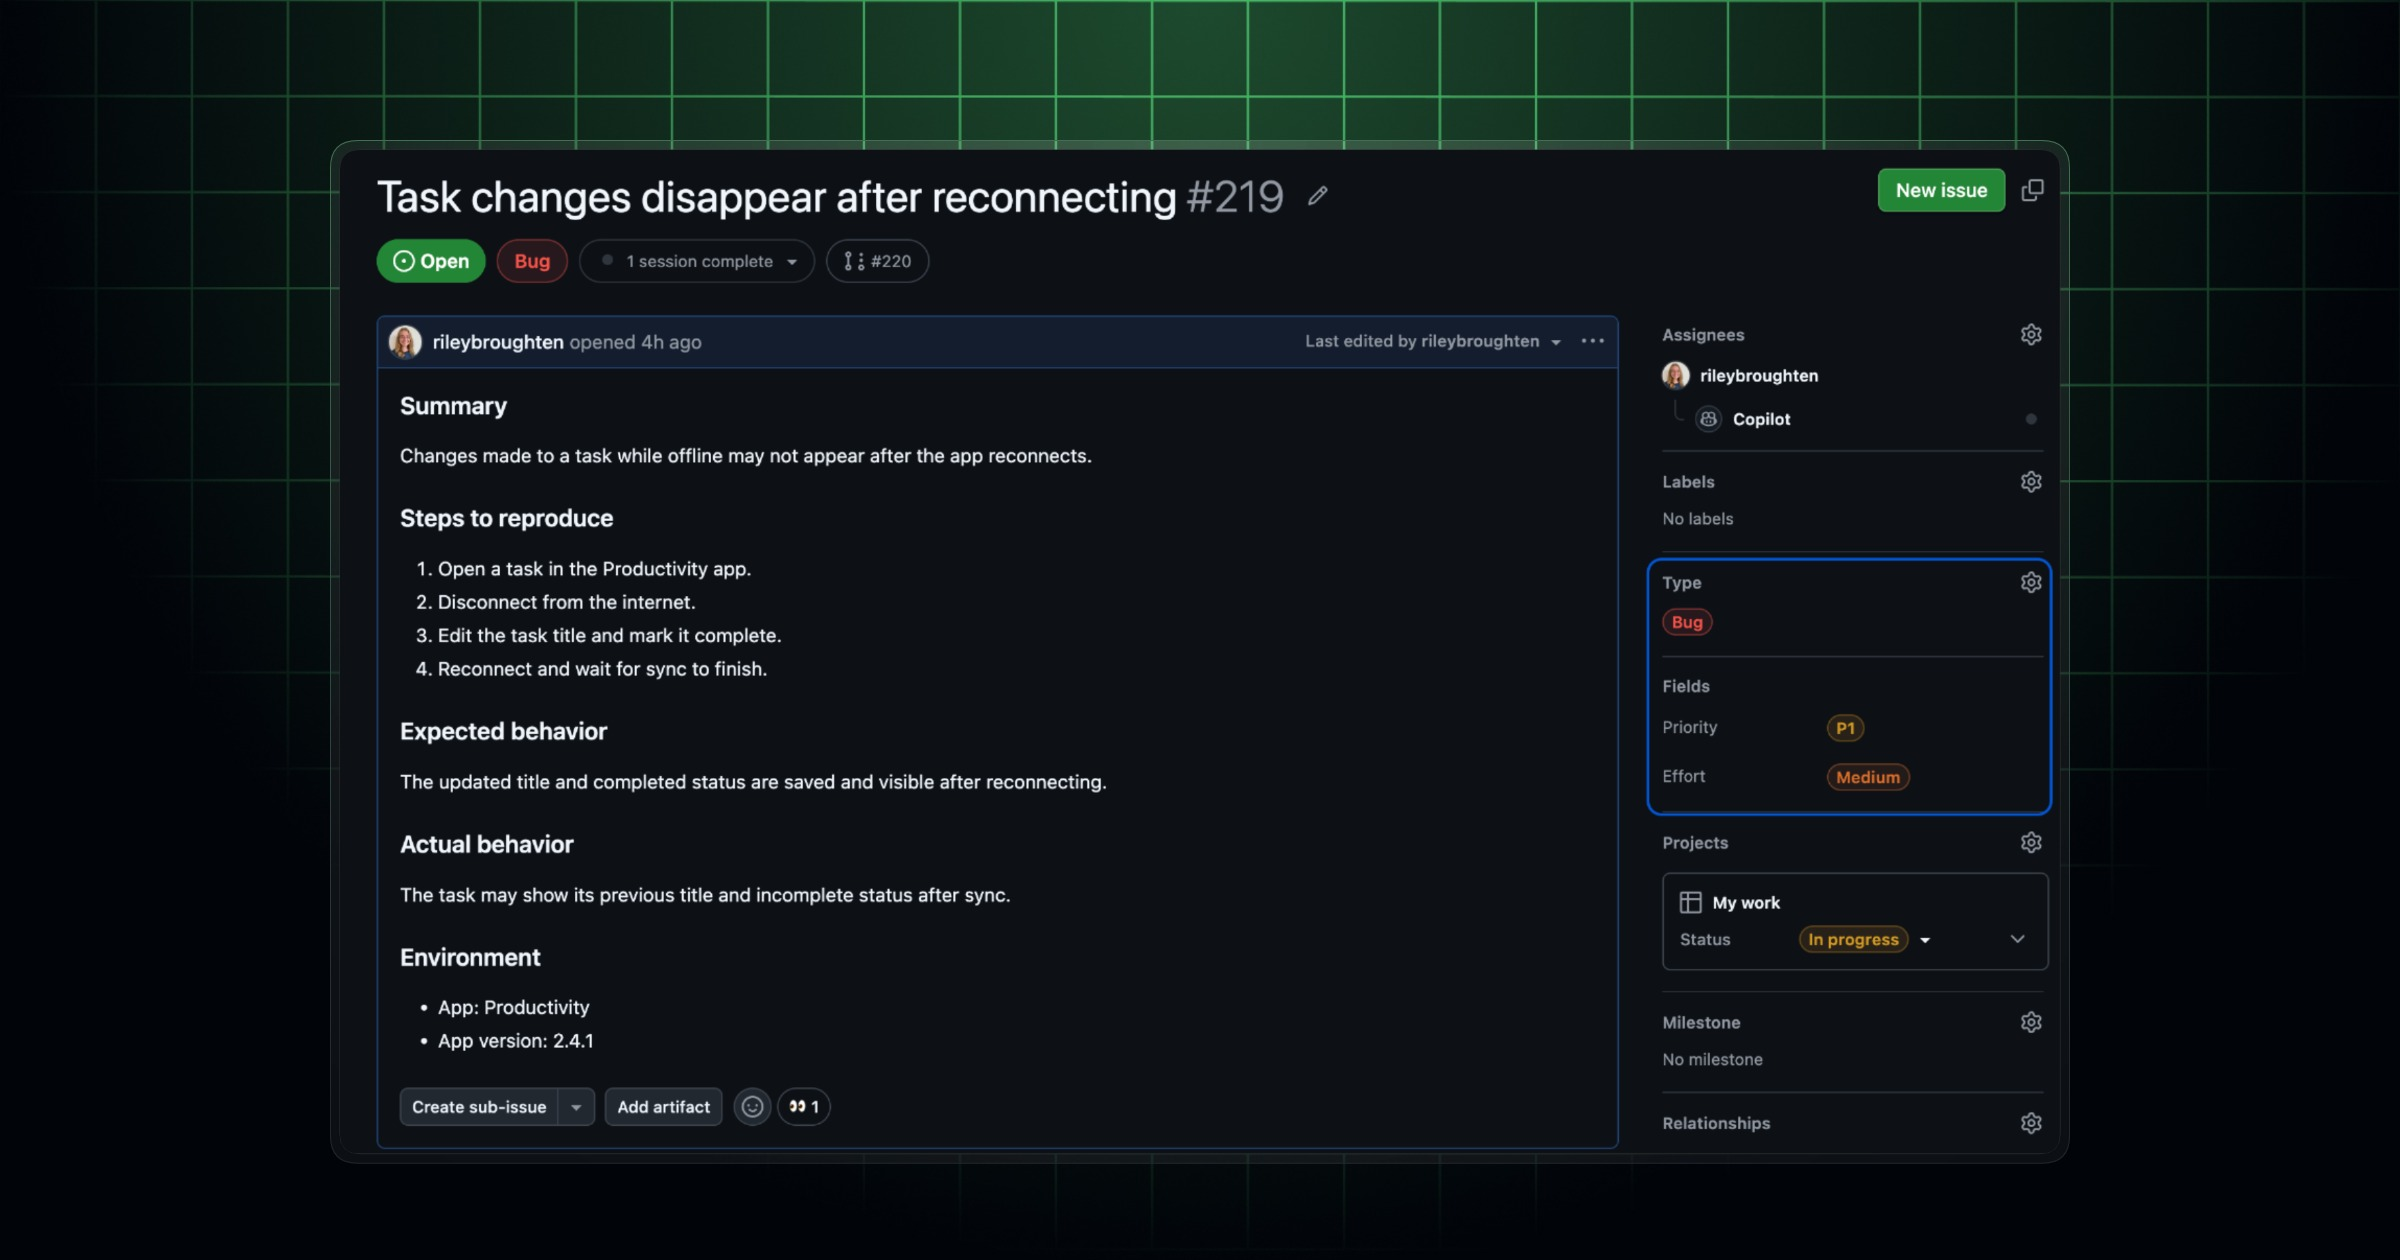
GitHub expands issue types to personal accounts
GitHub finally brings enterprise-grade planning structures to individual developers. Personal repositories now support customizable issue types and fields, allowing solo maintainers to standardize workflows with up to 25 distinct categories. This closes a long-standing gap where only organizations could enforce structured data schemas for bug tracking and feature management. The move signals that GitHub is treating personal open-source projects with the same operational seriousness as corporate codebases.
GitHub Changelog
Coding Toolscoding
Claude Code v2.1.321 patches security and stability
This release quietly shifts the default Fable model to version 5.2 with a generous 1M context window, making long-context coding significantly more viable without manual configuration. More critically, it addresses several security gaps in MCP OAuth handling and sandbox permission checks that could have exposed sensitive tokens or bypassed safety protocols. The update also stabilizes Remote Control and background agent interactions, fixing issues where sessions would hang or lose state during network interruptions. For developers relying on Claude Code for complex, multi-step workflows, this patch reduces the friction of managing long-running tasks and ensures safer execution environments.
Claude Code Releases