Coding Tools
llama.cpp b11054 adds Hexagon TOP_K support
llama.cpp Releaseshigh confidence
Why it matters
- →Enables TOP_K sampling on Qualcomm Hexagon DSPs, improving local inference quality on mobile devices.
- →Updates CUDA and ROCm support to match latest driver versions, preventing compatibility issues.
- →Maintains parity between mobile and desktop inference capabilities in the llama.cpp ecosystem.
llama.cpp has released version b11054, primarily focusing on enabling TOP_K sampling operations for Qualcomm Hexagon DSPs. This addition allows more sophisticated text generation strategies on Snapdragon-based devices, which previously lacked this specific sampling method. The release also updates backend libraries to support CUDA 12.8/13.3 and ROCm 10.0, ensuring compatibility with recent GPU driver releases. Additionally, minor optimizations were applied to TOP_K row partitioning for Hexagon processors.
Read originalMore from llama.cpp Releases
Coding Toolscoding
llama.cpp b11050 adds CUDA 13 and ROCm 10.0 support
This release quietly closes the hardware gap for local inference by adding native support for CUDA 13 and ROCm 10.0 across Linux and Windows builds. Users with newer NVIDIA GPUs or AMD accelerators no longer need to compile from source to get performance, as these binaries are now pre-packaged. The inclusion of OpenVINO and SYCL variants further broadens the pool of compatible hardware beyond just NVIDIA and AMD. While Apple Silicon support is present, KleidiAI has been disabled in this specific build, likely due to stability checks. This is a practical update that keeps llama.cpp relevant as hardware vendors push new driver standards.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11052 adds CUDA 13 and ROCm 10 builds
This release quietly extends llama.cpp's hardware support to the latest NVIDIA and AMD driver stacks. By shipping native binaries for CUDA 13 and ROCm 10, it removes the friction of manual compilation for users on bleeding-edge GPUs. Apple Silicon KleidiAI is explicitly disabled here, a deliberate choice that likely prioritizes stability over new acceleration features for this specific build. The real value lies in the breadth: with Vulkan, OpenVINO, and SYCL options across Linux and Windows, it remains the most versatile local inference runtime available. Users on newer hardware can finally run pre-built binaries without hunting for custom compile flags.
llama.cpp Releases
Coding Toolscoding
llama.cpp b11055 adds CUDA 13 and ROCm 10 builds
This release quietly extends llama.cpp's hardware support to the latest NVIDIA and AMD stacks. By shipping native binaries for CUDA 13 and ROCm 10, it ensures compatibility with newer GPU architectures without requiring users to compile from source. The inclusion of both CUDA versions side-by-side is a pragmatic move for developers managing mixed environments. While no new model optimizations are highlighted, this update keeps the runtime relevant as hardware vendors push their latest drivers.
llama.cpp Releases
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.277 fixes critical bugs and adds AGENTS.md
This release stabilizes Claude Code by patching a cascade of crashes and session hangs that plagued recent versions. The most notable functional shift is the fallback to AGENTS.md when CLAUDE.md is absent, aligning with broader industry standards for agent configuration. Gateway improvements allow better proxy handling for egress-bound environments, while numerous fixes address edge cases in file editing, plugin management, and resume functionality. It’s a maintenance-heavy update that restores reliability rather than introducing new capabilities.
Claude Code Releases
Coding Toolscoding
Claude Code v2.1.278 optimizes auto-mode billing
Anthropic quietly fixed a cost leak in Claude Code’s auto mode. By defaulting to the server-side classifier for API and enterprise users, the update eliminates charges for classifier overhead that previously bled into session costs. This shift means developers no longer pay double for the same logic, while still retaining the ability to opt out via environment variables if needed. The change is a subtle but necessary correction to pricing transparency in automated coding workflows.
Claude Code Releases
 © GitHub Changelog
Coding Toolscoding
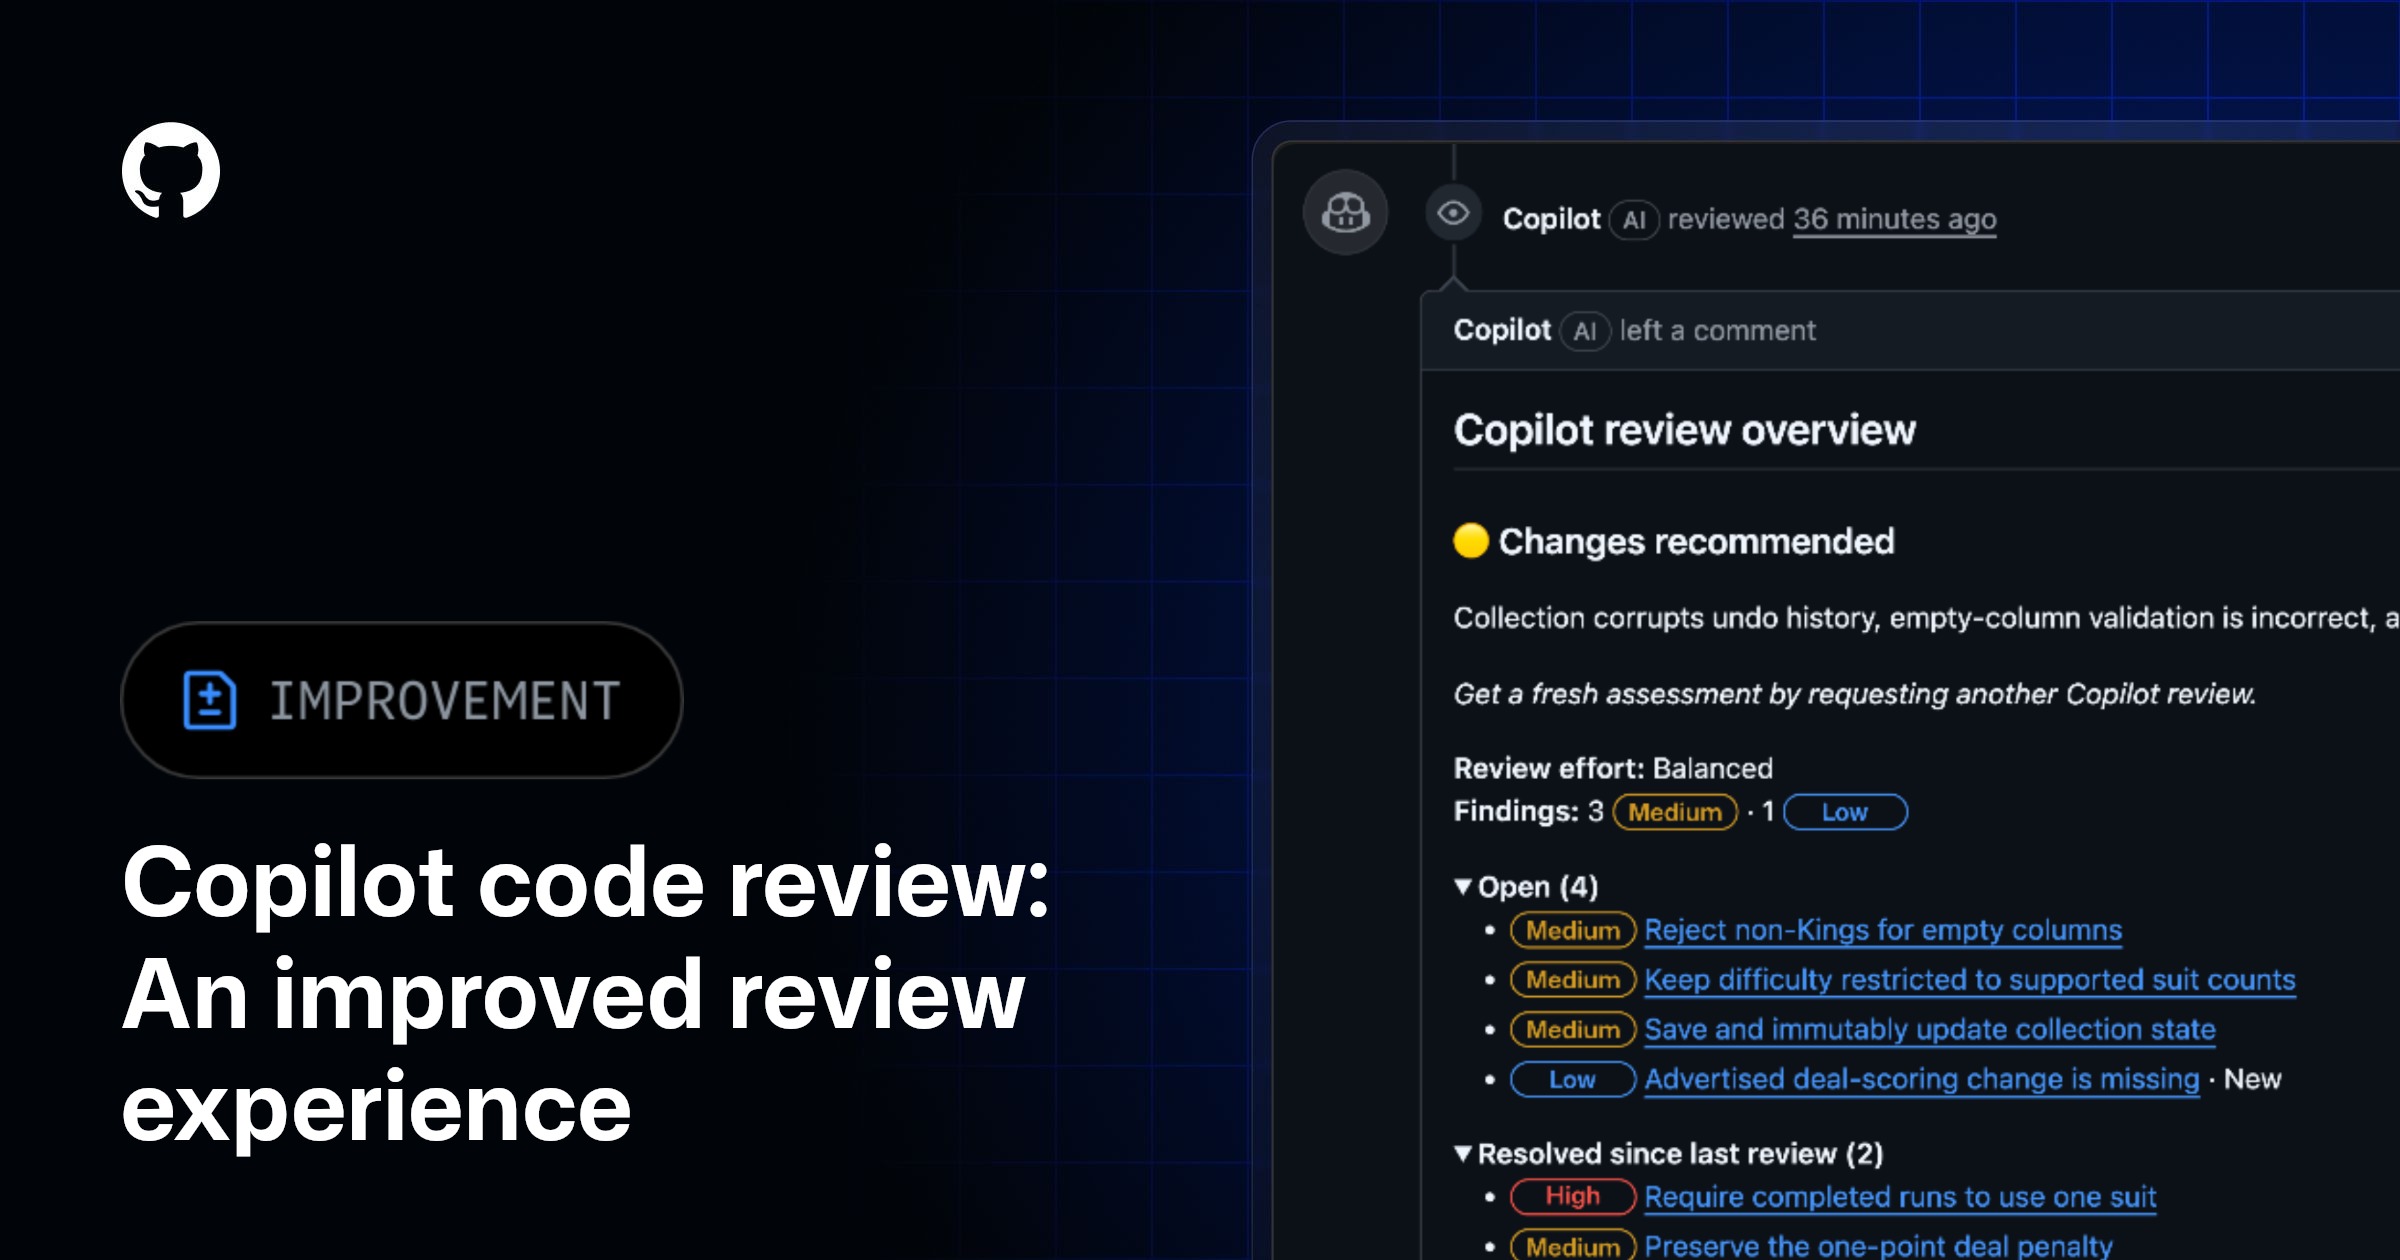
GitHub Copilot Code Review GA with Auto-Resolution
GitHub Copilot’s code review tool has reached general availability, shifting from experimental to a core part of the pull request workflow. The biggest leap is auto-resolution: Copilot now validates whether its own suggestions were actually fixed by subsequent commits and closes them out automatically, saving developers from manual cleanup. It also groups findings into clear states like 'Resolved' or 'Previously missed,' giving a real-time health check of the PR rather than just a static list of errors. This reduces context switching significantly, letting engineers focus on new issues while the AI handles the administrative burden of closing old ones.
GitHub Changelog