Coding Tools
GitHub Actions retention now covers checks and runs
GitHub Changeloghigh confidence
Why it matters
- →Unifies retention policies for CI/CD metadata and artifacts, simplifying storage management.
- →Applies a consistent 90-day maximum cap for public repositories across all Actions data types.
- →Reduces administrative overhead by consolidating configuration into a single UI setting.
GitHub has expanded its Actions retention settings to include checks, workflow runs, and statuses, aligning them with existing artifact and log policies. The unified setting allows administrators to configure retention periods at the enterprise, organization, or repository level, subject to a maximum of 90 days for public repositories. This change automatically cleans up records that exceed the configured period and applies to data generated by both GitHub Actions and third-party applications. Previously removed data cannot be restored by changing these settings.
Read originalThe story around this
Earlier coverage that leads up to this article, and what followed. Lines connect each piece to the closest one after it, converging here.
How we got here
- 1GitHub CI Migrates to Hugging Face Jobs
Hugging Face Blog · June 9, 2026 · Background
- 2GitHub Actions Retention Policy Update Announced
GitHub Changelog · August 27, 2026 · Same story
- 3GitHub Actions: September 2026 Updates Released
GitHub Changelog · September 3, 2026 · Related
More from GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub rate limits private vulnerability reports
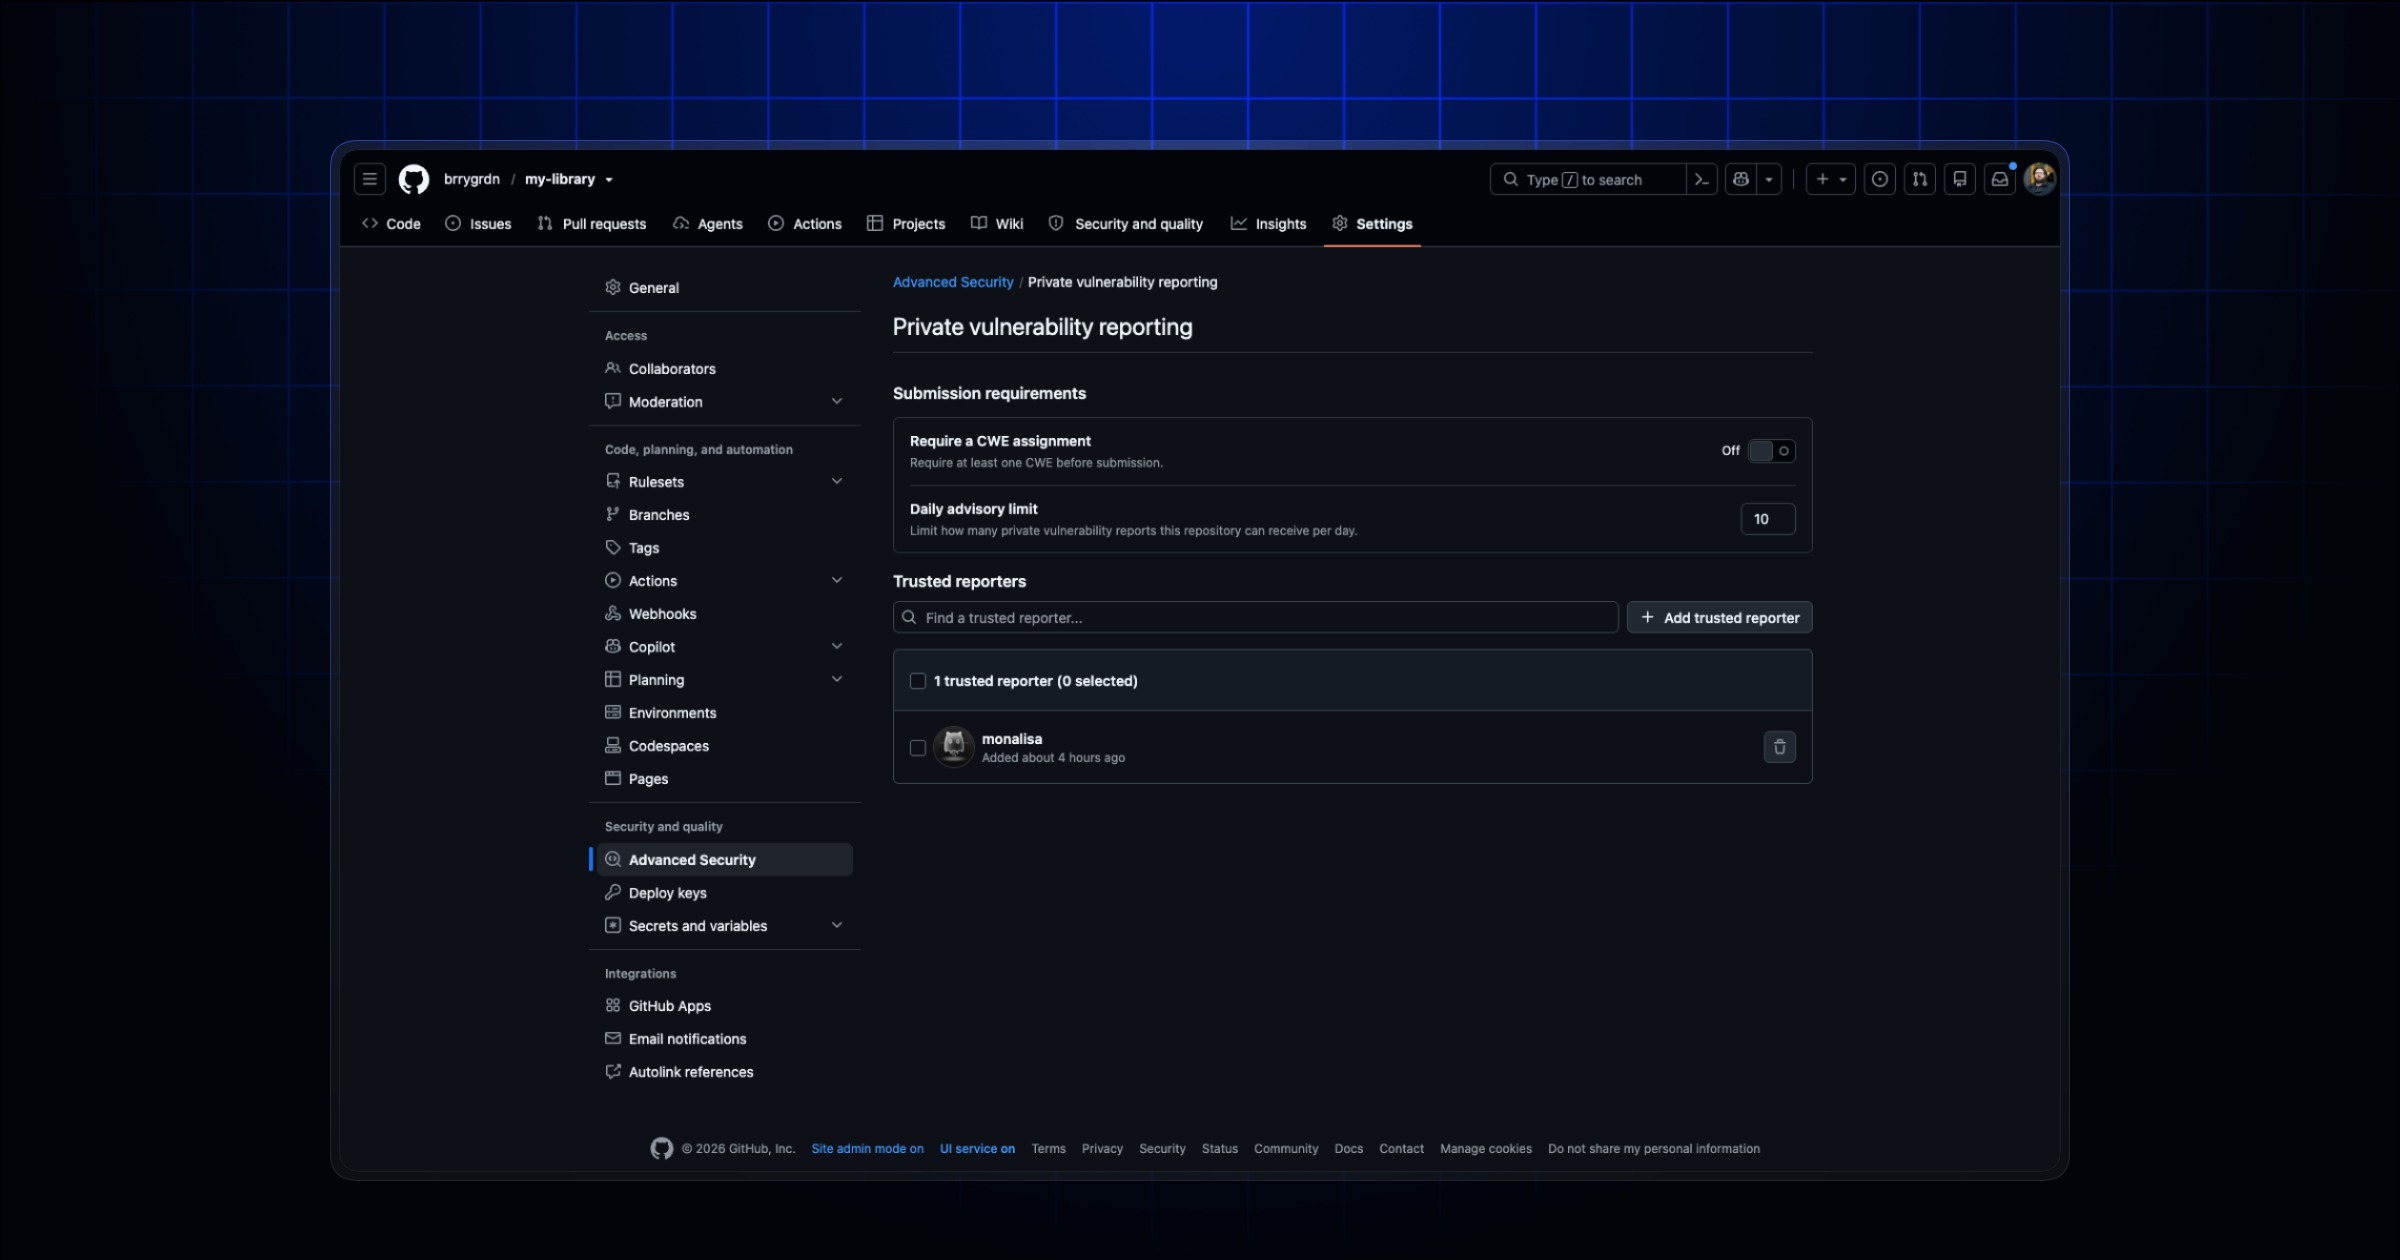
GitHub is finally capping the flood of automated junk hitting maintainers' inboxes. By enforcing daily per-user limits on new private vulnerability reports, the platform stops bad actors from burying legitimate security findings under noise. Admins can now set custom caps or whitelist trusted researchers, ensuring that actual threats get seen. This shifts the burden from manual triage to automated gating, protecting open source maintainers without blocking genuine disclosures.
GitHub Changelog
 © GitHub Changelog
Coding Toolscoding
GitHub enforces structured vulnerability reports
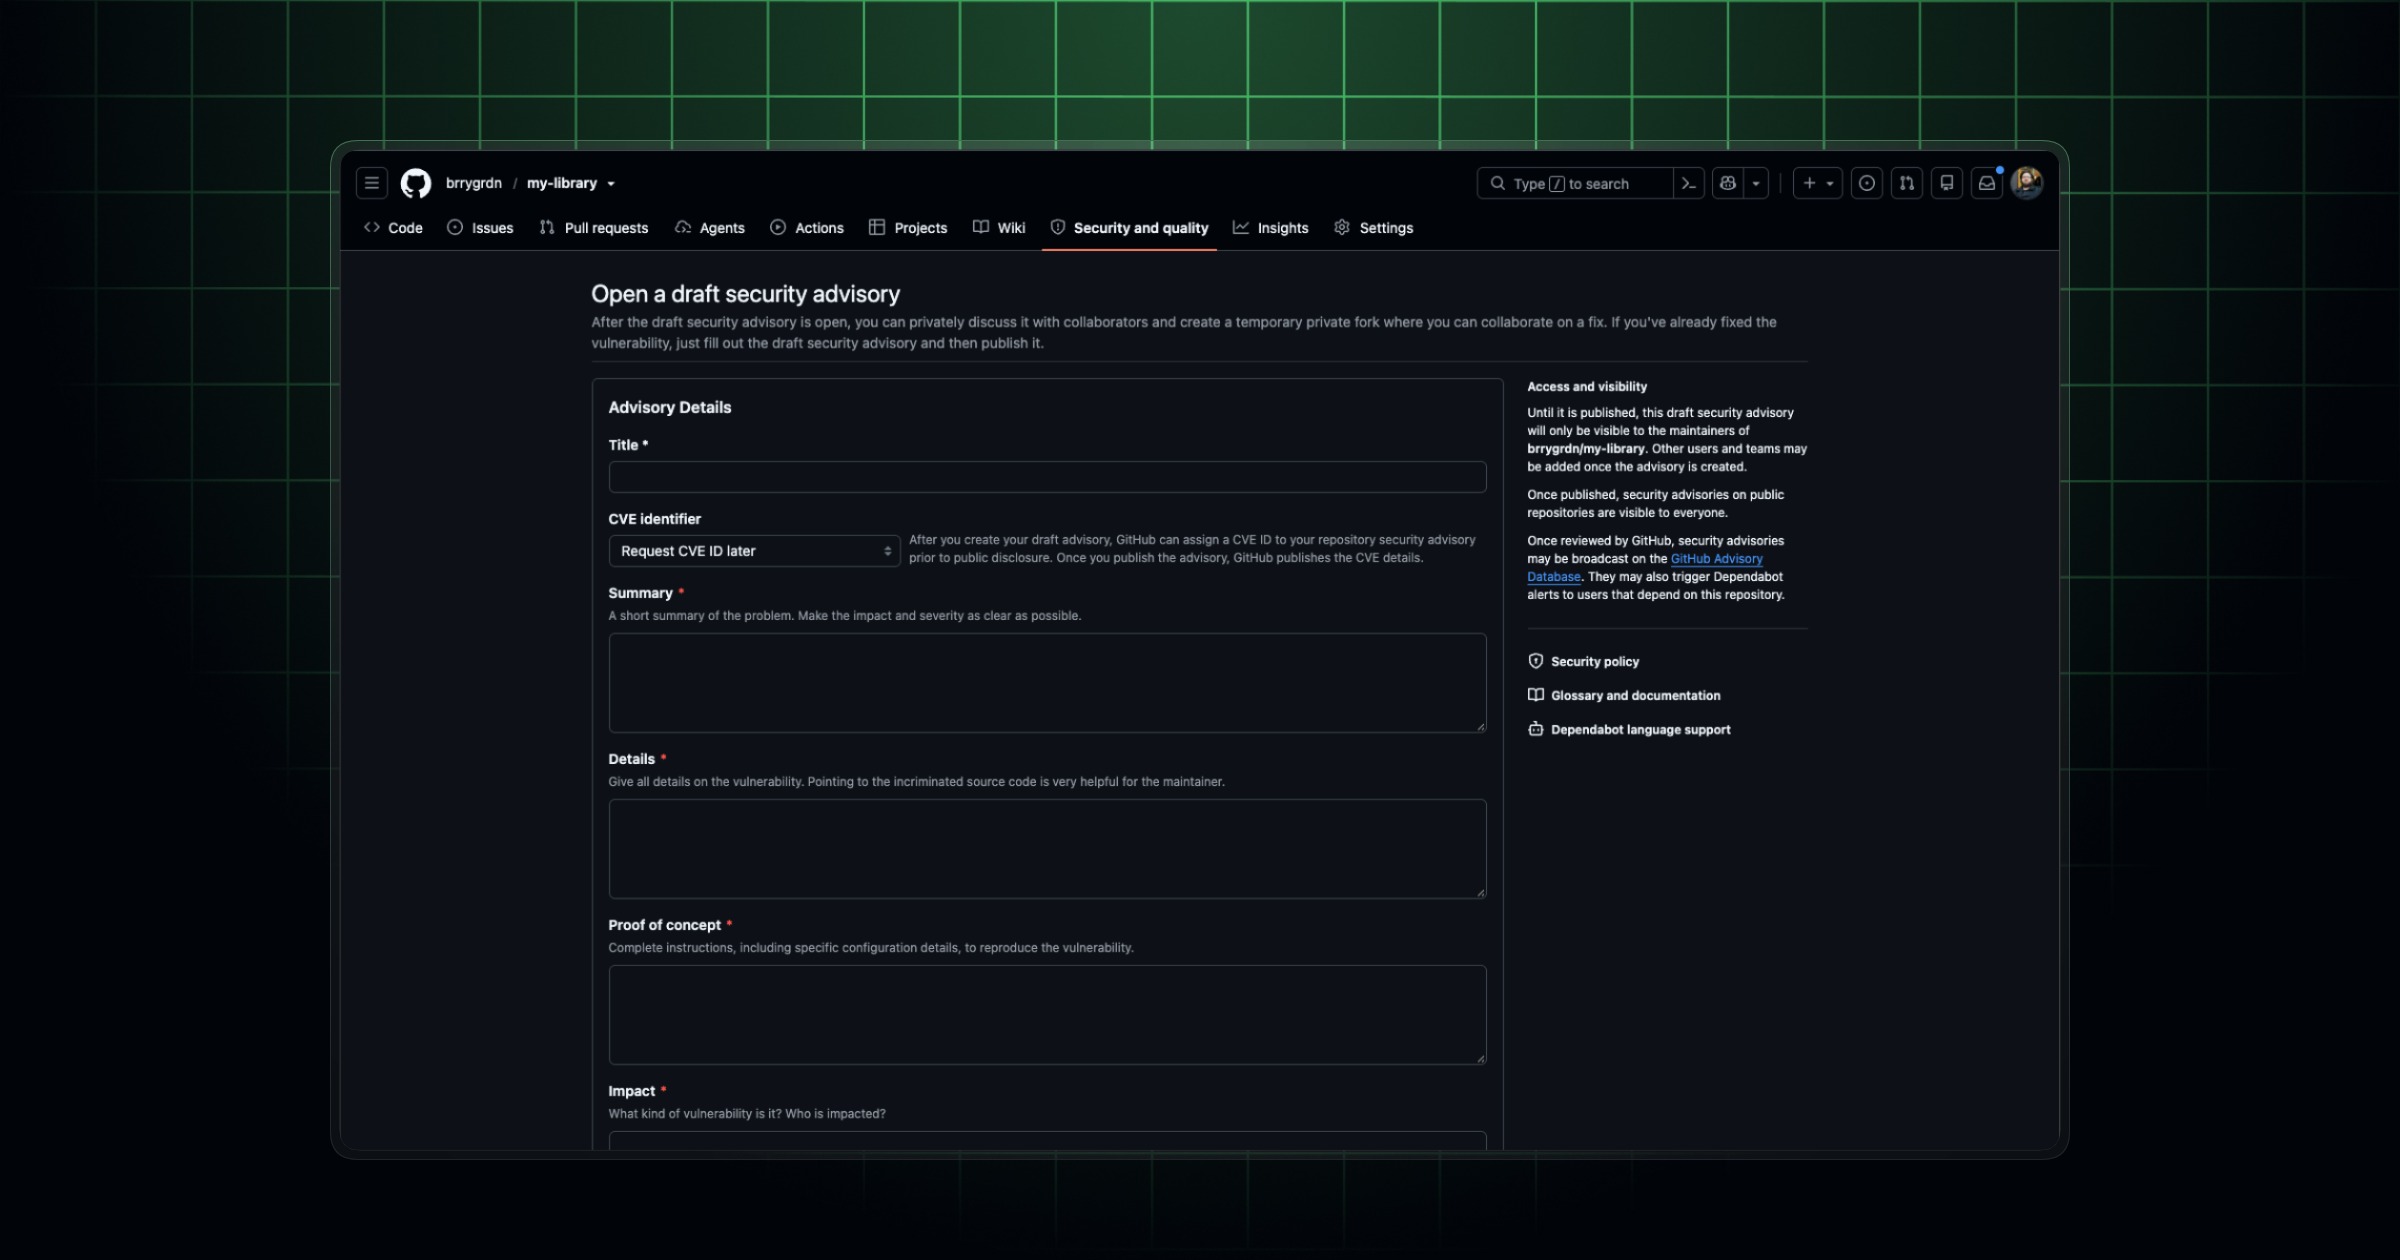
GitHub is killing the free-text black hole for private vulnerability reports by mandating structured fields. Reporters must now provide a summary, details, impact assessment, and a proof of concept with at least 150 characters, forcing signal over noise. The platform allows custom forms via YAML to tailor these requirements, while also introducing an AI disclosure checkbox to track automated submissions. This shift moves security triage from manual parsing of vague text to structured data that can be programmatically reviewed or integrated into existing workflows.
GitHub Changelog
 © GitHub Changelog
Coding Toolsagents
GitHub Copilot adds desktop computer use
GitHub Copilot now controls your mouse and keyboard, bridging the gap between code generation and actual desktop automation. By leveraging accessibility APIs to read screens and click controls, it can navigate legacy GUI software that lacks APIs or CLIs. This moves AI from a coding assistant to an operational agent for tasks like expense reporting in Safari. You retain control with approval gates, but the ability to automate non-API workflows is a significant shift in utility.
GitHub Changelog
More in Coding Tools
Coding Toolscoding
Claude Code v2.1.286 patches security and session stability
Anthropic quietly fixed a critical credential leakage bug where MCP error messages were exposing raw API keys in plaintext logs. Beyond the security patch, this release stabilizes the notoriously fragile background agent system by fixing subagent hand-offs and connection stalls that previously caused silent failures. The update also tightens session management for cloud environments, ensuring large transcripts actually load instead of hanging indefinitely. It’s a maintenance-heavy release, but essential for anyone running complex, multi-step automated workflows.
Claude Code Releases
Coding Toolscoding
Claude Code v2.1.287 adds plugins and fixes
This update shifts Claude Code from a simple CLI wrapper to a more extensible platform by introducing 'Claude Mods,' allowing plugins to modify deeper behavior rather than just adding tools. The inclusion of a built-in 'You should know' side agent that flags potential oversights is a notable step toward autonomous oversight within the coding workflow. Beyond features, the release addresses critical stability issues in remote sessions and significantly improves accessibility for screen reader users, making the tool more robust for enterprise and diverse developer environments.
Claude Code Releases
Coding Toolscoding
vLLM v0.31.0rc3 adds Model Runner V2 dummy inputs
The v0.31.0rc3 release of vLLM brings a critical infrastructure tweak to the new Model Runner V2: support for randomized dummy inputs. This isn't a feature for end-users but a developer-facing fix that stabilizes how the runner handles initial tensor shapes during compilation and warm-up phases. By allowing randomized inputs, it reduces the likelihood of shape-mismatch errors when tracing models with dynamic dimensions. For builders running large-scale inference workloads, this means fewer silent failures and more robust model loading sequences in production environments.
vLLM Releases