Coding Tools
llama.cpp b10993 adds ROCm 10 and CUDA 13 builds
llama.cpp Releaseshigh confidence
Why it matters
- →ROCm 10 support allows AMD GPU users to run latest drivers without custom builds.
- →CUDA 13 binaries ensure compatibility with newest NVIDIA GPU architectures.
- →WebGPU CI integration signals progress toward browser-based local inference capabilities.
llama.cpp has released version b10993, expanding its pre-built binary support to include ROCm 10.0 and CUDA 13 libraries on Linux and Windows platforms. The update also integrates self-hosted WebGPU testing into the CI pipeline and adjusts CPU backend thread configurations for better stability. While no new model architectures or quantization techniques are introduced, this release ensures compatibility with recent GPU driver updates from both AMD and NVIDIA. The build remains focused on maintaining broad hardware support rather than introducing new features.
Read originalMore from llama.cpp Releases
Coding Toolscoding
llama.cpp fixes Metal NaN bug for large activations
A critical precision bug in llama.cpp’s Apple Silicon backend has been patched, resolving total inference failures on models with high-activation ranges like Mistral Small 4. The issue stemmed from f16 saturation during matrix multiplication, which turned entire output tensors into NaN values for inputs exceeding ~32 tokens. By implementing an exact, power-of-two rescaling mechanism in the Metal kernel, the fix restores correctness without significant performance penalties. This ensures local inference on M-series chips remains viable for complex MoE architectures that previously crashed.
llama.cpp Releases
Coding Toolscoding
llama.cpp b10995 Vulkan and ROCm updates
This release quietly improves inference stability on AMD GPUs by unconditionally enabling the BN/2 tail for MUL_MAT_ID operations in Vulkan. It also adds ROCm 10.0 builds for both Linux and Windows, keeping llama.cpp competitive with CUDA across hardware vendors. Apple Silicon KleidiAI builds are disabled here, likely due to regression testing, but the core CPU and NVIDIA paths remain robust. For local inference users, this means fewer edge-case crashes on AMD setups without needing custom compilation flags.
llama.cpp Releases
Models & Labscoding
llama.cpp b10996 adds CUDA 13 and ROCm 10.0 builds
This release quietly closes the hardware gap for local inference by adding native support for CUDA 13 and ROCm 10.0 across Linux and Windows. NVIDIA users can now leverage newer driver stacks without waiting for upstream updates, while AMD GPU owners finally get first-class ROCm 10 binaries that match the maturity of their CUDA counterparts. Apple Silicon builds remain available but KleidiAI is explicitly disabled here, suggesting a focus on stability over new kernel optimizations for this specific iteration. The inclusion of openEuler support for Huawei's Ascend chips further broadens the ecosystem beyond standard x86 and ARM consumer hardware.
llama.cpp Releases
More in Coding Tools
Coding Toolscoding
vLLM v0.29.0rc6 fixes hybrid model caching
This release candidate addresses a critical configuration gap for hybrid models in vLLM by enabling the dense prefix cache by default. Previously, these mixed-precision or multi-head architectures likely suffered from inefficient memory usage or required manual flags to achieve optimal performance. By automating this optimization, the update ensures that users running complex model topologies get better throughput out of the box without tweaking internal parameters. It is a quiet but necessary step toward making vLLM robust for heterogeneous hardware setups.
vLLM Releases
 © GitHub Changelog
Coding Toolscoding
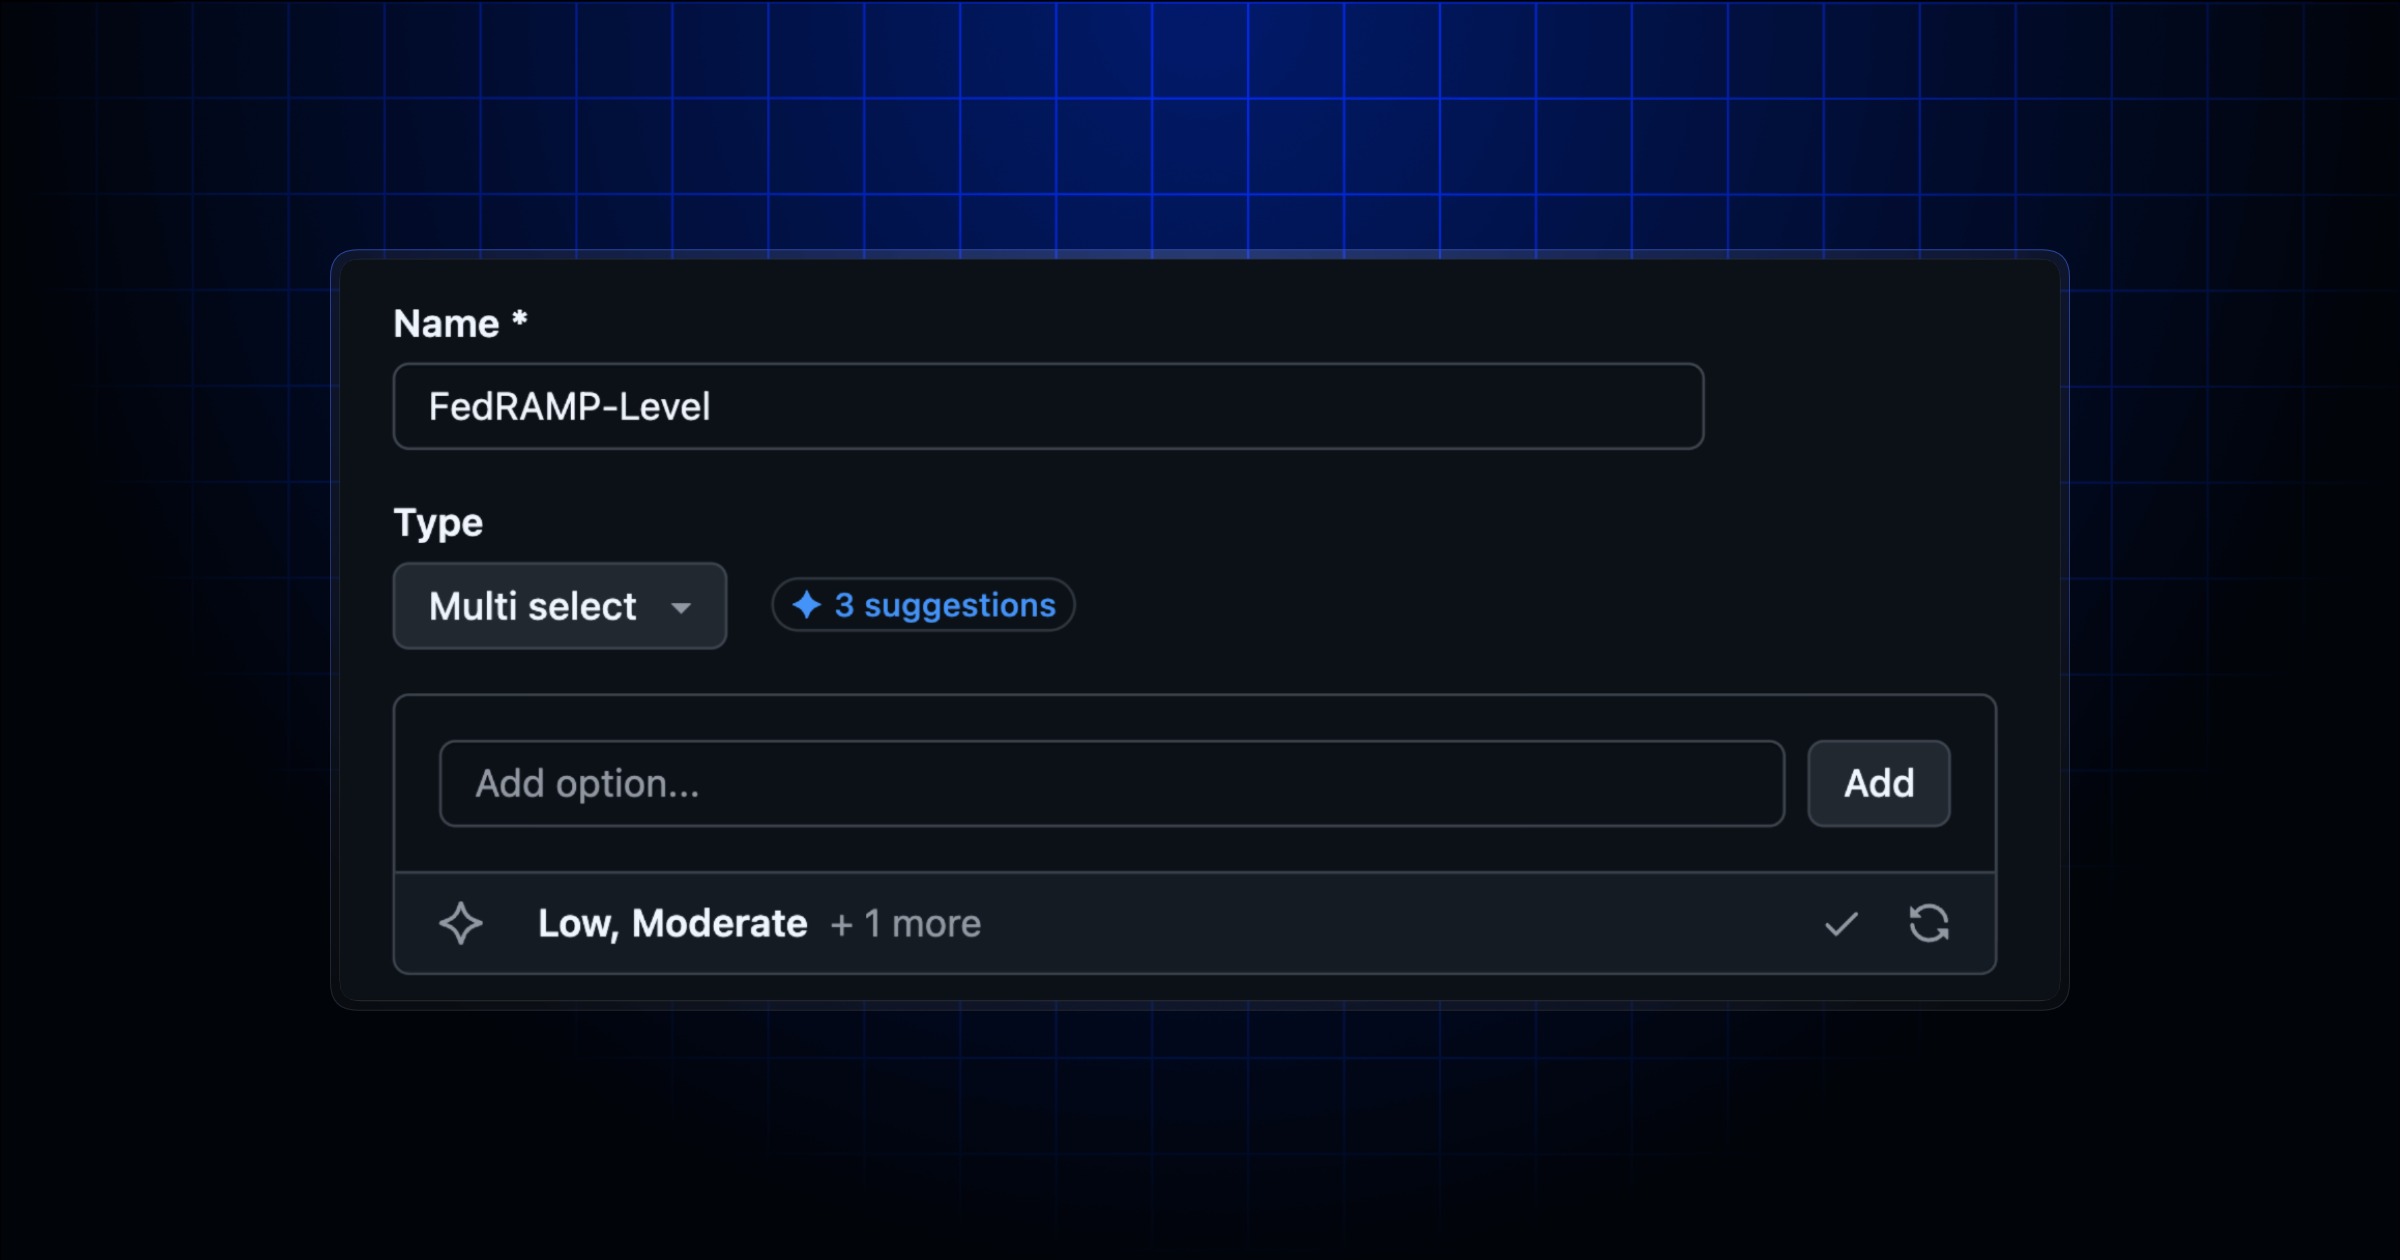
GitHub Copilot Enhances Custom Property Suggestions
GitHub Copilot is now assisting enterprise and organization admins by suggesting allowed values for custom properties in repositories. This feature, available in public preview for Copilot Business and Enterprise plans, tackles the issue of inconsistent metadata by offering relevant suggestions tailored to the property being defined. For example, when setting up a property like 'FedRAMP', Copilot proposes compliance-related values, making it easier to establish a consistent governance framework. This development accelerates the creation of custom property taxonomies, improving the application of governance rules across extensive repository collections.
GitHub Changelog
Coding Toolscoding
Claude Code v2.1.261 Update Released
The latest update to Claude Code, version 2.1.261, introduces several enhancements and fixes aimed at improving user experience and functionality. Notable changes include the addition of settings to increase command output limits and a new feature to identify unused skills, helping users optimize their setups. The update also addresses various bugs, such as character input issues and session management glitches, ensuring smoother operation across different environments. These improvements make Claude Code more robust and user-friendly, particularly for developers using it in complex workflows.
Claude Code Releases